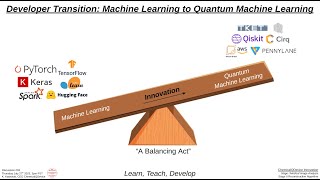
Developer Transition: Machine Learning to Quantum Machine Learning
Explore quantum machine learning frameworks, tools, and resources to transition from classical ML. Gain insights into QML algorithms, simulators, and future developments in the field.

Realtime Data Streaming - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using Apache Airflow, Kafka, Spark, and Cassandra. Learn end-to-end data engineering, from ingestion to processing and storage, all containerized with Docker.
Realtime Socket Streaming with Apache Spark - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using TCP/IP Socket, Apache Spark, OpenAI LLM, Kafka, and Elasticsearch. Process 7 million records for sentiment analysis and efficient data indexing.
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Building Robust Data Pipelines for Modern Data Engineering - End-to-End Project
Develop robust data pipelines using Apache Spark, Azure Databricks, and DBT. Master end-to-end data engineering with Azure, covering ingestion, integration, and transformation in a modern data architecture.
Realtime Streaming with Data Lakehouse - End-to-End Data Engineering Project
Design, implement, and maintain secure, scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Unlock data's potential through advanced analytics and machine learning.

Delta Live Tables: Building Reliable Data Pipelines with Databricks
Simplify ETL development with declarative pipelines, automatic testing, and deep visibility for reliable batch and streaming data on Databricks Lakehouse Platform.

Microsoft Fabric Overview - Features, Benefits, and Use Cases
Explore Microsoft Fabric's powerful features for organizational data management, including OneLake, lakehouses, warehouses, and AI integration. Learn key benefits and use cases for data engineering and analysis.
Elevating Kubeflow Spark Operator's Future: Best Practices and Enhancements
Discover advanced techniques for deploying Apache Spark on Kubernetes using Kubeflow Spark Operator, covering scaling strategies, multi-tenancy management, security best practices, and efficient upgrade procedures.
Design Patterns for Running AI/ML and Big Data Workloads on Kubernetes
Explore essential design patterns and solutions for deploying AI/ML and big data workloads on Kubernetes, addressing challenges in container management, data handling, and system optimization.
Apache Gluten - Boosting Apache Spark Performance with Native Engines
Discover how Apache Gluten enhances Spark performance through native engine integration, optimizing data processing and analysis capabilities for improved efficiency.
Meituan's Journey with Apache Spark and Gluten
Discover how Meituan optimizes data processing with Apache Spark and Gluten, exploring performance improvements and real-world implementation strategies for large-scale data analysis.
How to Build a Cloud Native Data Lake with Open Source Technologies
Discover how to deploy a Kubernetes-based data lake using open source tools, from initial setup to running a complete prototype platform on your local machine.
Object Storage Is All You Need - From Cloud Persistence to Modern Applications
Explore how object storage is evolving from simple web storage to a complete persistence solution, examining its benefits, performance aspects, and practical applications in modern cloud systems.
Building Production-Ready Data Applications with Databricks Asset Bundles - Cookies Dataset Analysis
Master real-time analytics and streaming data applications using Databricks Asset Bundles, featuring hands-on experience with the Bakehouse application and AI-powered store location optimization.
Understanding Apache Spark Services and Concepts - Lesson 40
Gain insights into Apache Spark's core services, features, and architecture, demystifying its components and understanding the platform's strategic direction and trends.

التقنية بإتقان | Hatem Gabr | TEDxYouth@TabaryElHegazHS
مع باشمهندس حاتم جبر، نستكشف عالم الذكاء الاصطناعي: مجالاته المتنوعة، دراسات حقيقية، واستثمارات تتجاوز 15 مليار دولار بحلول عام 2030. نعرف كيف يمكن للـ AI أن يكون أداة فعّالة تكمل عمل الإنسان، مع من حيث أنه يتطلب استخداماً واعياً وبيانات دقيقة Hatem Gabr is a Digital Transformation leader with over