Diamond Architecture on Scala 3 - Managing Large Codebases
Explore Diamond Architecture in Scala 3 for managing large codebases. Learn OOP techniques, modular approaches, and new Scala 3 features to build maintainable applications.
Running Remote Shuffle Service to Solve Apache Spark's Dynamic Resource Allocation Challenge on Kubernetes
探讨利用远程洗牌服务解决Apache Spark在Kubernetes上的动态资源分配挑战,实现存储与计算解耦,提高大数据处理的可靠性和可扩展性。
Crea tu Propio Laboratorio de Big Data con MicroK8s y Spark
Aprende a crear un laboratorio de Big Data utilizando Spark y MicroK8s. Descubre cómo emular una arquitectura de datos y practica habilidades esenciales para el análisis de grandes volúmenes de información.
Bytedance's Parquet Format Optimization for Cost Reduction and Efficiency
Optimize Parquet file operations for big data efficiency. Learn binary copy techniques to enhance file overwriting, merge small files, and implement column-level TTL, boosting performance 10+ times.
Accelerating Real-Time Video Analytics on a Heterogeneous CPU and FPGA Platform
Explore real-time video analytics acceleration using CPU+FPGA platforms. Learn about performance optimization, latency reduction, and cost-effective solutions for industrial applications like fraud detection and surveillance.
Scaling Security Threat Detection with Apache Spark and Databricks
Explore advanced security threat detection using Apache Spark and Databricks. Learn about innovative solutions for notebook-based testing, self-tuning alerts, automated investigations, and custom SDK development for enhanced cybersecurity.
Data Privacy Techniques with Apache Spark - Defensive and Offensive Approaches
Explore data privacy techniques for Apache Spark, including offensive and defensive approaches, k-anonymity, and quasi-identifiers. Learn implementation strategies and how Databricks Delta enhances dataset privacy.
Scaling Privacy in a Spark Ecosystem
Learn strategies for scaling privacy in Spark ecosystems, balancing customer rights with business needs. Explore centralized access control, auditing, and reporting in open data environments.
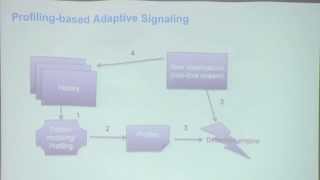
Devil in the Haystack - Application Security Through Statistical Analysis and Machine Learning
Exploring statistical and machine learning techniques for in-app security at Salesforce. Focuses on adaptive, data-driven approaches for detecting and preventing attacks and abuses on the platform.
Building a Flourishing Technical Community - Lessons from Delta Lake
Discover key strategies for building and growing a thriving technical community, focusing on developer engagement, branding, collaboration, and effective management with Linux Foundation partnership.
Becoming GDPR and CCPA Compliant Using Delta Live Tables
Explore solutions for implementing "Right to be Forgotten" in data lakehouses using Delta Live Tables, ensuring compliance with GDPR and CCPA privacy regulations.
Ensuring GDPR Compliance for Real-Time Data Pipelines
Strategies for GDPR compliance in real-time data pipelines using Databricks tools. Covers immediate solutions with Delta Lake's CDF and long-term plans for PII separation, offering practical privacy compliance approaches.
Unlocking Scalable and Efficient Data Storage with Apache Ozone
Discover how Apache Ozone revolutionizes distributed object storage, offering scalable solutions for managing massive data volumes while ensuring reliability, cost-effectiveness, and seamless integration with Hadoop ecosystem.
State of the Art Natural Language Understanding at Scale - David Talby
Explore state-of-the-art NLP techniques using Apache Spark, covering core algorithms, distributed pipelines, and performance optimizations for large-scale language understanding applications.
How Companies Are Using Tachyon, a Memory Centric Distributed Storage
Explore Tachyon, a memory-centric distributed storage system for fast big data processing. Learn about its benefits, use cases, and integration with popular frameworks like Spark and Hadoop.
Funnel Analysis with Apache Spark and Druid for Advertising Campaign Effectiveness
Learn to perform funnel analysis at scale using Apache Spark, Druid, and DataSketches. Discover techniques for measuring campaign effectiveness and analyzing user behavior in chronological order for large-scale advertising campaigns.
Degrading Performance - Understanding and Solving Small Files Syndrome
Learn how small files impact data pipeline performance, understand cloud storage and Apache Spark interactions, and discover DeltaLake solutions for improved efficiency in handling massive datasets.
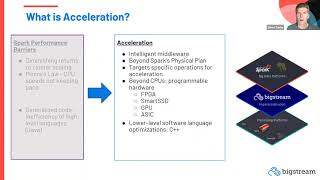
Turbocharging Spark with Samsung SmartSSD Computational Storage Devices
Discover how Samsung SmartSSD® with Xilinx FPGAs accelerates Spark, offering 2x-8x performance gains without code changes. Learn about the technology, benchmarks, and TCO savings.
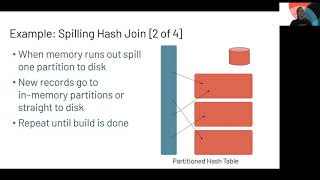
Photon: Accelerating SQL Queries on Databricks Lakehouse Platform
Explore Photon, a C++ component for efficient query execution in Databricks Lakehouse. Learn about its vectorized processing, compatibility with Apache Spark, and performance enhancements for data-driven decision-making.
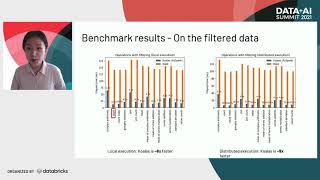
Koalas: Scaling Pandas APIs on Apache Spark - Performance and Comparison with Dask
Explore Koalas: pandas-like APIs for big data on Apache Spark. Compare performance with Dask, learn about recent updates, and understand its scalability for data science tasks.
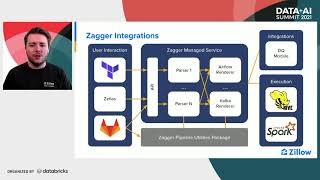
Empowering Developers with Self-Service ETL - Zillow's Approach
Zillow's self-service ETL solutions empower teams to build, maintain, and monitor data pipelines, abstracting complex processes and catering to diverse user needs while leveraging internal services for efficient implementation.