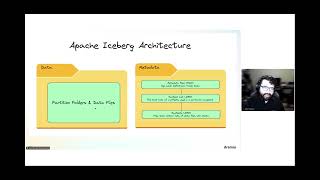
The Who, What, and Why of Data Lake Table Formats
Explore data lake table formats, their creators, purposes, and significance in modern data architecture. Gain insights into optimizing data management and analytics.
Tech Talk - Top Tuning Tips for Spark 3.0 and Delta Lake on Databricks
Learn top tuning tips for Apache Spark 3.0 and Delta Lake on Databricks. Discover optimal join strategies, machine sizing, merge operation speedups, and job simplification techniques for enhanced big data processing.
Building a Flourishing Technical Community - Lessons from Delta Lake
Discover key strategies for building and growing a thriving technical community, focusing on developer engagement, branding, collaboration, and effective management with Linux Foundation partnership.
Becoming GDPR and CCPA Compliant Using Delta Live Tables
Explore solutions for implementing "Right to be Forgotten" in data lakehouses using Delta Live Tables, ensuring compliance with GDPR and CCPA privacy regulations.
Ensuring GDPR Compliance for Real-Time Data Pipelines
Strategies for GDPR compliance in real-time data pipelines using Databricks tools. Covers immediate solutions with Delta Lake's CDF and long-term plans for PII separation, offering practical privacy compliance approaches.
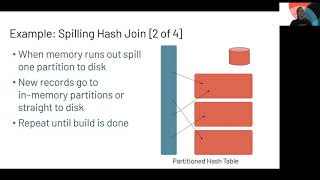
Photon: Accelerating SQL Queries on Databricks Lakehouse Platform
Explore Photon, a C++ component for efficient query execution in Databricks Lakehouse. Learn about its vectorized processing, compatibility with Apache Spark, and performance enhancements for data-driven decision-making.
Growing the Delta Ecosystem - Delta-RS for Rust and Python
Explore delta-rs, a Rust library extending Delta Lake beyond Spark. Learn its current capabilities, roadmap, and real-world application in kafka-delta-ingest for high-throughput data transfer.
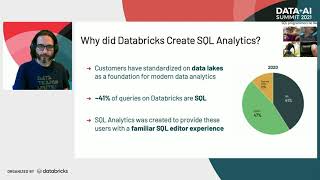
Building Lakehouses on Delta Lake with SQL Analytics
Learn to build lakehouses using Delta Lake, perform SQL analytics, and connect BI tools. Explore data management techniques, governance models, and implementation examples for efficient data processing and analysis.
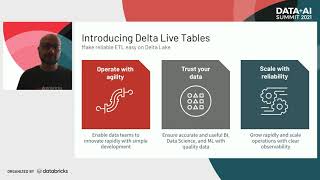
Make Reliable ETL Easy on Delta Lake
Learn to simplify ETL development on Delta Lake, improving data quality and scaling operations. Discover how Databricks streamlines the ETL lifecycle for efficient data engineering and management.
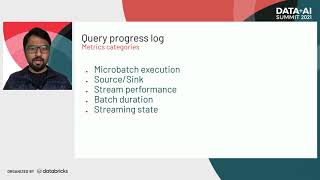
Delta Lake Streaming - Internals and Query Progress Logs
Explore Delta Lake streaming internals, focusing on structured streaming components, Query Progress Logs, and checkpoint directories for efficient real-time data pipeline management.
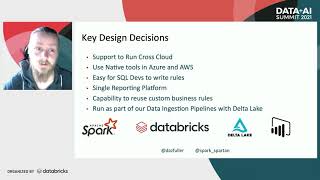
Building Data Quality Pipelines with Apache Spark and Delta Lake
Learn to build robust data quality pipelines using Apache Spark and Delta Lake. Explore rule templates, reporting models, and PowerBI integration for effective data remediation and self-healing in enterprise environments.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Creating a Lakehouse on AWS
Learn to build a Lakehouse on AWS, combining data lake affordability with data warehouse performance. Discover integration with AWS services and real-world examples of high-performance, cost-effective analytics solutions.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.
Boost Delta Lake Performance with Data Skipping and Z-Order
Explore data skipping and Z-ordering techniques to enhance Delta Lake performance, focusing on optimized partitioning strategies for improved read and write efficiency in large-scale data lakes.
How Apache Spark 3.0 and Delta Lake Enhance Data Lake Reliability
Discover performance enhancements in Apache Spark 3.0 and Delta Lake's data reliability features. Learn about Adaptive Query Execution, Dynamic Partition Pruning, and handling skewed queries for improved big data processing.
Engagement Activity Delta Lake for Einstein Analytics and Sales Cloud Einstein
Explore how Salesforce built an engagement activity platform using Delta Lake to support Einstein Analytics and Sales Cloud Einstein, covering data ingestion, incremental reads, and mutation handling.
Delta Lake: Optimizing Merge Operations
Explore Delta Lake merge optimization techniques, including inner and full outer joins, partition pruning, and file pruning. Learn tips for handling large merges efficiently.
Building a Cloud Data Lake with Databricks and AWS - Best Practices and Implementation
Explore building a cloud data lake using Databricks and AWS. Learn about data lake architecture, AWS services, Delta Lake for reliability and performance, and best practices for implementation.
Leveraging Apache Spark and Delta Lake for Efficient Data Encryption at Scale
Efficient data encryption solution for privacy compliance using Apache Spark and Delta Lake. Automates consumer deletion requests, enhances security, and maintains data integrity while ensuring accessibility when needed.
Common Strategies for Improving Performance on Delta Lakehouse
Explore techniques to enhance Delta Lakehouse query performance, including data skipping, optimizing Z-Order, SQL partitions, and Delta Cache. Learn to analyze and tune queries for better results.