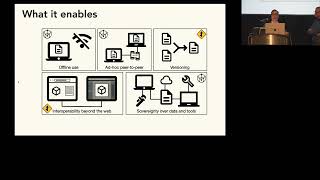
MyWebstrates - Building Local-first Software with Webstrates
Discover how Webstrates technology enables local-first software development, combining web-based collaboration with offline capabilities and data sovereignty in modern applications.
GitOps at Production Scale with Flux - Scaling Best Practices and Benchmarking
Discover scaling strategies for Flux controllers in production environments, covering vertical and horizontal scaling methods, sharding techniques, and performance benchmarking for efficient GitOps implementation.
Kubernetes SIG Architecture Introduction and Design Principles
Discover how Kubernetes SIG Architecture maintains design principles, API conventions, and architectural consistency while exploring its key roles, subprojects, and latest community developments.
Scaling and Safeguarding the Heart of Kubernetes: Deep Dive Into etcd
Dive into etcd development efforts, exploring feature gates, operator working group progress, compaction correctness, and community updates for enhanced Kubernetes cluster management and scalability.
Introduction to Cortex - Multi-Tenant Scalable Prometheus Architecture
Discover how Cortex enables scalable, multi-tenant Prometheus monitoring with long-term storage capabilities, exploring its architecture, features, and production implementation strategies.

Multi-Zone Clusters Inside and Out - Understanding Topology Aware Routing and Cost Management
Dive into the mechanics of multi-zone Kubernetes clusters, exploring topology-aware routing, cost management strategies, and practical implementation techniques through live demonstrations.
Navigating Failures in Pods with Devices: Challenges and Solutions
Explore common challenges and solutions for managing device-enabled pods in Kubernetes, focusing on GPU allocation, network cards, and memory placement for AI/ML workloads.
Pod Power: Liberating Kubernetes Users from Container Resource Micromanagement
Discover how to optimize Kubernetes resource management through pod-level specifications, moving beyond container-level controls for better flexibility and resource utilization in complex applications.
Mastering Cell-Based Architecture: Practical Solutions and Best Practices
Discover practical solutions for implementing cell-based architecture, from defining enterprise-wide boundaries to managing greenfield and brownfield implementations, with real-world examples and comprehensive best practices.
Per-Node API Server Proxy - Expanding Cluster Scale and Stability
Discover how to optimize API server communication in Kubernetes clusters using per-node proxies, improving scalability and reducing network load through efficient data synchronization techniques.
Lessons Learned Adopting OpenTelemetry at Scale
Discover practical strategies and real-world insights for implementing OpenTelemetry in complex enterprise environments through Heroku's journey, including adoption challenges, technical guidance, and success factors.
Cash App's Journey Into a Multi-Cluster Kubernetes Ecosystem
Discover how Cash App implemented multi-cluster Kubernetes architecture to enhance reliability, enable seamless service migrations, and streamline maintenance processes for improved system resilience.
All Your GPUs Are Belong to Us: An Inside Look at NVIDIA's Self-Healing GeForce NOW Infrastructure
Discover how NVIDIA manages GeForce NOW's massive GPU infrastructure using Kubernetes, exploring automated maintenance systems and self-healing operators that keep the game streaming platform running for millions of users.
Cooperative Scheduling for Stateful Systems in Kubernetes
Discover how LinkedIn manages stateful systems in Kubernetes through LiStatefulSet API, enabling customized safety checks and deployment policies while maintaining system availability and data durability.
Engineering a Kubernetes Operator - Lessons Learned from Versions 1 to 5
Discover the evolution of Kubernetes Operator development through 5 versions of a Postgres implementation, exploring architectural decisions, design patterns, and practical strategies for building robust operators.

Nothing but NATS - Building Cloud-to-Edge Native Applications
Discover how NATS simplifies cloud-to-edge native app development by eliminating complex tool stacks while enabling powerful distributed systems with minimal code and effort.
Bloomberg's Journey to Manage Multi-Cluster Training Applications with Karmada
Discover how Bloomberg leverages Karmada to manage multi-cluster GPU workloads, optimize resource utilization, and streamline AI model training across data centers with intelligent scheduling and high availability.
Platform Engineering for Software Developers and Architects
Explore platform engineering principles and their impact on software architecture, focusing on effective platform design, SDLC integration, and key metrics for measuring developer experience.
The Key Value of etcd Over Custom Resources - Scaling Cilium in Large Kubernetes Clusters
Discover how using dedicated etcd instances can enhance Cilium's scalability in large Kubernetes clusters, exploring direct etcd API interaction and performance optimization techniques.
Migratory Patterns - Making Architectural Transitions with Confidence and Grace
Discover proven strategies for seamless database migrations and architectural transitions using CNCF standards, featuring real-world examples of zero-downtime implementations and risk mitigation techniques.
Zero Downtime Upgrades at Scale: How Okta Manages Hundreds of Clusters Daily
Discover how to achieve zero-downtime Kubernetes cluster upgrades at scale, focusing on deployment methods, canary rollouts, and quick rollbacks while managing hundreds of clusters with 130+ services each.