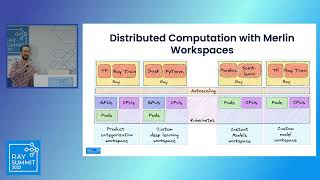
The Magic of Merlin - Shopify's New Machine Learning Platform
Explore Shopify's Merlin ML platform, its open-source stack, architecture, and how it scales ML work using Ray.
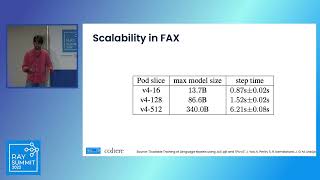
Scalable Training of Language Models Using Ray, JAX, and TPUv4
Explore challenges and design decisions for scalable language model training, with quantitative analysis of efficiency improvements using Ray, JAX pjit, and TPUv4.
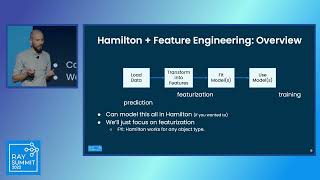
Scalable Feature Engineering with Hamilton on Ray
Explore scalable feature engineering using Hamilton and Ray at StitchFix. Learn declarative dataflow, team scaling, and efficient computation for thousands of time-series features.
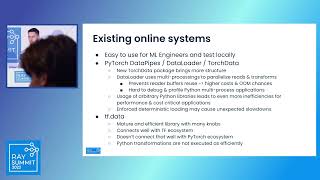
Cruise.data - A New Dataset Processing Pipeline for Cruise ML
Explore Cruise.data, a novel ML data pre-processing framework combining tf.data, PyTorch, and large-scale processing capabilities for efficient and scalable dataset handling in autonomous vehicle development.
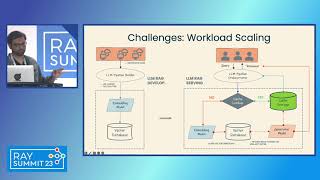
Enterprise Vector-based Information Retrieval and Prompt Engineering at Scale Using Open Source on AWS
Build enterprise-scale vector-based information retrieval systems using open source technologies on AWS, addressing challenges in Retrieval Augmented Generation for accurate, hallucination-free results.
Easily Scale to Production-Ready Generative AI with NVIDIA and Anyscale
Scale generative AI to production with NVIDIA and Anyscale's partnership. Learn how their combined technologies optimize performance, lower costs, and enable secure deployment of AI services at scale.
Best Practices for Productionizing Distributed Training with Ray Train
Explore fault-tolerant distributed training techniques using Ray Train, covering experiment restoration, node failure recovery, cloud storage snapshots, and large model checkpointing for efficient AI workloads.
A Ray-based ML Platform for Early Cancer Detection
Explore how Ray enhances scalability and efficiency in machine learning for early cancer detection, focusing on improved model development and evaluation for potential diagnostic applications.
Fast and Scalable Model Training with PyTorch and Ray
Learn distributed model training with PyTorch and Ray. Migrate code, scale AI workflows, and optimize performance for large-scale training and fine-tuning on Anyscale.
Scalable and Cost-Efficient AI Workloads with AWS and Anyscale
Learn to scale and productionize GenAI and LLM workloads cost-effectively using AWS compute instances and Anyscale's capabilities for ambitious AI projects.
How Flow Works in Software Engineering - Insights from Complexity Science
Explore how information theory and complexity science illuminate software engineering practices, optimizing value flow and challenging conventional approaches to development.
Challenges in ML Engineering
Explore challenges in ML engineering, including cost-efficient inference, automation, accuracy monitoring, and anomaly detection for real-world AI applications.
Scalable and Flexible Distributed Reinforcement Learning Systems
Explore scalable distributed reinforcement learning systems, focusing on flexible training loops, statement management, and GPU allocation. Gain insights into building efficient RLHF systems for large-scale applications.
From Two Strong Oxen to Billions of Fleas - The Evolution of Massively Parallel Distributed Supercomputers
Explore massively parallel distributed supercomputers, focusing on distributed-memory parallelism and RDMA through MPI. Gain insights into current designs and future challenges in high-performance computing.
HammingMesh: A Network Topology for Large-Scale Deep Learning
Explore a novel network topology for large-scale deep learning systems, enhancing data movement efficiency and job scheduling flexibility for future AI training infrastructure.

Harnessing Proprietary Data in the Era of Generative AI - Insights from AWS
Explore AWS's mission to democratize machine learning, offering customization capabilities for proprietary data. Learn about security, data governance, and scalable GenAI development for startups building innovative AI solutions.
My Plan B: Exploring Alternative Strategies in Computer Science Research
Explore innovative approaches to software testing and verification with Professor Alastair Donaldson in his Imperial Inaugural lecture.

Linus Torvalds on Linux and Git Development - Keynote Conversation
Gain insights from Linux creator Linus Torvalds as he discusses open-source development, technology trends, and his experiences in a candid conversation with Dirk Hohndel.
Detecting and Overcoming GPU Failures During ML Training
Explore GPU failure challenges in ML training, learn proactive detection methods, and discover fault-tolerant distributed training principles to mitigate issues and optimize performance.
A New Choice for Istio Data Plane: Architectural Innovation for Brand-New Performance
Explore innovative Istio data plane solution using eBPF and kernel enhancements for native traffic governance, reducing latency by 60%+ and simplifying mesh architecture. Discuss future service mesh evolution.
Revolutionizing Service Mesh with Kernel-Native Sidecarless Architecture
Explore innovative kernel-native sidecarless service mesh solutions to optimize resource management, reduce latency, and enhance microservice governance in expanding clusters.