Bulletproof Transient Error Handling with Polly
Learn to handle network interruptions and transient errors in connected applications using Polly, an open-source library. Explore retry policies and circuit breaker patterns for robust system design.
Quality Control and Non-Destructive Inspection Using the Multinomial Distribution
Explore quality control principles through multinomial distribution, learning to assess batch reliability using non-destructive inspection methods and statistical sampling techniques.
Material Compatibility Evaluation of High-power Interconnects for Single-phase Immersion Cooling
Explore material compatibility testing for high-power interconnects in single-phase immersion cooling, covering exposure tests, chemical considerations, and reliability evaluation methods.
Liquid Cooling When Component Failure is Not an Option
Explore cutting-edge liquid cooling solutions for critical computing components, focusing on reliability and failure prevention in high-performance systems.
Interconnect Design Optimization and Predictive Reliability Models for Immersion Cooling Technology
Explore design optimization strategies for interconnect solutions in immersion cooling systems, focusing on reliability testing, failure modes, and performance enhancements for long-term durability.
Liquid Cooling Reliability in High-Performance Computing Systems
Dive into reliability engineering for liquid cooling systems in AI infrastructure, focusing on component-level analysis, predictive techniques, and failure prevention mechanisms.
CAST-Based Analysis for Software Incident Investigations and Retrospectives
Discover how to conduct effective incident investigations using CAST methodology, focusing on software reliability engineering and systematic analysis of system failures.
Resilient Systems and Teams - A CTO's Blueprint for SRE Excellence
Discover a CTO's blueprint for building resilient systems and teams, covering SRE implementation, on-call strategies, and effective communication for startups and growing organizations.
Unknown Unknowns and Chaos - Introduction to Security Chaos Engineering
Explore Security Chaos Engineering's focus on "unknown unknowns" in cloud-native systems. Learn proactive security testing techniques and build resilient cyber defenses against unforeseen threats.
Reduce Cloud Cost and Increase Reliability via Accurate Resource Recommendations
Optimize Kubernetes resource allocation using open-source tools. Learn to set accurate requests and limits, improving utilization, cost-efficiency, and reliability in your clusters.

Monitoring Cloud Run Applications: From Basic to Custom Metrics
Learn to monitor Cloud Run apps effectively. Set up basic monitoring quickly, create custom metrics for in-depth analysis, and improve application reliability through practical demonstrations.
Kraken: A Tool for Chaos Engineering in Kubernetes Environments
Explore Kraken, an open-source chaos testing framework for Kubernetes. Learn to inject failures, analyze recovery, and improve system reliability through practical demonstrations.
Scaling Reliability Engineering with Tools
Explore strategies for scaling reliability engineering, including tool development, decision-making processes, and real-world examples of automated failover and chaos engineering implementations.
Chaos Engineering - Why Breaking Things Should be Practiced
Explore chaos engineering to build resilient systems by simulating failures. Learn how to uncover hidden issues and improve application performance through controlled disruptions.
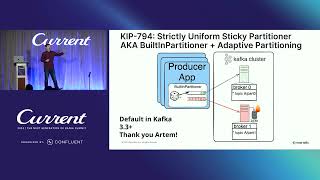
Mitigating Kafka Broker 'Gray' Failures for Key-Based Partitioners with Partition Multihoming
Explore partition multihoming (PMH) to mitigate Kafka broker gray failures, enhancing reliability for key-based partitioning. Learn implementation details, workflow, and future roadmap for virtual partitioning in Apache Kafka.
Building Event-Driven Systems - From Fundamentals to Advanced Integration Patterns
Discover practical insights into building event-driven architectures, from fundamental concepts to advanced integration patterns, enhancing system resilience, extensibility, and scalability in real-world applications.
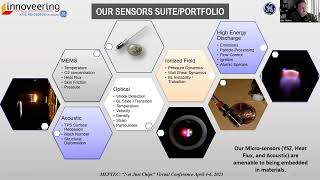
Packaging of Sensors for High Reliability, Survival and Performance in Extreme Environments
Explore sensor packaging design challenges for extreme aerospace environments, focusing on MEMS integration, material selection, and reliability testing for hypersonic applications.
Formal Verification of a Mechanical Ventilator Using UPPAAL
Explore formal verification of mechanical ventilators using UPPAAL, enhancing system reliability and correctness through advanced modeling techniques.
War Games - Prepare for the Unexpected in Chaos Engineering
Explore chaos engineering war games to enhance system resilience. Learn strategies for stakeholder engagement, tabletop exercises, and environment-based simulations to prepare for unexpected scenarios.
Just Don't Do It - Databases in Kubernetes
Explore challenges and best practices for running databases in Kubernetes, focusing on PostgreSQL's transformative potential and the shift from availability to reliability in cloud-native environments.
Monkey Business for Serious Systems: Why Chaos Engineering Isn't Crazy
Explore chaos engineering's role in uncovering system vulnerabilities and enhancing resilience. Learn to simulate real-world failures, identify weaknesses, and build robust infrastructures.