Growing a Lab for Automated Upstream Testing: Challenges and Lessons Learned
Explore challenges and solutions in scaling a large-scale automated testing lab, focusing on device management, reliability, and continuous monitoring for open source projects.
How Testability Drives Observability
Explore the crucial link between testability and observability in software development, enhancing system reliability and performance monitoring capabilities.
Scale, Resilience, and Efficiency in Cloud Environments - Lessons from Okta
Upgrading a private cloud environment for higher scale, resilience, and efficiency. Practical advice for developers on zero-downtime upgrades and infrastructure optimization.
Serverless Resilience - Building a Reliable Serverless Platform
Learn to build reliable serverless platforms using Chaos Engineering. Discover best practices for improving availability and performance in systems like Knative, addressing systemic failures proactively.
Make Cloud Native Chaos Engineering Easier - Deep Dive into Chaos Mesh
Explore Chaos Mesh, a popular open-source platform for cloud native chaos engineering. Learn implementation, best practices, and how to enhance observability in chaos experiments for improved efficiency.
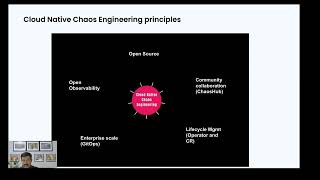
Cloud Native Chaos Engineering Preview with LitmusChaos
Explore cloud native chaos engineering using LitmusChaos, a powerful tool for enhancing system resilience and uncovering potential vulnerabilities in Kubernetes environments.
Cloud Native Live - Litmus Chaos Engine and Microservices Demo App
Explore Litmus Chaos Engine for resilience testing in microservices, featuring a hands-on demo application to enhance cloud-native development skills.
Chaos Engineering with LitmusChaos - Project Update
Explore the latest advancements in Chaos Engineering using LitmusChaos, a powerful tool for enhancing system resilience and reliability in cloud-native environments.
Chaos Engineering in Action - Building Fault-Tolerant Systems
Explore chaos engineering principles and practices to build resilient systems. Learn to plan, execute, and analyze experiments for improving fault tolerance and system reliability.
Bell the "Chaotic Cat" with Site Reliability Engineering
Explore SRE practices for managing unpredictable systems using the "Chaotic Cat" analogy, enhancing reliability and resilience in complex environments.
Reliability in the Face of Uncertainty - Chaos Engineering 2023
Explore strategies for building reliable systems in uncertain environments, focusing on chaos engineering principles and practical implementation techniques.
Introduction to Litmus Chaos - Getting Started with Cloud-Native Chaos Engineering
Comprehensive introduction to Litmus Chaos, covering its fundamentals, installation, and practical demonstrations of chaos experiments on Kubernetes, including a Kafka scenario.
Latency SLOs Done Right - Calculating and Setting Accurate Service Level Objectives
Explore accurate latency SLO calculation methods, including histogram-based approaches, to set mathematically correct quantiles and improve service level objectives for better monitoring and performance management.
Chaos Engineering for Hybrid Targets with LitmusChaos
Explore vendor-agnostic chaos engineering for multi-cloud deployments using LitmusChaos. Learn to integrate continuous chaos testing in CI/CD pipelines and manage experiments from a Kubernetes control plane.
Chaos Engineering 2023 with Chaos Mesh
Explore Chaos Engineering principles and Chaos Mesh platform to improve system resilience. Learn to configure experiments, identify vulnerabilities, and enhance overall reliability through practical demonstrations.
What's New in Chaos Mesh and Deep Dive into Multi-Cluster Support
Explore Chaos Mesh's latest features, including multi-cluster support for chaos experiments. Learn about design, implementation, and real-world applications in this comprehensive update on the popular chaos engineering platform.
Building Resilience with Chaos Engineering
Explore chaos engineering techniques to build resilient systems, increase developer productivity, and ensure continuous resilience in cloud-native environments.
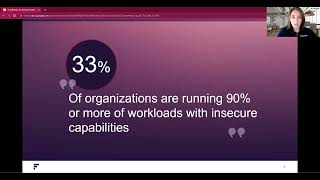
Kubernetes Benchmark Report 2023 - What's Working and What's Not
Explore key findings from the 2023 Kubernetes Benchmark Report, covering reliability, security, and efficiency in cloud-native environments.
Create Chaos Experiments Using Litmus-SDK
Learn to design and implement chaos experiments using Litmus-SDK, enhancing system resilience and uncovering potential vulnerabilities in your infrastructure.
Monitoring for File System Errors in Data Centers - A Guardian Angel Approach
Explore advanced techniques for monitoring and detecting file system errors in data centers, enhancing reliability and preventing data loss.
Beyond the Monkeys - Chaos Engineering on the Cloud
Explore chaos engineering in cloud environments, focusing on decentralized approaches, experiment design, and practical implementation strategies for improved system resilience.