Panel Discussion - Enabling Linux in Safety Applications
Explore the integration of Linux in safety-critical applications with industry experts, discussing challenges, opportunities, and best practices for secure and reliable implementations.
Better Reliability with Service Level Objectives (SLOs) - Defining and Implementing SLIs
Learn to define and implement Service Level Objectives (SLOs) effectively, including choosing indicators, setting agreements, and discussing realistic availability for improved reliability.
Scaling Kubernetes Networking to 1k, 5k, and 100k Nodes
Explore best practices for scaling Kubernetes networking with Cilium, comparing single large clusters vs. multiple smaller clusters. Learn configuration, monitoring, and reliability strategies for massive deployments.
Why NAND Flash Breaks Down - Tutorial
Explore NAND flash reliability, cell operations, fault mechanisms, and mitigation strategies. Gain insights into future developments in embedded systems storage technology.
Software-Defined Infrastructure at Uber Scale
Explore Uber's software-defined infrastructure, focusing on global network engineering, automation, and performance optimization for massive-scale operations and peak efficiency.
Using External Persistent Volumes for High Availability on DC/OS
Explore strategies for reducing recovery times and achieving high availability in DC/OS using external persistent volumes, focusing on distributed applications like Cassandra and HDFS.
Fast Recovery of Container Failures at Large Scale - The 1-5-10 Approach
Explore Alibaba's 1-5-10 theory for rapid container failure recovery at scale, covering efficient detection, intelligent diagnosis, and automated problem resolution techniques.
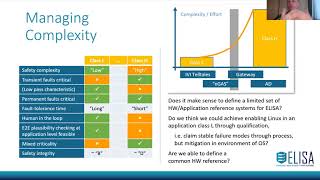
Designing, Configuring and Verifying Linux Systems for High Quality and Fault Mitigation
Explore techniques for creating robust Linux systems with high quality and fault mitigation, focusing on design, configuration, and verification methods used in the LF ELISA project.
Digital Twinning with Ansible and Cloud-Init for Destructive Infrastructure Testing
Explore innovative techniques for infrastructure testing using digital twinning, Ansible, and cloud-init to enhance system reliability and performance in cloud environments.
The Forefront of NVDIMM Development on Linux Kernel
Explore cutting-edge developments in NVDIMM technology for Linux kernels, focusing on recent advancements and future directions in non-volatile memory integration and optimization.
SLIs, SLAs, and SLOs - Learning About Service Uptime from Homer Simpson
Explore service uptime concepts through Homer Simpson's lens. Learn about SLIs, SLAs, and SLOs in a fun, engaging way to improve your understanding of system reliability.
Safety, Security, Quality - Artificial Intelligence versus Common Sense
Explore AI's impact on safety, security, and quality in infrastructure, comparing it with traditional approaches and discussing community collaboration and effort estimation.
9 Things You Should Do When Starting to Use SLOs
Practical guidance on implementing Service Level Objectives (SLOs) effectively, addressing common challenges and maximizing their value in enhancing service reliability and organizational culture.
Managing CI Across Multiple Farms for GPU Testing - Lecture 1
Explore challenges and solutions for managing CI across diverse farms and devices, focusing on Mesa3D infrastructure and optimizing performance for large-scale projects.
Graceful Degradation: When All Goes Wrong - Chaos Engineering 2023
Explore strategies for graceful degradation in systems when faced with failures, ensuring resilience and maintaining core functionality.
Chaos Engineering
Descubre cómo la ingeniería del caos mejora la resiliencia de sistemas mediante experimentos controlados. Aprende a implementar un cookbook de recetas para construir pruebas de caos en entornos de producción.
Watering the Roots of Resilience - Learning from Failure with Decision Trees
Explore how SREs can align mental models with system reality using resilience stress testing and decision trees. Learn practical tools for documenting, visualizing, and improving complex software systems.
Distri: Researching Fast Linux Package Management - Arch Conf 2020
Exploring innovative approaches to accelerate Linux package management, focusing on distri's architecture, SquashFS images, and system-wide implications for faster and more robust package handling.
Diocletian, Constantine, Bedouin Sayings, and Network Defense
Explore ancient Roman military strategies and their surprising parallels to modern network defense, offering innovative approaches to cybersecurity challenges.

Architectural Patterns of Resilient Distributed Systems
Explore architectural patterns for building resilient distributed systems, focusing on adaptation, decomposition, consistency, and safety. Learn strategies for system evolution and testing.
Availability, Latency, and Cost - Withstanding Regional Outages
Explore Netflix's multi-region strategy for improved availability and latency, including algebraic models, incident management, and design considerations for efficient failovers and user steering.