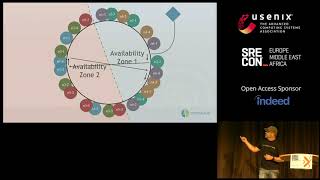
Circonus - Design Failures Case Study
Explore Circonus platform's evolution, including architectural changes and lessons learned from failures in telemetry management and SLO implementation for system reliability.
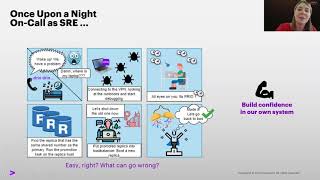
Let the Chaos Begin - SRE Chaos Engineering Meets Cybersecurity
Explore Security Chaos Engineering's role in uncovering system vulnerabilities and enhancing cyber resiliency. Learn to formulate and verify hypotheses through practical experimentation.
Security Chaos Engineering
Explore Security Chaos Engineering: a proactive approach to uncover system vulnerabilities through controlled experiments, empowering engineers to enhance resilience before real-world attacks occur.
Moving Fast at Scale
Strategies for scaling engineering teams while maintaining speed and efficiency. Explores organizational structure, DevOps practices, continuous delivery, and cultural shifts to foster innovation and rapid iteration.
Interaction Protocols - It's All About Good Manners
Explore the crucial role of interaction protocols in distributed systems, covering their impact on performance, resilience, and communication. Learn best practices for effective protocol design and implementation.
What We've Learned from Running Thousands of Production RabbitMQ Clusters
Gain insights on optimizing RabbitMQ clusters from extensive production experience. Learn best practices, common pitfalls, and strategies to enhance reliability and performance in various cloud environments.
Making Chaos Engineering Boring - Debunking Myths Hampering Adoption
Debunking myths about chaos engineering to promote adoption. Learn its definition, benefits, and how to overcome roadblocks in implementing this valuable practice for preventing major system issues.
How Google SRE and Developers Work Together
Discover Google's SRE engagement model for building reliable, scalable services. Learn how SREs and developers collaborate to ensure efficiency and maintainability in complex systems.
Spring Cloud Gateway - Resilience and Security
Explore Spring Cloud Gateway for resilient, secure microservices. Learn routing, circuit breakers, retries, authentication, and observability to enhance your API architecture.
Getting Started with Chaos Engineering
Explore chaos engineering with industry experts as they discuss best practices, experiences, and key takeaways from their book. Learn how to optimize distributed systems and improve incident response.
Getting Started with Chaos Engineering
Explore chaos engineering principles with industry experts, learning best practices from Netflix and Capital One to optimize distributed systems and meet business goals effectively.
Architecting for Scale
Learn best practices for scaling software architecture, including risk management, microservices adoption, and release strategies. Gain insights on building robust systems that can handle growth and increased demand.
Mature Microservices & How to Operate Them
Explore strategies for building and maintaining resilient microservices architectures, focusing on operational capabilities, monitoring, observability, and long-term sustainability in evolving systems.
Securing Our Future - Lessons From the Human Immune System
Explore how the human immune system's defense mechanisms can inspire innovative cybersecurity strategies for protecting digital assets and networks.
Chaos Engineering - Withstanding Turbulent Conditions in Production
Explore Chaos Engineering to enhance resilience in distributed systems. Learn practical techniques, conduct experiments, and implement resilience patterns for robust Cloud-Native Spring Boot applications.
Vaurien - The Chaos TCP Proxy
Explore Vaurien, a TCP proxy tool for simulating network issues and testing application resilience in distributed systems.
An SLO-Driven Approach to Enhance Kubernetes Cluster Reliability
Explore SLO-driven approaches to enhance Kubernetes cluster reliability, including defining SLOs, monitoring, alerting, and tracing for large-scale production environments.
Adopting Thanos Gradually Across All of LastPass Infrastructures
Explore LastPass's journey in implementing Thanos for unified metrics across diverse infrastructures, addressing challenges and architectural decisions for improved reliability.
From Prototype to Production - Lessons from Building and Scaling Reddit's Ad Serving Platform
Explore Reddit's journey in building a high-performance ad serving platform using Go, from prototype to production, with insights on scalability and reliability.
Rebuilding Facebook Chat
Discover how Facebook's chat was rebuilt using modularity and functional programming, improving reliability and enabling feature additions without regressions.
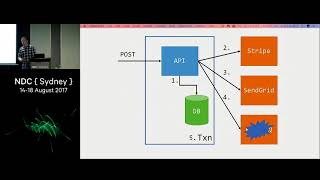
Six Little Lines of Fail
Explore challenges in distributed systems, examining failures in a simple checkout process and refactoring towards resilience while embracing distributed computing fallacies.