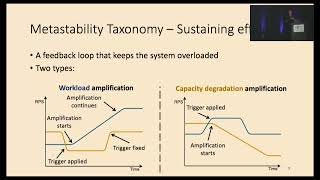
Metastable Failures in the Wild
Explores metastable failures in distributed systems, analyzing real-world incidents to categorize triggers and amplification mechanisms, aiding understanding and potential solutions for this prevalent issue.
Principled Performance Analytics
Explore innovative analytical methods for high-fidelity insights in distributed systems, focusing on performance analytics, statistical approaches, and practical applications in complex services at scale.
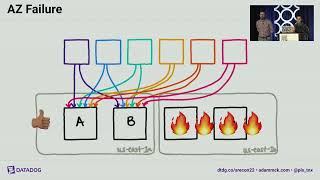
How the Metrics Backend Works at Datadog
Explore Datadog's metrics backend evolution, scaling challenges, and reliability solutions. Learn about distributed systems, Kafka implementation, and strategies for handling failures at various levels.
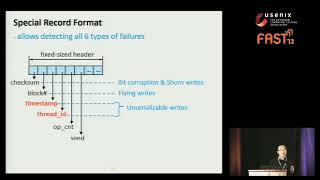
Understanding the Robustness of SSDs under Power Fault
Explores SSD reliability under power faults, revealing surprising failure behaviors in commodity devices. Proposes a testing framework to expose issues and improve storage system robustness.
Food for Thought - What Restaurants Can Teach Us about Reliability
Explore how restaurant operations parallel computer system reliability, drawing insights from dining experiences to enhance understanding of complex system management and fault tolerance.
Beyond Goldilocks Reliability
Explore reliability engineering beyond traditional SRE practices. Learn about concrete models, underlying mechanisms, and new strategies to enhance service reliability and tackle complex challenges.
Automating Performance Tuning with Machine Learning
Explore machine learning-driven automation for optimizing Kubernetes microservices and JVM settings, enhancing performance, efficiency, and cost-effectiveness in complex tech stacks.
Evolution of Incident Management at Slack
Explore Slack's evolution in incident management, covering strategies for handling numerous incidents, team-wide capability building, and future directions in maintaining platform reliability.
Don't Follow Leaders or - All Models Are Wrong - and So Am I
Reflective analysis of SRE book's impact, addressing its strengths, weaknesses, and unresolved challenges in production engineering and reliability practices five years after publication.
Remember When We Broke the Internet
Exploring unexpected incidents in open source history, their impact on technology, and the complexity of open source ecosystems as sociotechnical systems.
Meatbag Systems - How Our Reliability Culture & Practice Evolved over Time
Exploring the evolution of reliability culture through major incidents, emphasizing the human aspect in maintaining production systems and aligning reliability with customer value.
Reliable Data Processing with Minimal Toil
Explore strategies for safer, automated batch job processing across millions of users, featuring insights from Google and Slack on canarying, rollouts, and validations.
RSocket - New Reactive Cross-Network Protocol
Explore RSocket, a fast and resilient network protocol with reactive streams semantic for efficient microservices communication. Learn its advantages over REST and gRPC for building reactive systems.
How Events Are Reshaping Modern Systems
Explore event-driven architecture's benefits in modern systems, including autonomy, scalability, and resilience. Learn design principles and practical techniques for leveraging events effectively.
Practical Magic - The Resilience Potion & Security Chaos Engineering
Explore the five-ingredient Resilience Potion Recipe to foster systems resilience and guide security chaos engineering transformation, with practical opportunities for each ingredient in software development.
The Smallest Distributed System
Explore lessons learned from building Travis CI's distributed system, focusing on simplicity, resilience, and handling failures. Gain insights on evolving from a monolithic to a distributed architecture.
Building the Renewable, Self-Driving Grid - Lessons from Reliability Engineering
Explore the transition to a zero-carbon energy system through innovative grid technology, drawing parallels with distributed systems in tech to ensure reliability and efficiency.
All Fall Down - Interdependencies in the Cloud
Explore cloud system interdependencies, potential cascading failures, and strategies for enhancing resilience in interconnected cloud infrastructures.
A House Built on Sand - Engineering Stable and Reliable AI
Discover techniques for creating robust AI systems that remain stable despite changing requirements, focusing on engineering practices for game development.
We're Still Down - A Metastable Failure Tale
Explore a CDN's metastable failure, design improvements, and unconventional recovery methods. Learn strategies to prevent and address similar incidents in distributed systems.
Exploring Disconnects between Reliability Practitioners and Management
Insights into perception gaps between reliability practitioners and management based on The SRE Report, offering strategies to bridge differences and improve organizational alignment.