Video Games and the Future of Artificial Intelligence
Explore how modern video games and their advanced physics simulations are revolutionizing AI development and machine learning capabilities through realistic virtual environments.
LTV Forecasting and Churn Analysis for Mobile Gaming Revenue Optimization
Discover advanced LTV forecasting and churn analysis techniques for mobile gaming, focusing on whale player identification, MTL neural networks, and practical implementation strategies.
Seeing Through the Lens of Transformers - A New Era in Computer Vision
Explore the revolutionary impact of transformer architecture in computer vision, from its origins in language processing to groundbreaking applications in visual tasks and self-attention mechanisms.
Industry NLP: Multitask and Continual Learning - Adapters and Hypernetworks Approach
Discover how adapters and hypernetworks revolutionize NLP tasks through multi-task and continual learning approaches, enabling faster training, efficient storage, and seamless ML system integration.

Training High Quality Embedding Models for Production Vector Search
Master practical techniques for training and optimizing embedding models for production-ready vector search, covering data quality, loss functions, and efficient updating strategies.
Machine-Precision Neural Networks for Multiscale Dynamics
Discover how multi-stage neural networks can achieve machine-precision accuracy in scientific predictions, addressing spectral bias and improving deep learning applications in multiscale physics problems.
Parameter Efficient Fine-Tuning with Multiple LoRA Adapters for Large Language Models
Dive into parameter efficient fine-tuning with LoRA adapters, exploring matrix factorization, SVD, and advanced configurations for optimizing large language models.
Self-Reflective AI: Understanding Self-RAG Framework for Multi-AI-Agents
Explore the innovative Self-RAG framework that enhances AI language models through self-reflection and intelligent retrieval mechanisms, improving accuracy and contextual relevance in text generation.
StreamingLLM: Enabling Infinite Sequence Length in Large Language Models
Dive into StreamingLLM's framework for extending LLM attention windows to handle infinite sequences, featuring practical implementation insights and code analysis.
The Future of AI: From Language Models to Multimodal Agents and Video Processing
Explore the cutting-edge developments in AI technology, from multimodal agents to GPT-4's video capabilities, and discover how AI systems are evolving to handle diverse data types and tasks.
Mamba AI: Understanding Selective State Space Models as Transformer Alternatives
Explore the groundbreaking MAMBA architecture and its potential to revolutionize AI through selective state space models, offering a compelling alternative to traditional transformers.
Mixture of Experts (MoE) in Large Language Models - A Simple Guide
Delve into the architecture and functionality of Mixture of Experts (MoE) systems in language models through clear examples and technical insights about token routing, gating networks, and computational efficiency.
Mistral 7B: Architecture, Performance and Implementation Guide
Dive into Mistral 7B's implementation, exploring grouped-query attention, efficient GPU usage, and hands-on demonstrations for running advanced language models on local hardware.
How to Code Long-Context LLMs - LongLoRA Implementation with Llama 2 100K
Dive into fine-tuning techniques for extending LLM context lengths using LongLoRA, featuring practical implementation on Llama 2 and Flash Attention 2 optimization for handling extensive sequences.
Stable Diffusion XL Theory and Code with Shape-Shifting ControlNet
Dive into the advanced mechanics of SDXL and ControlNet, exploring text-to-image diffusion models and shape-shifting techniques for synthetic image manipulation.
WizardCoder 34B: Understanding Complex Fine-Tuning for Code Generation
Delve into the advanced fine-tuning techniques behind WizardCoder-34B, exploring its performance improvements through complex instruction cascading and evolutionary approaches.
Introduction to KERAS 3 Core for PyTorch and JAX
Explore KERAS 3's framework-agnostic capabilities for building neural networks and transformers across TensorFlow, PyTorch, and JAX platforms with advanced customization options.
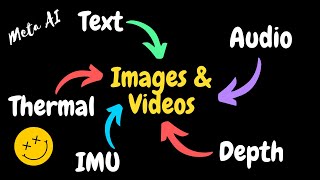
ImageBind: A Multi-Modal AI Model for Unified Embedding Space
Explore Meta AI's ImageBind technology and its groundbreaking approach to unified AI learning across six modalities, from technical architecture to practical applications and results.
Mistral 7B - Understanding the Architecture and Performance Improvements
Dive into the technical innovations of Mistral 7B, exploring its groundbreaking attention mechanisms, caching strategies, and performance improvements over existing language models.
LLaVA: Large Language and Vision Assistant - Understanding the First Instruction-Following Multimodal Model
Discover how LLaVA pioneered instruction-tuned multimodal AI, combining language and vision capabilities to create a groundbreaking Large Multimodal Model for advanced visual understanding and interaction.

Quantization in Deep Learning: Types, Algorithms, and Implementation
Explore quantization techniques in deep learning, from uniform to non-uniform approaches, and learn practical implementation strategies for optimizing large-scale neural networks.