Kolmogorov-Arnold Networks: Understanding KAN Architecture and Comparison with MLPs
Dive into Kolmogorov-Arnold Networks (KAN), a groundbreaking alternative to Multi-Layer Perceptrons, exploring its architecture, implementation, and potential advantages in neural network development.
LongRoPE and Theta Scaling for Extended Context Length in LLMs - Part 2
Delve into advanced techniques for extending LLM context lengths through LongRoPE and Theta Scaling, exploring methods to enhance model performance from 8K to 4M tokens.
RoPE: Rotary Position Embedding for Extended Context Lengths in Transformers
Dive into Rotary Position Embedding (RoPE) and learn how this innovative technique enhances transformer models by enabling extended context lengths up to 100K tokens.
In-Context Learning - Comparing Extreme Context Length with Fine-Tuning and RAG
Explore groundbreaking research on in-context learning with extended context models, comparing performance against fine-tuning and RAG methods while examining scaling impacts and demonstration effectiveness.
Fine-Tuning Large Language Models: Impact on Knowledge Integration and Hallucinations
Delve into groundbreaking research on how fine-tuning Large Language Models with new knowledge affects their tendency to generate hallucinations, exploring methodologies and practical implications.

Matrix Long Short-Term Memory (mLSTM) - A New Alternative to Transformer LLMs
Explore the innovative xLSTM architecture and its matrix-based approach to neural networks, comparing its potential advantages over traditional transformer models in language processing.
Understanding DSPy - Programming AI Pipelines for Language Models
Explore DSPy's innovative approach to AI pipeline programming, from its ColBERT v2 origins to practical applications in modular pipeline generation and self-improving language programs.
Understanding Snowflake Arctic 480B - A Mixture of Experts LLM Architecture
Dive into the architecture and performance analysis of Snowflake's Arctic 480B LLM, exploring how its 128x4B MoE design compares to traditional transformers for enterprise-level AI tasks.
RecurrentGemma: Moving Past Transformers with Griffin Architecture for Long Context Length
Explore Google's RecurrentGemma-2B architecture, featuring Griffin's innovative approach to language modeling that surpasses traditional transformers with enhanced efficiency and long-context processing capabilities.
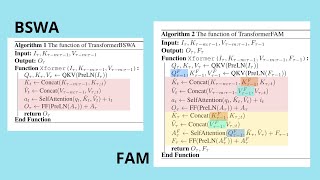
TransformerFAM and BSWA: Understanding Feedback Attention Memory and Block Sliding Window Attention
Dive into Google's revolutionary TransformerFAM architecture, exploring how feedback attention mechanisms and working memory enhance AI's ability to process indefinite sequence lengths with improved efficiency and context awareness.
INFINI Attention: Efficient Infinite Context Transformers with 1 Million Token Context Length
Explore Google's Infini-attention transformer mechanism, featuring compressive memory integration for handling million-token sequences and efficient long-term information processing.
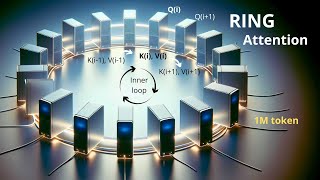
Ring Attention and Blockwise Transformers for Extended Context Length in Language Models
Dive into the technical mechanics of Ring Attention, exploring how it achieves million-token context lengths in large language models through blockwise parallel transformers and efficient implementation.
ORPO: A New Preference-Aligned Training Method for Large Language Models
Explore a groundbreaking reference model-free optimization algorithm for LLM training, comparing ORPO's performance with Llama 2 and Mistral 7B through theoretical physics perspectives.
Symmetry Breaking in AI Diffusion Models - Dynamical Regimes and Optimization
Explore groundbreaking research on symmetry breaking patterns in AI diffusion models and their impact on optimization and transformation processes.
Understanding AI State Machines, State Agents, and State Spaces
Explore fundamental AI concepts including state machines, agent states, and state spaces in modern language models, with clear explanations of their interconnections and applications.
Self-Extending LLM Context Windows Using Grouped Self-Attention
Discover how to extend LLM context windows through grouped self-attention, enabling longer text processing without model retraining. Learn implementation techniques and practical applications.
Supercharging Multi-LLM Intelligence with CALM - Composition to Augment Language Models
Discover how CALM (Composition to Augment Language Models) revolutionizes multi-LLM integration through advanced projection layers and cross-attention mechanisms for enhanced AI capabilities.
Generative Interactive Environments (GENIE) - Creating Synthetic Video Game Worlds
Explore GENIE AI's groundbreaking technology for generating interactive video environments, featuring advanced neural networks and transformers for synthetic world creation.
DSPy for In-Context Learning and RAG Classification - Code Explained
Explore state-of-the-art extreme multi-label classification using DSPy's Infer-Retrieve-Rank program, combining frozen retrieval with in-context learning for optimal results.
Diffusion Transformer and Rectified Flow in Stable Diffusion 3
Dive into the mechanics of Diffusion Transformers, exploring noise distribution, latent space dimensionality, and the innovative Rectified Flow technology powering next-gen AI image generation.
Understanding 4-bit Quantization and QLoRA - Memory Efficient Fine-tuning of LLMs
Dive into memory-efficient fine-tuning of large language models through 4-bit quantization and QLoRA, combining theoretical foundations with practical implementation in Colab.