Lumiere: Space-Time Diffusion Model for Text-to-Video Generation
Dive into Google's Lumiere text-to-video model, exploring its innovative space-time UNet architecture and MultiDiffusion design for creating temporally consistent video generation.
Simple Quantization of LLMs - A Hands-on Guide to Absolute Max and Zero Point Methods
Master practical LLM quantization techniques through hands-on implementation of Absolute Max and Zero Point methods, building foundational skills for advanced approaches like GPTQ and AWQ.
Getting Started with HuggingFace Transformers - Pipeline, Tokenizer, and Model Development
Master HuggingFace Transformers library fundamentals, from pipelines and tokenizers to models and Hub integration, enabling you to effectively work with and fine-tune Large Language Models.
Application of Machine Learning Approaches to the Generation of Organic Compounds and Properties Prediction
Explore machine learning techniques for generating organic compounds and predicting their properties, focusing on practical applications in theoretical physics and chemistry.

QLoRA: Efficient Training of Large Language Models Using Quantization and Low-Rank Adaptation
Discover how QLoRA enables efficient training of large language models on a single GPU through innovative techniques like NormalFloat, Double Quantization, and Paged Optimizers.
LoRA: Low-Rank Adaptation for Parameter-Efficient Large Language Model Fine-Tuning
Discover how LoRA enables efficient fine-tuning of large language models through low-rank adaptation, from fundamental concepts to practical implementation in transformer architectures.
Stable Video Diffusion: Model Architecture and Training Pipeline
Dive into the technical architecture and training methodology of Stable Video Diffusion, exploring its three-stage process, data curation pipeline, and practical applications in AI-powered video generation.
ControlNet: Adding Conditional Control to Text-to-Image Diffusion Models
Delve into the groundbreaking ControlNet paper, exploring its architecture, classifier-free guidance, and spatial control capabilities in text-to-image diffusion models through detailed technical explanations.
Robin3D: Improving 3D Large Language Models Through Robust Instruction Tuning
Discover how Robin3D advances spatial intelligence through innovative data generation and architectural improvements for better 3D scene understanding and object relationship comprehension.

DINOv2: Data Pipeline, Model Training and Results - Meta AI's Visual Feature Learning System
Delve into Meta AI's DINOv2 architecture, exploring its data pipeline, training methodology, and innovative features for robust visual processing without supervision in just 12 minutes.
Understanding Meta AI's Segment Anything Model (SAM) - Architecture, Data Engine, and Results
Dive into Meta AI's Segment Anything Model (SAM), exploring its architecture, innovative data engine, and zero-shot transfer learning capabilities for advanced image segmentation tasks.
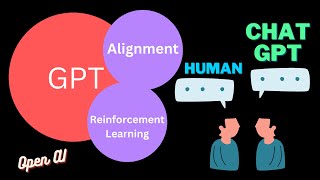
How ChatGPT is Trained - Model and Training Explained
Delve into the technical foundations and training methodology behind ChatGPT, exploring its model architecture, reinforcement learning principles, and step-by-step training process.
Neuro-Symbolic Graph Reasoning and Knowledge Graph Analysis - From Theory to Implementation
Explore neuro-symbolic AI frameworks and graph-based reasoning through practical examples, from biomedical research applications to Python implementations and logical rule learning.

Intelligence at the Edge of Chaos - Understanding Complex Reasoning in Overparameterized LLMs
Explore groundbreaking research on how intelligence emerges in LLMs through complex datasets, focusing on the critical balance between order and chaos in cellular automata-based training.
Inside the Black Box of AI Reasoning - Understanding LLM Knowledge and Complex Problem-Solving
Delve into groundbreaking research exploring how AI models process complex reasoning tasks, using novel graph-based frameworks to analyze knowledge integration and problem-solving capabilities.
CriticGPT: Understanding RLHF and Force Sampling Beam Search Optimization
Dive into OpenAI's innovative CriticGPT algorithm, exploring how RLHF and Force Sampling Beam Search optimize language models and enhance their reliability.
Coding Multi-Agent Reinforcement Learning with PyTorch and JAX - Including ReDel and AgentScope Frameworks
Dive into practical multi-agent reinforcement learning implementation using PyTorch and JAX, featuring new frameworks ReDel and AgentScope for advanced distributed systems and LLM-powered simulations.
Understanding Grokking - A New Performance Phase in Large Language Models
Discover how extended training of LLMs leads to "grokking" - a breakthrough phase where models develop superior generalization abilities and form geometric patterns in embedding spaces.
NEFTune - Improving LLM Performance Through Noisy Embeddings Fine-Tuning
Discover how NEFTune's innovative instruction fine-tuning method enhances LLM performance through noisy embeddings, with practical implementation in HuggingFace TRL.
Stable Diffusion XL with T2I-Adapter and ControlLoRA - Tutorial and Demo
Master advanced image generation techniques using SDXL with T2I adapters and ControlLoRA, featuring hands-on demonstrations and practical implementations for enhanced AI art creation.
Fine-tuning LLama 2 with PEFT, LoRA, 4-bit Quantization, TRL and SFT
Master advanced LLama2 fine-tuning techniques using PEFT, LoRA, and 4-bit quantization while creating synthetic datasets with GPT-4 for customized model training.