Berkeley Lab's Breakthroughs in Exascale Supercomputing and AI Energy Efficiency
Explore Berkeley Lab's journey from atomic age to supercomputing forefront. Discover exascale computing challenges, energy efficiency innovations, and future HPC directions with specialized hardware and chiplets.
Reflecting on the 'Why' Behind Supercomputing Simulations - Advancing Science
Explore supercomputing's role in scientific advancement with insights from an expert on simulation applications and exascale computing.
Jack Dongarra's Perspective on the Exascale Computing Project
Explore computing pioneer Jack Dongarra's insights on the Exascale Computing Project's progress, achievements, and future impact on scientific research and high-performance computing.
ECP Broadening Participation Initiative: Challenges, Gaps, and Opportunities in Computing Workforce
Explore strategies for fostering diversity and inclusion in DOE high-performance computing, addressing workforce challenges and opportunities.
ClusterCockpit: Job-Specific Performance Monitoring for HPC Systems Demo
Explore the ClusterCockpit web interface for job-specific performance monitoring in HPC systems, gaining insights into this powerful framework's capabilities.
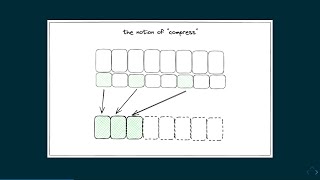
Advanced SIMD Algorithms in Pictures - Lecture
Explore advanced SIMD algorithms for memcmp, copy_if, and set_intersection through visual explanations. Gain insights into vectorized implementations without prior SIMD knowledge.
Introduction to Numerical Computation Applications Using Ubuntu WSL
Explore numerical computing on Ubuntu WSL for efficient solver development and deployment, with practical examples and insights on streamlining workflows for complex engineering problems.
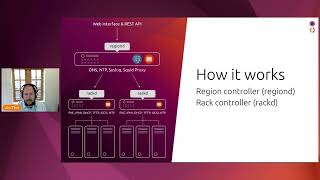
Juju on Metal for High Performance Computing
Explore MAAS and Juju for deploying bare metal HPC workloads. Learn how charms integrate with MAAS to efficiently manage clusters for various applications, from LXD to OpenStack.
vLLM on Kubernetes in Production - Deployment and Cost-Saving Strategies
Deploy vLLM on Kubernetes for efficient LLM inference and serving. Learn basics, local setup, and production deployment with GPU-attached nodes via DaemonSet. Includes hands-on demo and cost-saving strategies.
Accelerating Scientific Discovery with AI and Quantum Computing
Explore cutting-edge insights on distributed computing and AI from IBM's Dario Gil in this Ray Summit 2022 keynote address.
Managed Cloud Infrastructure for LLMs
Explore solutions for LLM infrastructure challenges, including cost reduction, GPU availability, scalability, and cloud resource management. Learn to accelerate AI development and deployment.

Introduction to the Pawsey Supercomputing Research Centre
Explore Pawsey Supercomputing Research Centre's capabilities and impact on scientific research with Supercomputing Specialist Marco De La Pierre.
Cppless: A Single-Source Programming Model for High-Performance Serverless
Explore Cppless, a single-source programming model enabling high-performance serverless applications in C++. Learn about transparent offloading, common abstraction layers, and composable architectures for efficient cloud computing.
Accelerating Data Serialization and Deserialization Protocols with In-Network Compute
Explore in-network compute techniques to accelerate data serialization/deserialization protocols, enhancing efficiency in datacenter and HPC systems. Learn about SmartNIC offloading and its impact on performance.
Streaming Task Graph Scheduling for Dataflow Architectures
Explore efficient scheduling techniques for dataflow architectures using canonical task graphs, steady-state analysis, and spatial block partitioning to optimize performance and device utilization.
Noise in the Clouds - Influence of Network Performance Variability on Application Scalability
Explore network performance variability in cloud computing and its impact on HPC workload scalability, comparing cloud providers with on-premise systems.
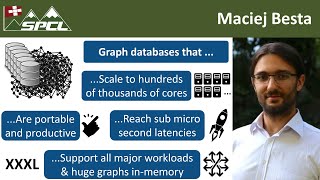
The Graph Database Interface: Scaling Online Transactional and Analytical Graph Workloads
Explore cutting-edge graph database technology scaling to 100,000+ cores. Learn about GDI, a new interface for high-performance, scalable graph processing in distributed memory systems.
EtherNET: The Present and Future of Datacenter and Supercomputer Interconnects
Explore the role of Ethernet in modern datacenters and supercomputers, examining its current state and future prospects in high-performance computing environments.
Fortran Optimization for Accelerator Devices - Data-Centric Representation
Explore data-centric optimization techniques for Fortran code on accelerator devices, enhancing high-performance computing capabilities.
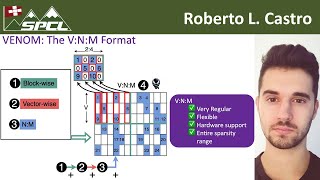
VENOM: A Vectorized N:M Format for Unleashing the Power of Sparse Tensor Cores
Explore VENOM, a vectorized N:M format for sparse tensor cores. Learn about high-performance sparse libraries and second-order pruning techniques for efficient deep learning model sparsification.
Swing: Short-cutting Rings for Higher Bandwidth Allreduce
Optimize allreduce performance on torus networks with Swing algorithm. Improve bandwidth by reducing distance between communicating nodes, outperforming existing methods by up to 3x.