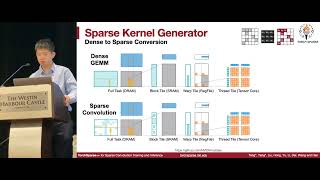
TorchSparse++ - Efficient Training and Inference Framework for Sparse Convolution on GPUs
Explore efficient GPU-based sparse convolution with TorchSparse++, an advanced framework for training and inference in deep learning applications.
Insights and Experiences of Packaging Python Binary Extensions
Explore challenges and solutions for packaging Python binary extensions in scientific computing, focusing on portability and performance across diverse platforms.
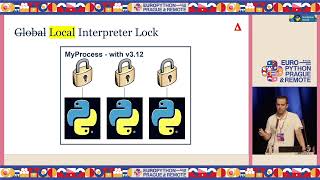
Python in Parallel: Sub-Interpreters vs. NoGIL vs. Multiprocessing
Explore Python's parallel processing options: Sub-Interpreters, NoGIL, and Multiprocessing. Compare their pros and cons for CPU-bound and IO-bound applications to make informed decisions on leveraging multi-core capabilities.
Parallel Computing in OpenFOAM Using MPI - DecomposePar and ReconstructPar Tutorial
Learn to set up parallel computing with MPI in OpenFOAM, including decomposePar and reconstructPar operations, for enhanced simulation efficiency.
GraphQL and Rails Beyond HTTP APIs
Explore GraphQL's versatility in Rails projects beyond HTTP APIs, including real-time data, webhooks, WebAssembly integration, and efficient data export.

Optimizing Time Series Data in Mixed Architectures with QuestDB
Explore time series database optimization, high-performance data ingestion, and cross-platform integration with QuestDB engineer Adam Cimarosti. Gain practical insights for handling fast-moving data in modern deployments.
MeshGraphNets.jl - Adaptation of MeshGraphNets as NeuralODE
Explore MeshGraphNets.jl: Adapt MeshGraphNets as NeuralODE for efficient simulation of physical systems. Learn design choices, GPU optimization, and industrial applications in hydraulic brake systems.
Storage Best Practices for Data Analytics, GKE, and Critical Applications
Discover optimal storage strategies for data analytics, GKE workloads, and critical applications, enhancing performance and efficiency in cloud environments.
Top HPC Best Practices for Deploying and Managing Demanding Workloads
Explore Google Cloud's latest HPC advancements, including VMs, processors, accelerators, and storage solutions. Learn deployment tools and best practices for managing demanding workloads.
Simplify and Secure Your Network for All Workloads: Cloud Networking Innovations
Leverage new network offerings for faster migration, enhanced security, and improved operational efficiency. Explore CDN, Private Service Connect, ML-powered security, and GKE networking.
KSVD.jl: A Case Study in Performance Optimization
Explore performance optimization techniques for K-SVD algorithm implementation, including execution order adjustments, single-core optimizations, multi-threading, and distributed computing.
Parallel Algebraic Multigrid in Julia with PartitionedArrays.jl - JuliaCon 2024
Explore parallel algebraic multigrid methods in Julia using PartitionedArrays.jl. Learn about recent updates, implementation strategies, and advantages over traditional MPI-based approaches for large-scale linear solvers.
DistributedWorkflow.jl - A Task-Based Workflow System Interface
Explore DistributedWorkflow.jl, a Julia interface for task-based workflow management. Learn to build domain-specific workflows, leverage dynamic scheduling, and simplify parallel distributed application development for HPC and domain scientists.
Drawing onto the Camera - React Native App Development
Explore real-time face blurring in React Native using VisionCamera and Skia. Learn about technical challenges, C++/GPU implementation, and new possibilities in 60 FPS camera streams.
Preemption Chaos and Optimizing Server Startup for LLMs in Production - Part 2
Optimize GPU costs and improve uptime by leveraging preemptible instances for LLM services, overcoming challenges and maximizing savings.
Installing WSL with CUDA Support and PyTorch for Data Science and Machine Learning
Aprenda a instalar WSL con soporte CUDA y PyTorch para potenciar sus proyectos de aprendizaje automático y ciencia de datos en Windows.
Accelerating Python Code with Numba and CuPy for Machine Learning
Boost Python code execution with GPU acceleration and compilation using Numba and Cupy for machine learning tasks.
Optimizing Python Code Speed with Numba JIT Compiler
Accelerate Python code execution using Numba's JIT compiler, leveraging jit and njit decorators for enhanced performance.
Pandas Parallel Transformations with Dask and Pandarallel
Optimize data processing with Dask and Pandarallel for faster Pandas transformations. Learn parallel computing techniques to enhance performance.
Installing NVIDIA cuDNN and First Steps with NVCC in C++
Aprenda a instalar Cudnn y desarrolle aplicaciones de ML con soporte GPU en C++, utilizando la biblioteca de redes neuronales profundas de Nvidia.
The First Optimal Distributed SGD in the Presence of Data, Compute and Communication Heterogeneity
Explore optimal time complexities for parallel optimization methods with heterogeneous data, compute, and communication. Gain insights into efficient distributed SGD algorithms.