Dynamic Graphs on the GPU
Explore GPU-accelerated techniques for dynamic graph algorithms, focusing on efficient data structures and parallel processing for real-time graph updates and analysis.
High Performance Secure Container - Quark
Explore Quark, a high-performance secure container solution, presented by experts from Futurewei. Learn about its innovative features and potential applications in containerization technology.
High Performance Databases in Containerized Environments
Explore high-performance databases in containerized environments, focusing on Kubernetes architecture, challenges, and best practices for optimizing database performance and scalability.
Hardware-Assisted IO Virtualization: Applying Techniques to Virtualization Framework
Explore hardware-assisted techniques for optimizing I/O virtualization in high-performance computing, focusing on RISC-V architecture and paravirtual I/O devices in kernel and userspace.
Simple and Scalable Microservices: Using NATS with Docker Compose and Swarm
Explore NATS messaging system for microservices, its core features, and integration with Docker Compose and Swarm for simple, scalable, and low-latency distributed systems.
Exponentially Faster Massively Parallel Maximal Matching
Discover advanced techniques for optimizing parallel maximal matching algorithms, enhancing efficiency and scalability in large-scale data processing.
Conditional Hardness Results for Massively Parallel Computation from Distributed Lower Bounds
Explore conditional hardness results in massively parallel computation, derived from distributed lower bounds. Gain insights into theoretical computer science and parallel algorithms.
Docker Containers for Machine Learning on Specialized AI Hardware
Explore Docker's role in scaling machine learning across heterogeneous systems with multiple processors, including GPUs and AI accelerators. Learn about container benefits and future trends in multi-processor ML workloads.
Serving Machine Learning Models at Scale Using KServe
Explore KServe's Multi-Model Serving solution for scalable machine learning deployment. Learn design, implementation, and benchmarks for efficient model serving across frameworks.

Trends in Deep Learning Hardware
Explore deep learning hardware advancements, including GPU efficiency improvements and data representation innovations, with NVIDIA's chief scientist Bill Dally.
Building a Multi-Cluster Privately Hosted LLM Serving Platform on Kubernetes
Explore the architecture and challenges of building a cloud-agnostic LLM serving platform on Kubernetes, including control plane, dataplane, and serverless inference using KEDA for auto-scaling.
How We Power the Largest AI Deployments on the Planet - Running Virtual Clusters at Scale
Explore challenges and solutions for managing large-scale Kubernetes clusters on bare metal, focusing on security, GPU provisioning, and scalability for AI workloads at CoreWeave and Loft Labs.
Training Foundation Model Workloads on Kubernetes at Scale with MCAD
Explore how IBM's Vela supercomputer uses MCAD to queue custom resources for large-scale AI training on Kubernetes, enabling flexible frameworks and fault tolerance across hundreds of GPUs.
Keep HPC Running - SRE's Guide to Supporting GPUs on Kubernetes
Learn best practices for SRE teams supporting GPU-enabled Kubernetes clusters for HPC and AI workloads, including key metrics, monitoring tools, and operational strategies.
Training Large Language Models on Kubernetes
Explore challenges and best practices for training Large Language Models on Kubernetes, including optimization techniques, resource management, and benchmarks comparing K8s to bare metal environments.
Middleware for Quantum - Enabling Advanced Quantum Computing Workflows
Explore open-source Middleware for Quantum, integrating quantum computing with Kubernetes for complex tasks. Learn how it manages heterogeneous resources and enables advanced quantum-classical workflows.
Unveiling the Future of High-Performance Computing with Ulrike Yang
Explore xSDK, an ecosystem of interoperable math libraries for extreme-scale architectures, enabling efficient development of high-quality applications in multiphysics modeling and data analytics.
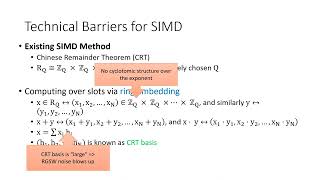
Fully Homomorphic Encryption: Advanced Techniques and Optimizations - Session 2
Explore advanced concepts in fully homomorphic encryption, including noise management, bootstrapping techniques, and optimizations for improved performance and efficiency in secure computations.
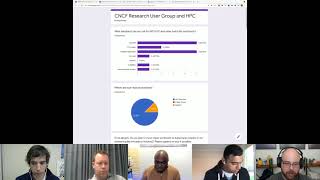
CNCF Research: HPC and HTC End User Landscape - December 2021
Explore HPC/HTC landscape in cloud-native environments, covering solutions, deployments, workload migration, resource management, and tools for high-performance computing.
Emission and Emissive Materials - Ray Tracing Series
Explore emission and emissive materials in ray tracing, enhancing your ability to create realistic lighting effects and improve the visual quality of rendered scenes.
Less Talking, More Learning - Avoiding Coordination in Parallel Machine Learning Algorithms
Strategies for scaling machine learning on parallel platforms, focusing on coordination-free algorithms to maximize computation time and discussing challenges in performance analysis.