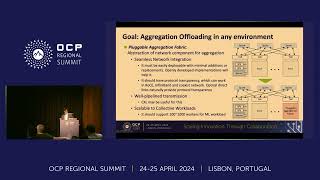
Optcast: Open-Source Aggregation Offloading for Distributed Deep Learning
Discover how to accelerate distributed AI training through open-source in-network aggregation, achieving 1.72x faster performance across multiple GPUs without specialized hardware requirements.
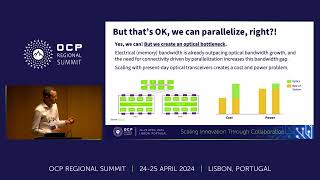
Coherent Optics and Photonics Technologies for AI Data Center Interconnects
Discover how coherent optics and photonic technologies optimize data center interconnects for AI applications, focusing on cost efficiency and sustainable scaling solutions.
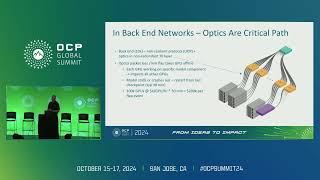
Liquid Cooling Impact on Backend Network Design for AIML Systems
Explore how liquid cooling transforms AI/ML backend networks, enabling cost-effective interconnect solutions and significant power savings while improving network reliability through innovative data center design.
Deploying the AI Factory - Transforming Data Centers with Accelerated Computing
Explore how accelerated computing transforms data centers into efficient AI factories, focusing on NVIDIA's Blackwell-powered solutions and advanced cooling technologies for optimal performance.
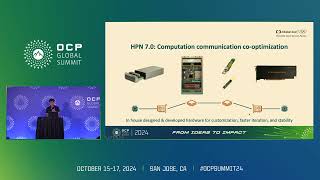
Alibaba HPN - Data Center Network Architecture for Large Language Model Training
Explore the innovative HPN architecture designed for large language model training, featuring dual-plane design, efficient path selection, and enhanced fault tolerance for high-performance computing.
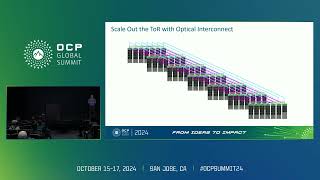
The Art of AI Networking Scaling to Support 100K GPU Nodes
Explore advanced networking technologies and solutions for scaling AI infrastructure to support massive GPU node deployments, focusing on optics, power, cooling, and management challenges.
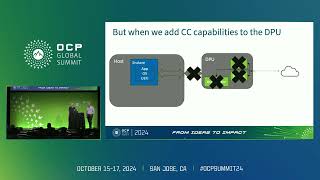
Beyond CPUs and GPUs - Extending Confidential Computing to DPUs for Enhanced AI Security
Explore how confidential computing extends beyond CPUs and GPUs to DPUs, examining privacy-preserving AI implementations and hardware-based security solutions for third-party infrastructure.
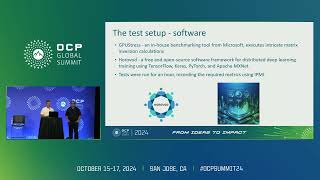
Combined Performance Metric for Data Center Efficiency in the AI Era
Explore a new data center efficiency metric (CPM) that combines GPU performance and power usage, designed specifically for evaluating AI workload infrastructure optimization.
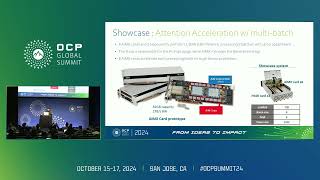
LLM Service Revolution Through Memory Computing Fusion Technology - From Datacenter to On-Device AI
Discover how SK Hynix's AiM technology revolutionizes LLM services through processing-in-memory solutions, offering enhanced efficiency and reduced costs for both datacenter and device-level AI applications.
Machine Learning Software Ecosystems: Frameworks, Compilers, and Models - Part 1
Explore the landscape of ML frameworks, compilers, and models while understanding performance considerations for various hardware platforms and edge computing requirements.
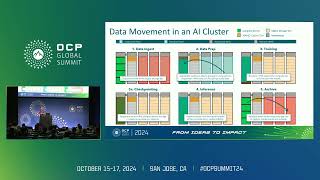
Optimizing High Density Storage for AI and ML Applications
Discover how to optimize high-density storage systems for AI/ML workloads, focusing on data pipelines, GPU utilization, and efficient solid-state storage solutions for large-scale models.
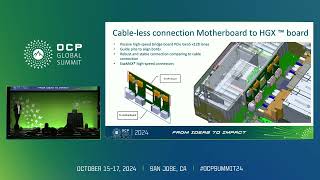
Designing In-House Server Solutions for Modern GPU Cloud Computing
Discover innovative approaches to designing energy-efficient servers and data centers optimized for ML-focused GPUs, with insights into thermal management and power consumption optimization.
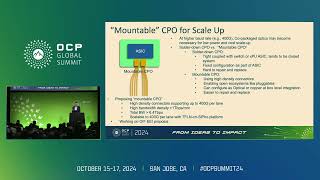
Energy-Efficient High Bandwidth Optical Interconnect Solutions for Generative AI
Explore cutting-edge optical interconnect technologies powering next-gen AI computing, from 800G deployment to 3.2T planning, focusing on power efficiency innovations like LPO, LRO, and CPO solutions.
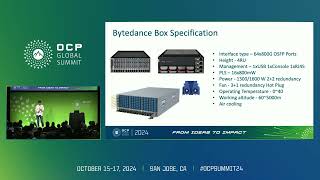
AI/ML Clusters Enabled by a 51.2 Tbps CPO Switch
Discover how Co-Packaged Optics technology revolutionizes AI/ML networks through a 51.2T switch, enabling enhanced bandwidth, reduced power consumption, and improved latency for large-scale GPU clusters.
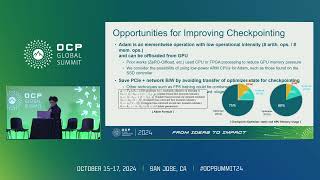
Checkpoint Offloading SSD - Enhancing Performance and Scalability in LLM Training
Discover how checkpoint offloading SSD technology optimizes LLM training by reducing GPU memory usage and improving data movement efficiency between storage components.
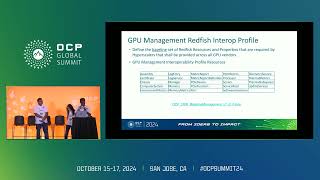
GPU Profiles for Hyperscale Use Cases - Redfish Interoperability and Management
Explore GPU tray management through Redfish Interoperability Profiles, focusing on compliance testing, vendor adoption, and practical implementation for hyperscale environments.
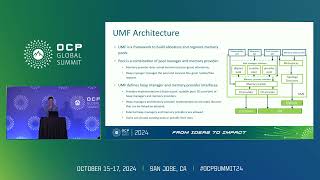
Unified Memory Framework: A Unified API for Diverse Memory Technologies
Explore Intel's Unified Memory Framework (UMF), an open-source solution for managing diverse memory technologies across CPU and GPU domains through consistent middleware mechanisms.
Addressing Future Thermal Challenges Driven by AI - Data Center Cooling Solutions
Explore thermal management innovations and solutions for AI-driven computing challenges, focusing on liquid cooling technologies and power efficiency in modern data centers.
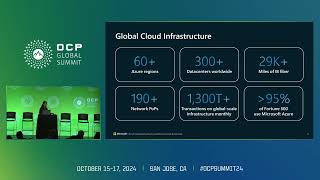
Exploring the Inner Workings of Azure's Advanced AI Infrastructure
Delve into Azure's advanced AI infrastructure, exploring GPU architectures, networking technologies, and system designs powering modern AI model training and deployment at scale.
Rethinking System Design for the New Wave of AI GPUs and CPUs
Explore innovative server design strategies for optimizing thermal management, power delivery, and performance in next-generation AI computing infrastructure with advanced GPUs and CPUs.
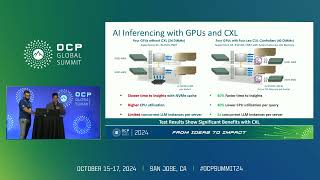
Optimizing AI Inferencing with CXL Memory - Memory Tiering Strategies for Enhanced Performance
Explore how CXL-attached memory revolutionizes AI inference systems, enhancing performance and scalability for Large Language Models while optimizing memory bandwidth and reducing latency.