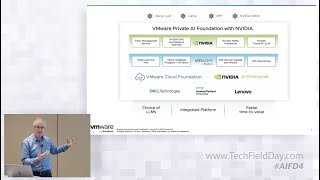
VMware Private AI Foundation with NVIDIA - Enterprise Generative AI Platform Overview
Discover how to deploy and manage enterprise-level generative AI applications with VMware's integrated solution, featuring NVIDIA NeMo for customization, enhanced security, and seamless data privacy controls.
Subzero.jl: Fast and Flexible Sea Ice Physics
Explore efficient sea ice modeling with Subzero.jl, leveraging Julia's speed for advanced climate simulations. Learn about discrete-element modeling and performance improvements in sea ice dynamics research.
AI Technologies Driving Innovation and Transformation in Data Centers
Explore how large-scale AI models transform data center technologies, focusing on Mix of Experts architectures, high-speed interconnects, and multi-GPU optimization for enhanced performance.
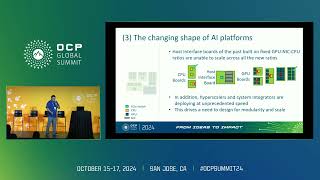
Using Modularity to Enable Hardware Reuse Across AI Platforms in a Rapidly Evolving Ecosystem
Explore modular architectures and design strategies for flexible GPU platform deployment, addressing data center challenges in AI/ML applications and hardware reusability.
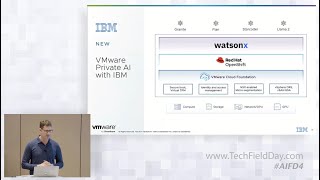
Running Best-of-Breed AI Services on VMware Cloud Foundation Platform
Discover how VMware Cloud Foundation enables secure AI deployment with IBM watsonx, Intel AI, and AnyScale Ray, offering enterprise-grade infrastructure for privacy-focused machine learning operations and workload management.
MLOps: Using GPUs in Local, Docker, and Docker Compose Environments
Aprende a instalar PyTorch con soporte GPU y configura Docker y Docker Compose para aprovechar el poder de procesamiento gráfico en tus proyectos de aprendizaje automático.
Subglacial Water Flow Simulations on GPUs - JuliaCon 2024
Explore GPU-accelerated subglacial water flow simulations using Julia, enabling large-scale modeling of glacier dynamics and sea level rise predictions.
Cost-Effective GPU Solutions for AI Workloads with OpenStack - Optimization Strategies
Discover how to optimize AI workload costs using affordable GPUs and desktop workstations for cloud instances, with practical insights from ArcFusion AI and NIPA Cloud's successful implementation.
Processing 100+ GB of Data in Seconds Using Polars GPU Engine
Master high-speed data processing with Polars GPU engine, leveraging NVIDIA GPUs to handle massive datasets up to 10x faster while using familiar Polars syntax and commands.
Stable Diffusion 3.5 Medium - A Review of the New Text-to-Image AI Model
Explore Stable Diffusion 3.5 Medium's capabilities, comparing its performance against SDXL and other models while learning about its advantages for users with lower-end GPUs.
Perfect PC for AI, Object Detection and LLMs - Complete Guide
Learn how to build the optimal PC setup for AI development, focusing on computer vision, object detection, and large language model implementation.
Getting GPUDirect to Work with Broadcom NICs
Discover how to integrate Broadcom NICs with NVIDIA GPUs for enhanced packet processing using GPUDirect RDMA, exploring necessary DPDK ecosystem modifications and implementation steps.

1.2 Tb/s Packet Processing of Radio Telescope Data on GPU
Discover how to process massive radio telescope data streams at 1.2 Tb/s using NVIDIA Grace Hopper GPUs, optimizing packet handling and reducing energy consumption through innovative system architecture.
Enabling Cloud Workloads with the WEKA Data Platform
Discover how the WEKA Data Platform transforms data silos into dynamic pipelines, optimizing GPU performance and streamlining AI, ML, and HPC workloads in modern cloud environments.
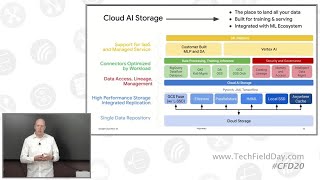
Optimizing Storage Solutions for AI and ML Workloads in Google Cloud
Discover advanced storage solutions optimized for AI/ML workloads, featuring Anywhere Cache, HyperDisk ML, and Cloud Storage FUSE innovations that enhance data accessibility and training efficiency.
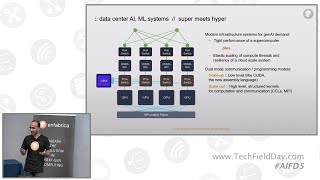
Accelerated Computing for AI Systems - A Network Architecture Perspective
Discover groundbreaking networking technology for AI computing with Enfabrica's ACFS system, offering 8Tb/s bandwidth and innovative solutions for modern data center challenges in distributed AI workloads.
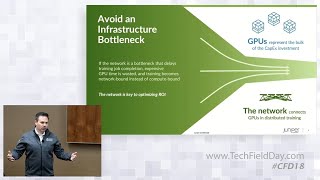
Automating AI Cluster Design with Juniper Apstra
Discover how to automate AI cluster designs using Terraform with Apstra, including GPU compute fabrics, storage fabrics, and NVIDIA-optimized rack configurations for efficient model training.
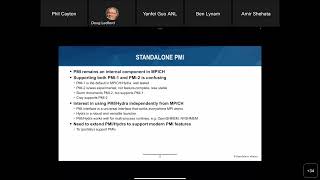
OpenFabrics Interfaces Support and GPU Integration in MPICH
Discover the latest updates on OFI integration in MPICH, focusing on GPU support implementation, network API enhancements, and Libfabric development for high-performance computing systems.
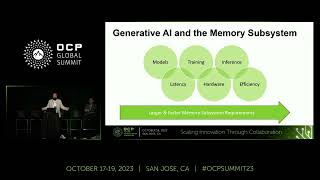
Scalability of Memory Subsystem in AI Storage Systems - IO Profiling and Performance Analysis
Explore IO profiling in AI systems, examining pipeline stages, metadata costs, and filesystem latency impacts on GPU performance, with solutions for optimizing storage systems.
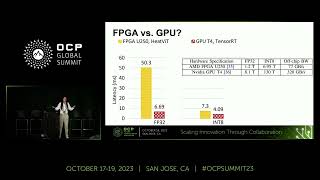
Architectural Challenges and Innovation for Compute Infrastructure Co-Design in Generative AI
Explore architectural solutions for generative AI computing challenges, focusing on heterogeneous computing infrastructure and chiplet-based systems for improved energy efficiency.
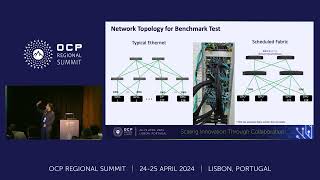
Scheduled Ethernet Fabric for Large-Scale AI Training Clusters
Discover how Scheduled Ethernet Fabric optimizes large-scale AI training clusters, enabling efficient GPU connectivity, workload management, and resilient networking for enhanced computational performance.