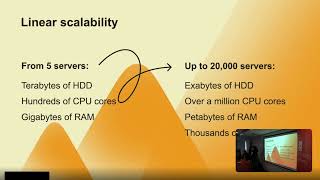
YTsaurus - The Next Generation of Open Source Big Data Platforms
Explore YTsaurus, an open-source big data platform for distributed storage and processing. Learn about its components, features, and capabilities for creating large-scale clusters up to 20,000 nodes.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 20
Explore Databricks Photon and Spark SQL's advanced features for efficient data processing and analysis in modern database systems.
Accelerating Apache Spark Workloads with Apache DataFusion Comet
Explore Apache DataFusion Comet's potential to enhance Apache Spark performance, optimizing data processing workflows and improving efficiency in large-scale analytics.
Apache Arrow DataFusion - A Fast, Embeddable, Modular Analytic Query Engine
Explore Apache Arrow DataFusion's fast, embeddable, and modular analytic query engine capabilities with insights from expert Andrew Lamb.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 18
Explore Databricks Photon and Spark SQL architectures, optimizations, and performance improvements in modern data processing systems.

Spark Unveiled: Essential Insights for All Developers
Discover Apache Spark's core concepts, architecture, and impact on data processing. Gain essential insights to enhance your development skills and unlock Spark's potential.

Understanding the SQL Aspects of Spark - Spark SQL
Explore Spark SQL's capabilities for distributed processing of structured data, integrating relational operations with Spark's high-performance engine.

Introduction to Databricks and Data Lakehouse Architecture
Explore Data Lakehouse, Databricks platform, Spark architecture, and SQL. Learn advantages and common use cases of Databricks for data processing.

State Storage in Spark Structured Streaming
Learn to configure and manage state storage in Spark Structured Streaming for efficient data processing and analysis.
Smooth Migration Practice from MapReduce to Spark at ByteDance
Learn ByteDance's smooth migration solution from MapReduce to Spark, reducing costs and improving performance. Explore design, implementation, and benefits of transitioning legacy jobs with minimal changes.
Apache Celeborn: Making Spark and Flink Faster, More Stable and More Resilient
Explore Apache Celeborn's high-performance Shuffle service for Spark and Flink, enhancing stability, performance, and cost-efficiency in large-scale data processing environments.
Introduction to Federated Learning with Flower - A Hands-on Tutorial
Explore federated learning with Flower framework. Learn AI training across devices, enhancing privacy without centralizing data. Includes hands-on tutorial and insights into reshaping AI while protecting sensitive information.
Deploying Distributed AI and Machine Learning in Financial Services
Discover how financial services leverage AI and ML in big data environments to overcome deployment challenges and deliver transformational business results.
AutoML Time Series Forecasting for Infrastructure Resources
Spark-based AutoML framework for scalable time series forecasting of IT infrastructure resources, enabling efficient long-term planning and daily dynamic provisioning.
Building a Multimodal Data Lakehouse with the Daft Distributed Python Dataframe
Explore Daft, a next-gen distributed query engine for processing multimodal data at scale. Learn to build a multimodal data lakehouse using familiar dataframe interfaces on existing infrastructure.

Discovery of the World's Biggest Prime Number
Discover the fascinating journey of Luke Durant's groundbreaking discovery of the world's largest prime number through interviews and insights from key figures in mathematical research.
Dynamical Systems in Neuroscience
Explore cluster computing and OpenMind for brain and cognitive sciences, covering dynamical systems, models, and observation techniques in neuroscience research.
Structure of Communication - Richard M. Karp Distinguished Lecture
Explore communication complexity, its applications, and structural conjectures in theoretical computer science with Shachar Lovett. Gain insights into efficient communication and its connections to various mathematical domains.
Linear Time and Efficient Distributed Algorithms for List Coloring Graphs on Surfaces
Explore efficient algorithms for list coloring graphs on surfaces, focusing on linear time complexity and distributed computing approaches.
Cookbook Lower Bounds for Statistical Inference in Distributed and Constrained Settings - Part 2
Explore advanced statistical inference techniques for distributed and constrained environments, focusing on lower bounds and their applications in complex data analysis scenarios.