Big Data Computing
Comprehensive exploration of big data technologies, covering Hadoop, Spark, key-value stores, streaming analytics, machine learning, and graph processing for large-scale data analysis and insights.
Cloud Computing
This course will introduce various aspects of cloud computing, including fundamentals, management issues, security challenges and future research trends. This will help students (both UG and PG levels) and researchers to use and explore the cloud computi…
Hadoop Tutorial for Beginners - Big Data Hadoop Tutorial
IT mavens like Google, Amazon and IBM as well as growing start-ups are always in search of Big Data experts. So we have come up with a tutorial on Apache Hadoop to help you get started on your Data Analytics path!
Hive Tutorial - Hive Architecture - Hadoop for Beginners - Big Data for Beginners
Comprehensive tutorial on Apache Hive, covering its architecture, SQL-like querying, and integration with Hadoop for efficient big data processing and analysis.
Programming the Internet - C4 Public Lecture
Explore the evolution of programming for internet-scale applications, addressing challenges in distributed computing, concurrency, and scalability through innovative methodologies and infrastructure changes.
Hadoop Tutorials
Learn Big Data and Hadoop essentials, including HDFS, MapReduce, YARN, Hive, and HBase. Explore career paths, architecture, and practical problem-solving in Hadoop ecosystems.
Hadoop Tutorials for Beginners
Comprehensive introduction to Big Data technologies, covering HDFS, MapReduce, Hive, Pig, Spark, NoSQL, HBase, Sqoop, Flume, and Kafka. Ideal for beginners seeking a solid foundation in Hadoop ecosystem.
Hadoop Tutorials
Simplified approach to Hadoop ecosystem: architecture, HDFS, MapReduce, YARN, security, and practical examples. Includes Google Cloud integration for hands-on experience.
Introduction to Reinforcement Learning - Distributed RL Systems - Lecture 9
强化学习分布式系统概述:探讨系统架构、参数更新方法、并行化策略,以及从DQN到AlphaStar的案例研究,深入分析分布式RL系统的发展和实现。
Trustworthy Data Analytics in the Cloud Using SGX
Explore trustworthy cloud-based data analytics using SGX technology. Learn about VC3, a system enabling secure MapReduce computations while preserving confidentiality and integrity of code and data.
How Companies Are Using Tachyon, a Memory Centric Distributed Storage
Explore Tachyon, a memory-centric distributed storage system for fast big data processing. Learn about its benefits, use cases, and integration with popular frameworks like Spark and Hadoop.
Master Databricks and Apache Spark - Introduction
Learn the fundamentals of Databricks and Apache Spark, exploring scale-up vs. scale-out concepts and laying the groundwork for mastering these powerful data processing tools.

Hadoop and Big Data with Java
Explore Hadoop and Big Data concepts in this NightHacking presentation, focusing on their integration with Java for efficient data processing and analysis.
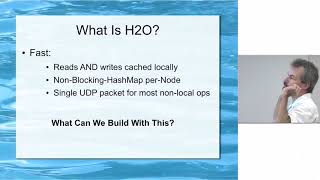
Big Data Processing on Small Computers
Explore distributed computing, MapReduce, and parallel programming techniques for handling big data on small-scale systems with expert insights.
Smooth Migration Practice from MapReduce to Spark at ByteDance
Learn ByteDance's smooth migration solution from MapReduce to Spark, reducing costs and improving performance. Explore design, implementation, and benefits of transitioning legacy jobs with minimal changes.
MapReduce and Distributed Computing for Data Mining - Spring 2023
Master distributed computing fundamentals through MapReduce, exploring cluster computing challenges, file systems, and practical applications like PageRank and community detection algorithms.
Research in Data Management - Challenges and Projects
Explore cutting-edge data management research, including VR/AR video databases, in-memory storage optimization, MapReduce frameworks, cardinality estimation, bias detection in OLAP queries, and automated query reasoning.
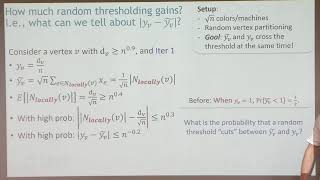
Graph Algorithms in the Massively Parallel Computation Model
Explore efficient graph algorithms in the Massively Parallel Computation model, focusing on techniques for near-linear memory regime and comparing MPC to other distributed/parallel models.
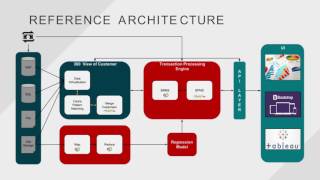
The Intersection of Business Rules Management and Big Data
Explore integrating JBoss BRMS with Hadoop for real-time decision-making in big data environments, focusing on anti-money laundering in financial services and retail applications.
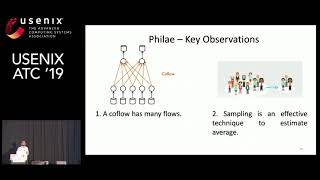
Your Coflow has Many Flows - Sampling them for Fun and Speed
Innovative coflow scheduling technique using flow sampling to estimate coflow size, improving performance and scalability for data-intensive applications in distributed computing environments.
Database Wizardry for Legacy Applications
Discover techniques to enhance legacy application databases using NoSQL and MapReduce, improving data consolidation and project performance without major structural changes.