DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
Master Databricks and Apache Spark - Introduction
Learn the fundamentals of Databricks and Apache Spark, exploring scale-up vs. scale-out concepts and laying the groundwork for mastering these powerful data processing tools.
Create a Spark Cluster - Master Databricks and Apache Spark Step by Step - Lesson 4
Learn to create and use Apache Spark clusters, understand their differences from Databricks, and explore data querying with Zeppelin notebooks in this step-by-step guide.
Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
Introducing Apache Spark 3.0 - A Decade of Progress and Future Outlook
Apache Spark 3.0: Reflecting on a decade of progress and unveiling new features to enhance data processing accessibility, speed, and compatibility across various sources and environments.
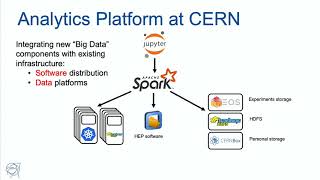
Deep Learning Pipelines for High Energy Physics Using Apache Spark and Distributed Keras
Explore CERN's Apache Spark-based data pipeline for deep learning in High Energy Physics. Learn about distributed training of neural network classifiers using BigDL and Analytics Zoo for improved event filtering at LHC experiments.
Apache Spark Core - Practical Optimization Techniques - Partition Shaping and Job Optimization
Explore Apache Spark optimization techniques, including partition shaping, join and aggregate optimizations, and multi-dimensional parallelism to maximize cluster utilization and eliminate data skew.
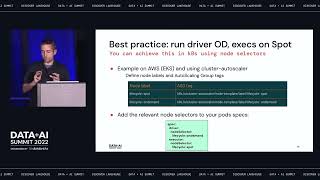
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.
Apache Spark on Kubernetes - Lessons Learned from Launching Millions of Spark Executors
Lessons learned from running massive Spark workloads on Kubernetes at Apple, covering orchestration, resource management, monitoring, and optimization for scalability and performance.
Adaptive Query Execution: Speeding Up Spark SQL at Runtime
Explore Spark SQL's Adaptive Query Execution framework, which optimizes query plans at runtime using real-time statistics for improved performance in data processing and analysis.
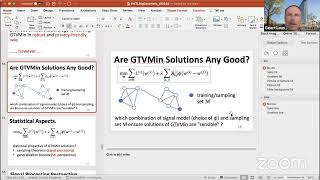
Federated Learning in Big Data Over Networks
Explore federated learning techniques for big data networks, focusing on distributed algorithms and privacy-preserving methods in large-scale data analysis.

Hadoop and Big Data with Java
Explore Hadoop and Big Data concepts in this NightHacking presentation, focusing on their integration with Java for efficient data processing and analysis.
Big Data Processing on Small Computers
Explore distributed computing, MapReduce, and parallel programming techniques for handling big data on small-scale systems with expert insights.
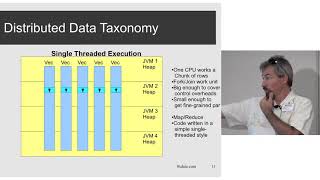
Big Data Analytics and Processing Techniques
Explore big data concepts, distributed systems, and analytics techniques with expert Cliff Click, covering data motion, compression, and efficient processing strategies.
Tools for Big Data - Professor Richard Gibbens, University of Cambridge
Explore mathematical modeling of networks with a focus on communication, transport, and energy systems. Learn to apply advanced computational techniques to analyze and interpret big data.
Big Problems with Big Data - Hadoop Interfaces Security
Explore Hadoop interfaces security challenges and solutions in big data environments, focusing on potential vulnerabilities and best practices for robust protection.
Efficient Data Parallel Distributed Training with Flyte, Spark and Horovod
Learn to optimize distributed training using Flyte, Spark, and Horovod for efficient data parallelism in machine learning workflows.
Designing High-Performance Scalable Middleware for HPC, AI, and Data Science in Exascale Systems and Clouds
Explore high-performance middleware design for exascale systems, focusing on MVAPICH2 project's features and performance in HPC, AI, and data science applications across various platforms.
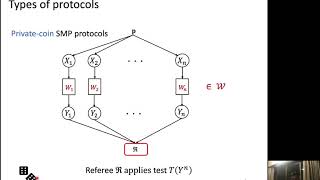
Cookbook Lower Bounds for Statistical Inference in Distributed and Constrained Settings - Part 3
Explore advanced statistical inference techniques for distributed and constrained environments, focusing on lower bound analysis and practical applications in complex data scenarios.
Tower of Babel - Making Apache Spark, Kubeflow, and Kubernetes Play Nice
Explore how Apache Spark, Kubeflow, and Kubernetes can work together to process big data matrices, denoise medical images, and create reproducible ML pipelines for COVID research and healthcare applications.
Federated and Collaborative Learning
Explore federated and collaborative learning approaches with Katrina Ligett, delving into innovative techniques for privacy-preserving data analysis and machine learning.