Best Practices in HPC and HTC Environments
Discover best practices for optimizing performance in High Performance and High Throughput Computing environments.
Scaling AI at Autodesk with Ray and Metaflow
Explore a 15-minute conference talk from Ray Summit 2024 where Thomas Gale and Peter Meltzer from Autodesk, alongside Savin Goyal from Outerbounds, demonstrate how Autodesk leverages Ray and Metaflow for large-scale 3D generative AI operations. Learn abo…
Scaling Ray to 10,000 NPUs - Huawei's Hyperscale Journey
Dive into Huawei's groundbreaking journey of integrating 10,000 Ascend NPUs with Ray, exploring technical innovations, observability solutions, and strategies for hyperscale AI infrastructure deployment.
Evolving Ray Core - Scalability, Reliability, and Compiled Graphs
Discover the latest advancements in Ray Core's architecture, including streaming generators, weekly releases, and the new Compiled Graphs backend for enhanced performance in accelerator-driven computing environments.
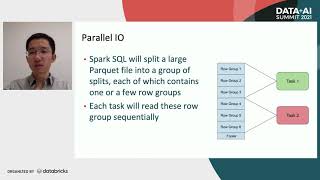
Optimizing Spark SQL Jobs with Parallel and Asynchronous IO
Optimizing Spark SQL jobs through parallel and async IO techniques, including file-level and row group-level parallel read, asynchronous spill, and parquet column family, resulting in 5-30% performance improvement.
Create a Spark Cluster - Master Databricks and Apache Spark Step by Step - Lesson 4
Learn to create and use Apache Spark clusters, understand their differences from Databricks, and explore data querying with Zeppelin notebooks in this step-by-step guide.
Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
Apache Spark Core - Practical Optimization Techniques - Partition Shaping and Job Optimization
Explore Apache Spark optimization techniques, including partition shaping, join and aggregate optimizations, and multi-dimensional parallelism to maximize cluster utilization and eliminate data skew.
Tools for Big Data - Professor Richard Gibbens, University of Cambridge
Explore mathematical modeling of networks with a focus on communication, transport, and energy systems. Learn to apply advanced computational techniques to analyze and interpret big data.
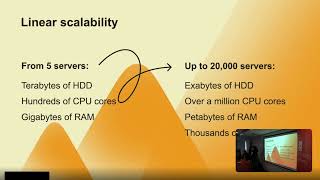
YTsaurus - The Next Generation of Open Source Big Data Platforms
Explore YTsaurus, an open-source big data platform for distributed storage and processing. Learn about its components, features, and capabilities for creating large-scale clusters up to 20,000 nodes.

Spark Unveiled: Essential Insights for All Developers
Discover Apache Spark's core concepts, architecture, and impact on data processing. Gain essential insights to enhance your development skills and unlock Spark's potential.
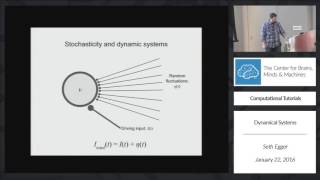
Dynamical Systems in Neuroscience
Explore cluster computing and OpenMind for brain and cognitive sciences, covering dynamical systems, models, and observation techniques in neuroscience research.
Distributed Database Computing: Installing Apache Cassandra Across Multiple Data Centers
Step-by-step guide to installing and configuring Apache Cassandra across multiple data centers, covering setup, configuration, and activation of a distributed database cluster.
MapReduce and Distributed Computing for Data Mining - Spring 2023
Master distributed computing fundamentals through MapReduce, exploring cluster computing challenges, file systems, and practical applications like PageRank and community detection algorithms.
Dimensionality Reduction II
Explore advanced dimensionality reduction techniques, including PCA and negentropy, with practical applications in brain and cognitive sciences. Includes exercises and research discussions.
Mesos - A Platform for Fine-Grained Resource Sharing in the Data Center
Explore Mesos, a platform for efficient resource sharing in data centers. Learn about fine-grained allocation, resource offers, and improved cluster utilization across diverse computing frameworks.
Distribute the Workload
Explore distributed systems and scalability techniques to enhance performance, redundancy, and availability of web services, inspired by ant colony principles.
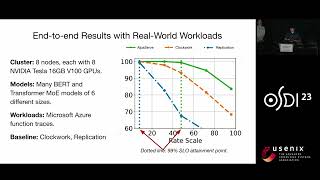
AlpaServe - Statistical Multiplexing with Model Parallelism for Deep Learning Serving
Explore AlpaServe, a novel system for efficient deep learning model serving using statistical multiplexing and model parallelism to handle bursty workloads and improve request processing rates.
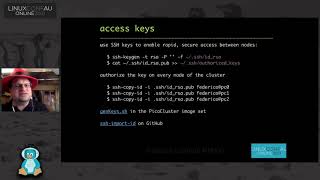
Building Raspberry PI Supercomputers
Learn to build and manage Raspberry Pi supercomputers, from cluster setup to parallel computing. Explore software integration, node configuration, and practical applications using MPI for numerical workloads.
Lessons Learned in X Years of Parallel Programming
Insights and practical examples on advanced parallel programming in Python, covering performance, debugging, and useful libraries for both enterprise and scientific applications.
Ray - A System for High-performance, Distributed Python Applications
Ray: open-source framework for scaling Python applications from laptop to cluster, solving performance challenges in ML/AI systems. Learn its features, use cases, and how it compares to alternatives.