Efficient Data Parallel Distributed Training with Flyte, Spark and Horovod
Learn to optimize distributed training using Flyte, Spark, and Horovod for efficient data parallelism in machine learning workflows.
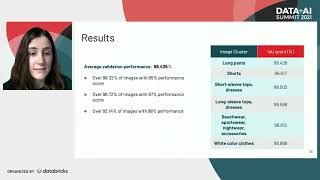
Automated Background Removal Using PyTorch - Wehkamp's Image Processing Pipeline
Discover an automated pipeline for efficient background removal in product images using PyTorch and machine learning, enhancing visual experiences for e-commerce customers.
Democratizing Deep Learning at Scale with Horovod
Explore Horovod's capabilities for scaling deep learning across distributed systems, enhancing efficiency and accessibility for AI practitioners and researchers.
Distributed Deep Learning on Apache Mesos with GPUs and Gang Scheduling
Explore distributed deep learning on Apache Mesos, leveraging GPU clusters for efficient model training in self-driving cars, trip forecasting, and fraud detection at UBER.
How Linux Foundation is Changing the Machine Learning World
Explore Linux Foundation's initiatives in AI, including open-source projects like Acumos AI and Horovod, aimed at reducing fragmentation and fostering collaboration in machine learning development.
Large Scale Distributed Deep Learning on Kubernetes Clusters
Explore distributed deep learning deployment on Kubernetes, comparing tf-operator and mpi-operator for TensorFlow training jobs, and optimizing resource utilization for better economics in machine learning tasks.
Horovod - Distributed Deep Learning for Reliable MLOps
Explore Uber's Horovod framework for distributed deep learning, covering its adoption, techniques, and integration with Spark for efficient large-scale model training and deployment.
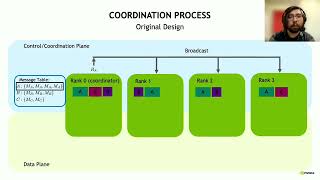
Accelerating Collective Communication in Data Parallel Training across Deep Learning Frameworks
Techniques to improve Horovod's communication efficiency in data parallel training, enhancing performance and scalability for deep learning frameworks on supercomputers.
Production Multi-node Jobs with Gang Scheduling, K8s, GPUs and RDMA
Explore distributed execution of DL/ML jobs in Kubernetes, covering gang scheduling, GPU acceleration, and high-speed networking for improved performance and scalability.
Machine Learning Using Kubeflow and Kubernetes
Explore machine learning workflows on Kubernetes using Kubeflow, covering deployment, training, inference, and advanced features like hyperparameter tuning and automated pipelines.
Predibase: A Low-Code Deep Learning Platform Built for Scale
Explore Predibase: a low-code deep learning platform combining large-scale ML with state-of-the-art architectures for NLP, computer vision, and tabular data, built on Ludwig and Ray for scalable, end-to-end solutions.