The Graph Database Interface: Scaling Online Transactional and Analytical Graph Workloads
Explore cutting-edge graph database technology scaling to 100,000+ cores. Learn about GDI, a new interface for high-performance, scalable graph processing in distributed memory systems.
Portable Communications Interface for Earth System Model - JuliaCon 2024
Explore ClimaComms.jl's high-level interface for Earth System Model components, enabling efficient communication patterns and distributed simulations across various architectures.
Applications of Distributed Task Parallelism
Explore distributed task parallelism in Julia, comparing Dagger with other frameworks and libraries. Learn about unique features for efficient, scalable, and maintainable code.
Beaver: Practical Partial Snapshots for Distributed Cloud Services
Innovative protocol for capturing partial snapshots in distributed cloud services, ensuring causal consistency without disrupting operations. Leverages load balancers for minimal changes and near-zero overhead.
MAST: Global Scheduling of ML Training across Geo-Distributed Datacenters at Hyperscale
Intelligent global scheduling system for ML training workloads across datacenters, optimizing resource utilization and eliminating regional overload through innovative design principles.
Power-aware Deep Learning Model Serving with μ-Serve
Explores μ-Serve, a power-aware model-serving system optimizing GPU frequency scaling and model multiplexing for energy-efficient deep learning workloads in homogeneous GPU clusters.
OPER: Optimality-Guided Embedding Table Parallelization for Large-scale Recommendation Models
Optimality-guided embedding table parallelization for efficient large-scale recommendation model training and inference, achieving significant speedups over existing frameworks.
Dependency Management in Spark Connect - Simple, Isolated, Powerful
Explore Spark Connect's new session-based dependency management system for dynamic updates and isolation in distributed computing, with practical examples for Python and Scala applications.
Optimizing Apache Spark and SQL for Improved Performance
Enhance Apache Spark and SQL performance through optimization techniques. Learn strategies for improved efficiency in data processing and analysis.
Fleet Is on Its Way
Explore Fleet, JetBrains' lightweight IDE with multi-language support, remote collaboration, and adaptive code insights. Learn its features and how it enhances developer workflows.
Machine Learning Using Kubeflow and Kubernetes
Explore machine learning workflows on Kubernetes using Kubeflow, covering deployment, training, inference, and advanced features like hyperparameter tuning and automated pipelines.
A Java 8 Lambda Is All You Need for Distributed Background Jobs
Discover JobRunr: transform Java 8 lambdas into distributed background tasks. Run CPU-heavy or I/O-intensive jobs asynchronously, scale effortlessly, and focus on delivering value to end users.
Inside TensorFlow - TF-Agents
Explore TF-Agents, TensorFlow's reinforcement learning library, with experts demonstrating its capabilities, architecture, and applications in game playing, bandits, and recommender systems.
Reducing Complexity and Increasing Performance with Trino
Explore Trino's capabilities for efficient data querying across diverse sources, optimizing pipelines, and enhancing analytics performance in complex data environments.
vLLM Inference and LLM Server Engine for Machine Learning
Discover how to leverage vLLM for efficient large language model inference and serving, including practical implementation techniques and deployment strategies.
IBM Storage Scale - A Global Data Platform for High-Performance Unstructured Data Management
Discover IBM Storage Scale's capabilities for high-performance data management, featuring policy-based lifecycle control, multi-protocol connectivity, and flexible deployment across core, edge, and cloud environments.

Demystifying AI and ML Infrastructure for Network Engineers
Discover how to build and optimize GPU clusters for AI workloads, focusing on inter-GPU networking, efficient communication protocols, and practical implementation using Cisco's infrastructure solutions.
Designing Networking Stacks for Machine Learning Frameworks
Dive into networking stack design for machine learning frameworks, exploring challenges, solutions, and real-world applications through NCCL case studies and prototype implementations.
Infrastructure Software for Hyperscale AI and GPU Clusters
Explore cutting-edge infrastructure software solutions powering large-scale AI operations and GPU cluster management for hyperscale computing environments.
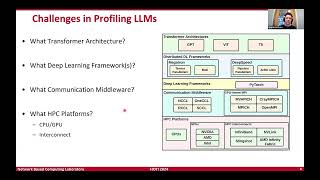
Demystifying the Communication Characteristics for Distributed Transformer Models
Explore communication patterns and optimization strategies for distributed transformer models, focusing on collective operations and performance characteristics in large-scale deployments.
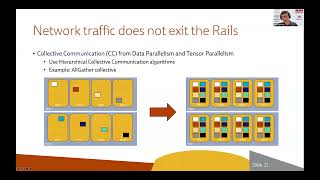
Rail-only: A Low-Cost High-Performance Network for Training LLMs with Trillion Parameters
Discover a groundbreaking network architecture designed for efficient training of large language models, optimizing performance while reducing infrastructure costs.