Building a Dynamic Rules Engine with Kafka Streams
Develop a real-time threat detection system using Kafka Streams. Learn to handle dynamic rule modifications, implement external data feeds, and apply best practices for stream processing.
Need for Speed: Machine Learning in the Era of Real-Time
Explore the evolution of real-time machine learning techniques, addressing low latency, dynamic data adaptability, and resource efficiency challenges in modern ML systems.
Building Nucleus: Community Brands' Real-Time Analytics Platform
Explore the architecture and design of a real-time analytics platform, featuring sub-second latency, cloud-native services, and CDC streams for efficient data processing and customer insights.
Handle Millions of IoT Devices Connected to Kafka via MQTT
Learn to manage massive IoT device networks using Kafka and MQTT for real-time data ingestion, analysis, and control in applications like vehicle communication and predictive maintenance.
Creación de una Data Pipeline con KPIs - Fluentbit, Kafka, Python y PostgreSQL
Aprende a crear una Data Pipeline eficiente utilizando fluentbit, Kafka, Python y PostgreSQL. Domina la generación de KPIs y explora herramientas como CloudBeaver.
Pandas and Dask DataFrame 2.0 - Comparison to Spark, DuckDB and Polars
Explore Dask DataFrame 2.0's improvements and performance compared to Spark, DuckDB, and Polars. Learn about new features, benchmarks, and future developments in distributed computing with Python.
Python and SQL: Better Together, Powered by DuckDB
Explore DuckDB's integration with Python for efficient data processing, combining SQL and dataframe capabilities to handle large datasets with ease and speed.
The End of History? Convergence of Batch and Realtime Data Technologies
Explore hybrid approaches like Lambda and Kappa architectures for combining batch and real-time systems. Learn about SaaS platforms and managed services that simplify implementation of these powerful data technologies.
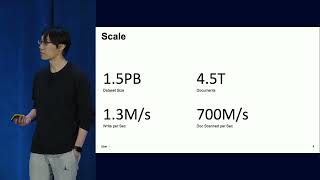
Scaling Uber's Metric System from Elasticsearch to Apache Pinot
Explore Uber's journey in scaling their metric system, transitioning from Elasticsearch to Apache Pinot for improved reliability and performance in real-time data processing.
CDC Stream Processing with Apache Flink
Explore Apache Flink's capabilities as a data integration hub, focusing on its SQL engine for changelog processing, CDC data handling, and materialized view maintenance. Learn about data source semantics and system integrations.
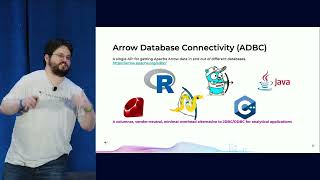
Making Moves with Arrow Data: Introducing Arrow Database Connectivity (ADBC)
Explore Arrow Database Connectivity (ADBC), a new Apache Arrow subproject for Arrow-based database access. Learn its goals, use cases, and communication with data APIs using Arrow-native in-memory data.
Change Data Streaming Patterns with Debezium and Apache Flink
Explore change data capture with Debezium and Apache Flink for microservices. Learn outbox pattern, strangler fig pattern, and saga orchestration for reliable data exchange and long-running transactions.
Ten Years of Building Open Source Standards: From Parquet to Arrow to OpenLineage
Explore the journey of building open-source data standards, from Apache Parquet to Arrow to OpenLineage. Gain insights into successful project ideation, growth, and ecosystem impact in data management.
When to Move from Batch to Streaming and How to Do It Without Hiring an Entirely New Team
Demystify the transition from batch to real-time processing. Learn arguments, architectures, pitfalls, and open-source tools for stream processing without overhauling your team.
Real-time Schema Discovery in Distributed Systems
Explore real-time schema discovery in high-volume distributed systems. Learn about schema versioning, conflict detection, compatibility, and normalization without batching processes.
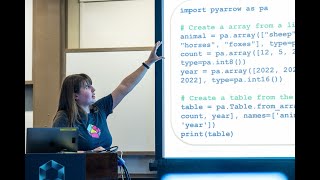
Time Series Analytics with Apache Arrow, Pandas, and Parquet - A 101 Introduction
Explore efficient time-series data handling using Apache Arrow and Parquet. Master open-source technologies for high-performance analytics applications.
Building an Open Data Service Layer with Arrow, DuckDB and Semantic Layer
Explore FlexQuery, an open-source solution revolutionizing data services with Arrow, DuckDB, and semantic layers. Learn to create high-performance, scalable analytics environments using Python and cutting-edge technologies.
Ten Years of Building Open Source Standards in Data Engineering
Explore a decade of open-source standards development, from Parquet to Arrow. Gain insights into community-driven innovation and the evolving landscape of data engineering.
Building a Unified Feature Platform with DuckDB and Arrow
Explore ML feature platform development using DuckDB and Arrow. Learn scaling strategies, DuckDB extension implementation, DeltaLake interoperability, and performance comparison with Spark.

Building InfluxDB 3.0 with Apache Arrow, DataFusion, Flight and Parquet
Explore InfluxDB 3.0's innovative design using Apache Arrow, DataFusion, Flight, and Parquet. Discover how this deconstructed database system enables fast, high-quality data analysis and advanced interoperability.
From Zero to Multilingual Next.js Site with Next-drupal and Drupal Recipes
Build a multilingual Next.js site with Drupal backend using a single command. Explore features like preview mode, on-demand updates, SEO support, and more in this comprehensive template.