A Gentle Introduction to Vector Databases
Explore vector databases, semantic search, and machine learning models for unstructured data processing. Learn about Weaviate and see a practical demo of vector search in action.
The Future of Application Development - Cloud Native Summit
Explore Kappa architecture, stream processing, and LLM integration for innovative application development. Learn to build scalable systems leveraging real-time data and AI capabilities.
A Practical Approach to Measuring Relevance in E-commerce Search Engines
Implement a component to measure e-commerce search engine relevance using NDCG theory. Learn practical details, integration, and ROI for preventing relevance regressions.

Testing in Apache Solr - Session 3
Explore Solr's testing capabilities, learn to contribute effectively, and master techniques for writing and managing tests in Apache Solr.
Dive into NLP with the Elastic Stack
Explore practical NLP applications using Elasticsearch, including semantic vectorization, semantic search, named entity recognition, multimodal search, and automatic classification.
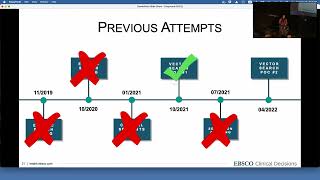
Vector Search for Clinical Decisions
Explore EBSCO's journey in implementing vector search for clinical decision support, addressing challenges in precision and recall for complex medical queries.
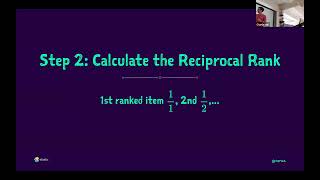
Reciprocal Rank Fusion (RRF) - How to Stop Worrying about Boosting - Lecture
Explore Reciprocal Rank Fusion (RRF) for combining search results, its advantages over boosting, and implementation in various systems. Learn from Philipp Krenn's expertise in search technology.
Mastering Hybrid Search: Blending Classic Ranking with Vector Search - Haystack EU 2023
Explore hybrid search systems combining classic ranking and vector search. Learn best practices for enhancing relevancy, managing performance-accuracy tradeoffs, and scaling to production.
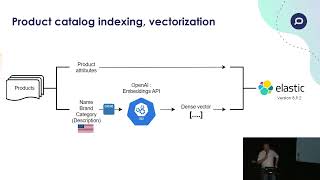
Vector (Hybrid) Search Live A/B Test Results in E-commerce Sector
Explore significant A/B test results of Vector (Hybrid) Search in e-commerce, revealing revenue increases and improved user engagement. Learn about embedding creation and result blending techniques.
Retro Relevance: Lessons Learned Balancing Keyword and Semantic Search
Explore strategies for enhancing search relevance by combining traditional keyword-based methods with semantic search, addressing limitations and improving user satisfaction.
Expanding RAG with Multimodal Capabilities - Haystack US 2024
Explore multimodal RAG workflows for enhanced retrieval and generation, incorporating text, tables, and images. Live demo showcases PDF processing, vector database usage, and LLM-enriched responses.
Using MLflow and Databricks to Deploy ML Models in Production
Explore MLflow and Databricks for production ML model deployment. Learn end-to-end management, model tracking, and deployment strategies, plus Databricks' Feature Store and AutoML.
Introduction to Data Engineering - Best Practices and Production-Level Infrastructure
Learn best practices for scaling data science projects from local to production, covering infrastructure, reliability, and real-world applications in data engineering.
Using the FLiPN Stack for Edge AI
Explore the FLiPN stack for building fast IoT and AI applications. Learn how Apache Flink, NiFi, and Pulsar combine to create scalable streaming solutions for edge computing and rapid data ingestion.
Spark at Scale: Engineering Strategies for Data Science Workflows
Optimize PySpark applications and slash runtimes using engineering strategies for data science workflows, illustrated through a case study on in-store availability reporting.
Vector and Hybrid Search with Elasticsearch
Explore vector and hybrid search in Elasticsearch, covering classic search limitations, models, implementation, and integration with LLMs like ChatGPT for enhanced data retrieval.
Leveraging Databricks for Advanced Geospatial Analysis
Explore advanced geospatial analysis using Databricks. Learn to process spatial data at scale, integrate GIS with big data analytics, and utilize the H3 index for efficient grid-based operations.
7 Tips to Ensure Your Data Project Succeeds
Discover 7 crucial tips for successful data projects. Learn to overcome common pitfalls, exceed expectations, and deliver tangible business outcomes in big data initiatives.
A Gentle Introduction to Event Streaming and Processing Using Apache Pulsar
Explore event-driven systems, Apache Pulsar's unique capabilities in cloud-native applications, and its advantages over Apache Kafka. Learn about integrating Pulsar with Spring framework.
The Path to Real-time Data Integration with Open Source
Explore real-time data integration using SymmetricDS, an open-source solution for syncing databases. Learn to set up and scale data replication across various platforms for improved service offerings and customer insights.
Spinning Your Drones with Cadence Workflows, Apache Kafka and TensorFlow
Explore building a real-time drone delivery app using Cadence and Apache Kafka, then apply TensorFlow for machine learning on streaming data to predict busy shops.