Streaming ETL on the Shoulders of Giants
Explore configuration-based streaming ETL pipelines between MongoDB and Apache Kafka using Kafka Connect framework, focusing on data integration scenarios without coding.
Finding Needles in Ever Increasing Haystacks - Scalability with Elasticsearch
Explore Elasticsearch's distributed architecture, efficiency, and resilience for modern data challenges. Learn about ingestion, sharding, replication, and search distribution techniques.
The Data Lakehouse for Streaming Data - A Talk for Everyone Who Loves Data
Explore data lakehouses: combining data lakes and warehouses for reliable, flexible data management. Learn about open-source projects, streaming data support, and see a live Twitter sentiment analysis demo.
Unlocking the Power of Big Data, Analytics & AI
Explore Payzy, a mobile app revolutionizing e-transactions in Greece. Learn about its innovative tech stack, including AI-powered features like conversational assistants and recommendation systems.
Developing a Stream Processing Application with Apache Kafka and Quarkus
Learn to build high-performance event-driven microservices using Apache Kafka and Quarkus. Explore common patterns, live coding, and integration with Quarkus' reactive core for smooth development.
The Data Lakehouse - A Tech Talk for Everyone Who Loves Data
Explore data lakehouses: combining data lakes and warehouses for reliability, governance, and flexibility. Learn about open-source projects, streaming data, and future improvements through live demos and code examples.
Building ML Workflows with Java, Python & Apache Beam
Learn to create multi-language ML pipelines using Apache Beam, combining Java for data processing and Python for ML modeling in batch and streaming workflows.

Stream All Things - Patterns of Modern Data Integration
Explore modern data integration patterns, focusing on event streaming with Apache Kafka. Learn about microservices, compatibility, and innovative approaches to handling complex data challenges.

Apache Spark Beyond Shuffling - Why it isn't Magic - but also where there is some really cool Magic
Apache Spark performance deep dive: scaling challenges, RDD operations, key skew issues, and optimization techniques for distributed data processing. Insights from an IBM Spark engineer.
Monitor Your Containers with the Elastic Stack
Explore container monitoring using the Elastic Stack. Learn challenges of logging containerized apps and discover solutions for effective monitoring in microservices architectures.
Humio - A Fast & Efficient Way to Understand Log Data
Explore real-time log data analysis with Humio, a fast and efficient solution for managing large-scale log datasets. Learn techniques for explorative querying and cost-effective log management.
Speed is Not All You Need for Data Processing
Exploring data processing frameworks beyond Pandas, challenging assumptions about speed, and emphasizing practical considerations for choosing tools that best serve data practitioners.
Reducing Complexity and Increasing Performance with Trino
Explore Trino's capabilities for efficient data querying across diverse sources, optimizing pipelines, and enhancing analytics performance in complex data environments.
Using Kafka at Scale - A Case Study of Microservices Data Pipelines at Evernorth Health Services
Explore a case study on implementing Kafka-based microservices data pipelines at scale in Evernorth Health Services, showcasing real-world applications and challenges.
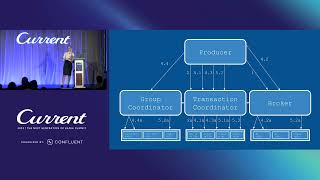
Transactions in Action: The Story of Exactly Once in Apache Kafka
Explore Apache Kafka's transaction evolution, from KIP-98 to KIP-890, covering idempotency, protocol improvements, and solutions for hanging transactions.
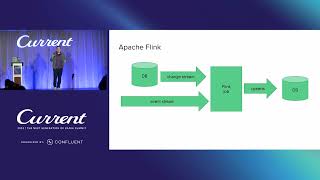
Deeply Declarative Data Pipelines with Flink and Kubernetes
Explore declarative streaming data pipelines on Kubernetes using Flink and SQL. Learn to simplify development, integrate systems, and optimize configurations for efficient stream processing.
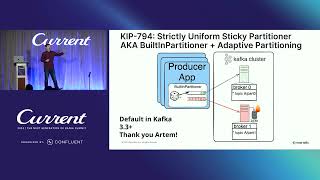
Mitigating Kafka Broker 'Gray' Failures for Key-Based Partitioners with Partition Multihoming
Explore partition multihoming (PMH) to mitigate Kafka broker gray failures, enhancing reliability for key-based partitioning. Learn implementation details, workflow, and future roadmap for virtual partitioning in Apache Kafka.
Our Multi-Year Journey to a 10x Faster Confluent Cloud
Explore the multi-year journey to enhance Confluent Cloud's performance, learning about workload design, cloud-native complexities, challenges faced, and key principles for improving data streaming systems.
Build Real-time Machine Learning Apps on Generative AI with Kafka Streams
Develop real-time ML applications using Generative AI and Kafka Streams, leveraging data in motion for intelligent, streaming-based solutions.
Power BI and Azure Synapse Analytics: Beginning Your Journey
Explore Power BI and Azure Synapse Analytics integration, learning effective data leveraging techniques to maximize insights and optimize your data strategy.

The Future Roadmap for the Composable Data Stack
Explore advancements in data processing with Wes McKinney. Learn about Parquet, Arrow, and interface libraries like Ibis and tidyverse. Gain insights into current project states and future innovations.