
Zookeeper in Action
Explore ZooKeeper's potential for managing application clusters, focusing on real-time data processing and automatic scalability in monitoring and alerting systems.
Continuous Deployment of Machine Learning Models
Explore real-time ML model deployment at Auto Trader UK, featuring automated retraining, robust testing, and integration with existing infrastructure for efficient experimentation and reduced time-to-live.
Deep Learning con DL4J e Apache Spark
Esplora il Deep Learning distribuito con DeepLearning4J, ND4J e Apache Spark. Scopri potenzialità e sfide nell'implementazione di reti neurali multilayer su diverse modalità di deployment di cluster Spark.

Live Kubernetes Debugging with the Elastic Stack
Hands-on guide to troubleshooting Kubernetes apps using Elastic Stack, covering health checks, monitoring, tracing, logs, and deployment analysis for efficient problem-solving.
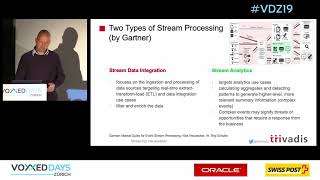
Streaming Visualisation
Explore streaming data visualization techniques, from traditional approaches to dedicated solutions. Learn architecture blueprints and tools for real-time data analysis and presentation.
Reacting to the Future of Application Architecture
Explore nature-inspired reactive architecture for efficient, resilient software solutions. Learn from honeybees to create responsive applications using frameworks and real-world examples.
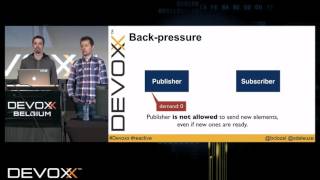
Developing Reactive Applications with Reactive Streams and Java 8
Learn to build reactive applications using Reactor Core 3.0, exploring its powerful API based on Java 8 and Reactive Streams. Gain practical skills through live coding and real-world use cases.
Elasticsearch + Hibernate - From Artisanal to Industrial Integration
Discover how Hibernate ORM and Elasticsearch can be seamlessly integrated, enabling automatic data synchronization and efficient querying between relational databases and search indexes.
Sentiment Analysis of Social Media Posts Using Apache Spark
Practical demonstration of sentiment analysis on Reddit comments using Apache Spark, covering implementation, data processing, and results visualization for large-scale social media content analysis.
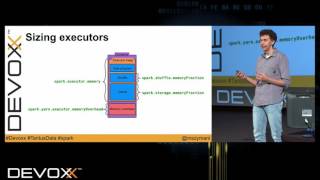
Apache Spark? If Only It Worked
Practical guide to optimizing Apache Spark applications, covering common issues like data skew, memory management, caching, and executor sizing for improved performance and stability.
And the Beats Go On
Explore new data shippers for Elasticsearch: Packetbeat for network packets, Metricbeat for machine metrics, and Filebeat for log files. Learn to build custom beats with Libbeat.
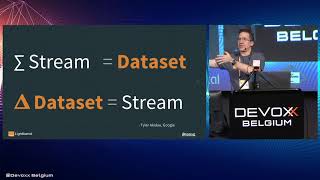
Processing Fast Data with Apache Spark - The Tale of Two Streaming APIs
Explore Apache Spark's streaming APIs for fast data processing, comparing Spark Streaming and Structured Streaming through practical examples and guidance on implementation.
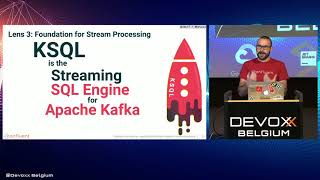
Embrace the Anarchy - Apache Kafka’s Role in Modern Data Architectures
Explore Apache Kafka's role in modern data architectures, focusing on its streaming platform capabilities, ecosystem, and design patterns for addressing enterprise data flow challenges.
Data Stream Processing - Concepts and Implementations
Explore data stream processing concepts, including time handling, Dataflow API, stream-table duality, data lookup, and deployment strategies. Compare implementations in Apache Spark Streaming, Flink, and Kafka Streams.
How Uber Audits Real-Time Infrastructure of Trillion+ Messages
Explore Uber's Chaperone system for auditing real-time infrastructure handling trillions of daily messages. Learn about its design, implementation challenges, and lessons learned in scaling massive data flows.
Building Serverless AI Powered Applications on AWS
Explore serverless AI applications on AWS using Amazon Rekognition and Polly. Build image analysis and podcast generation systems with practical demos and deployment techniques.
GeoSpatially Enabling Your Big Data Apache Clusters with LocationTech
Explore geospatial data processing at scale using LocationTech projects. Learn about challenges, solutions, and integration with Apache frameworks for analyzing large-scale location-based information.
What Are Observables and Why Should I Care
Explore Observables: next-gen async abstraction. Learn high-level concepts, tackle typeaheads, and dive into stream processing for machine learning. Gain confidence in harnessing Observables to simplify asynchronous programming.
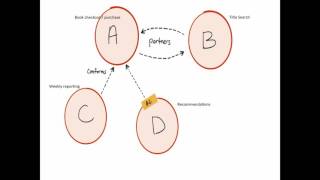
The Hardest Part of Microservices - Your Data
Explore data challenges in microservices, using Domain Driven Design to manage complexity. Learn about transactional boundaries, CAP theorem, and technologies like Kafka and Camel for building scalable, autonomous systems.
Fast Cars, Big Data - How Streaming Can Help Formula 1
Explore real-time data streaming and analysis in Formula 1 racing using Apache Kafka, Spark, and Drill. Learn how to capture, process, and visualize high-volume automotive data for performance insights.
Improve Your App UX with One Model Processing Insights from Batch and Streams
Learn to enhance app UX using a unified model for batch and stream processing. Explore Dataflow's capabilities through a real-time demo, gaining practical insights on managing and visualizing data streams.