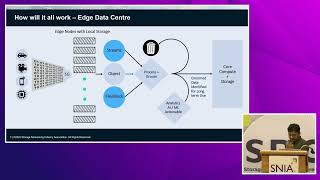
Cloud Native Storage Services for Edge Computing - Understanding Data Sources and Architectures
Explore cloud-native storage architectures for edge computing, covering data types, storage services, and operating models across far edge, enterprise edge, and network edge environments.
AWS EMR Demystified - Part 3
Master AWS EMR's integration with Glue, Athena, and PySpark while learning essential data transformation techniques and architectural considerations for optimizing your data lake implementation.
A Journey of Audit Logs from Kafka to Elasticsearch - Building a Centralized Logging Platform
Discover how to build a scalable audit logging platform using Kafka and OpenSearch, focusing on tracking data modifications across multiple users and data models in business-critical systems.

DuckDB: Crunching Data Anywhere - From Laptops to Servers
Discover how DuckDB enables efficient data analysis across devices, from processing hundreds of gigabytes on laptops to terabytes on servers, with native support for SQL and popular file formats.
Apache HBase on Ozone - Data Storage and Computing
Discover how Apache HBase integrates with Ozone for enhanced distributed storage capabilities, exploring architecture, deployment strategies, and performance optimization techniques.
How Data Hub Flies Above the Clouds - Building a Centralized Social Media Analytics Platform
Discover how to build a centralized data platform using Azure services, integrating social media data through Data Lake, Databricks, and Power BI for comprehensive analytics and reporting.

Benchmarking Storage with AI Workloads - Performance Analysis and Optimization
Explore how storage systems impact AI/ML workload performance through comprehensive benchmarking analysis, focusing on data ingestion, training patterns, and inference workload optimization.
Indexify Unveiled: A Scalable Content Extraction Engine for Multimodal Data
Discover how Indexify enables scalable content extraction and real-time knowledge base creation for AI workflows, focusing on unstructured data processing and hybrid search capabilities.
Kafka for .NET Developers
Discover how to leverage Kafka's streaming capabilities in .NET applications, from basic concepts like records and offsets to advanced features including Connect and Flink, with practical code examples.
PySpark Best Practices
Learn best practices for PySpark, including dependency management, code structuring, testing, and performance optimization. Gain insights on writing efficient and scalable Python applications using Spark's distributed computing model.
The Human Factors of Running a Data Driven Company
Insights on building a data-driven culture at QuizUp, focusing on team structure, communication, and leveraging data across the organization to inform product decisions.

Db2 SQL All-in-One Quick Start Tutorial Series
Comprehensive introduction to Db2 SQL covering database fundamentals, data structures, CRUD operations, relationships, and normalization for beginners and intermediate users.
Intro to NoSQL and JSON
Explore NoSQL databases and JSON format for handling unstructured data in modern applications. Learn key concepts and benefits for efficient data management.
DataSource V2 and Cassandra - A New Era of Speed and Flexibility
Explore DataSource V2 in Spark Cassandra Connector: enhanced speed, flexibility, and usability. Learn about Spark's understanding of Cassandra clustering and direct catalogue manipulation for improved data integration and analysis.
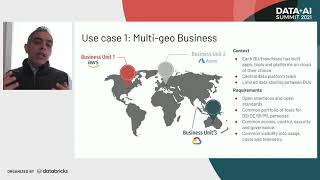
Managing a Multi-Cloud Data and Analytics Platform - Challenges and Solutions
Learn to manage a multi-cloud data and analytics platform, addressing challenges and leveraging benefits across major cloud providers for enterprise-level data, analytics, and AI solutions.
From Python to PySpark and Back Again - Unifying Single-Host and Distributed Deep Learning with Maggy
Unifying single-host and distributed deep learning with Maggy framework, enabling seamless transition from laptop to cluster for efficient model development and training using TensorFlow and PySpark.
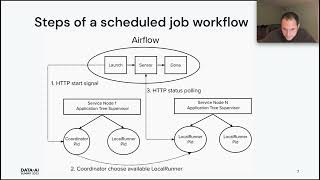
Elixir for Data Engineering - Batch and Stream Processing
Discover how Elixir can revolutionize data engineering with distributed processing, Airflow integration, and Kafka event handling. Learn practical examples for efficient batch and stream processing.
Architecting for Data Quality in the Lakehouse with Delta Lake and PySpark
Learn techniques for ensuring data quality in lakehouses using Delta Lake and PySpark. Explore data observability, reliability lifecycle, and practical implementation of quality checks across metadata, storage, and query layers.
Sound Data Engineering in Rust - From Bits to DataFrames
Explore Rust for efficient data engineering, from low-level bit manipulation to high-performance DataFrames using Apache Arrow. Learn optimization techniques and benchmarks for improved data processing.
Introduction to Azure Data Services One by One
Explore Azure's diverse data services, from SQL Database to Databricks, understanding their purposes and use cases to make informed choices for your data management needs.

Azure Databricks - Azure + Spark + Machine Learning
Explore Azure Databricks: Combine Azure, Spark, and machine learning. Learn key features through demonstrations and understand its advantages for big data processing and analytics.