Streaming Apache Kudu Within Apache Flink
Unlock continuous data streaming from Apache Kudu with a custom Flink source connector. Learn the design and implementation for seamless integration.
Build a Stream Graph Processing System Based on Apache Calcite and Gremlin
Explore building a streaming graph engine using Apache Calcite and Gremlin. Learn about GeaFlow's query language and its applications in real-time graph processing at Ant Group.
Building a Real-Time Analytics Database
Odkryj tajniki tworzenia bazy danych do analityki w czasie rzeczywistym. Poznaj kluczowe koncepcje i najlepsze praktyki w tej dziedzinie.
Visual Data Analytics - A Short Tutorial
Explore visual data analytics techniques for large datasets, bridging data mining and HCI to solve real-world problems with scalable interactive tools.
Caching for Jupyter Notebooks
Aprenda técnicas de caching para acelerar o desenvolvimento em Jupyter Notebooks, melhorando o fluxo de trabalho e reduzindo o tempo de espera em células dispendiosas.
MLOps at Scale: Predicting Bus Departure Times Using 18,000 ML Models
Explore MLOps at scale through a case study on predicting bus departure times using 18,000 ML models. Learn practical insights for implementing large-scale machine learning projects.
Building and Operating an Open Source Data Science Platform
Develop an end-to-end data analytics pipeline, from exploratory analysis to model deployment. Learn pipeline orchestration, distributed training, automation, and monitoring for scalable machine learning projects.
Deploying Distributed AI and Machine Learning in Financial Services
Discover how financial services leverage AI and ML in big data environments to overcome deployment challenges and deliver transformational business results.
Unveiling the Power of IoTDB Stream Processing Engine in Industrial IoT Edge-Cloud Applications
Discover how IoTDB's stream processing engine revolutionizes Industrial IoT with real-time data handling and edge-cloud integration for enhanced operational efficiency.
Retail Transactions at Scale for AI - From PoC to Production
Discover how to scale AI solutions for retail transactions, from handling millions of unstructured data points to enabling enterprise-wide AI applications and reporting capabilities.
Analyzing Daily Bank Transactions: Maximizing Insights for Credit Risk Assessment
Discover how to leverage daily bank transaction data for real-time credit risk assessment, transforming traditional financial analysis into dynamic insights for better decision-making.
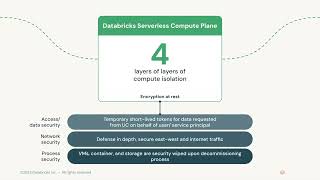
Databricks Serverless Security - Serverless Compute Isolation
Explore Databricks' serverless compute isolation techniques, including defense-in-depth strategies and multi-layered security measures to minimize risks in the intelligent data warehouse environment.
Version Control for Lakehouse Architecture - Essential Practices and Benefits
Discover how to implement data version control using lakeFS for improved data quality, reproducibility, and experimentation in Databricks data/ML pipelines, enhancing overall product value.
Streaming Data Enrichment and Analysis with Redpanda, CDC, and Python
Explore real-time data enrichment using streaming platforms, Debezium for CDC, and Python-based ML for sentiment analysis. Learn strategies for data aggregation and visualization in modern streaming architectures.

Compute Engine Testing with Synthetic Data Generation
Explore Meta's innovative testing framework using privacy-safe synthetic data for compute engines, enhancing regression detection, test coverage, and release cycles in data warehousing.
Streamline Real-Time Ingestion and Serving with DLT and Online Tables
Västtrafik improves public transport efficiency using near real-time data ingestion for its Travel Planner App. Learn how Delta Live Tables and Brickstore optimize low-latency pipelines, balancing cost and performance.
Building Data Applications on Databricks in 20 Minutes
Learn to create data apps for non-technical users, enabling data-driven decisions. Explore rapid app development using Python frameworks, data access methods, security, governance, and production deployment on Databricks.
Default Storage - Fast Track to Databricks Data Intelligence Platform
Explore Databricks' Default Storage feature for seamless data management. Discover pre-configured storage, built-in security, and Unity Catalog integration for a comprehensive SaaS lakehouse experience with unified data access.
Ocean Cleanup's Efforts to Remove Ocean Plastic - Leveraging Databricks
Databricks supports Ocean Cleanup's mission to remove 90% of ocean plastic by 2040, enhancing computer vision models, developing impact reporting, and streamlining data architecture for more efficient operations.
Best Features of Delta Lake - Love Your Open Tables
Explore Delta Lake's key benefits for data analysis, including Liquid Clustering, UniForm, and interoperability with various engines like Spark, Trino, and Pandas.
Creating Optimized Thematic Portfolios with Bloomberg Enterprise Data
Learn to build custom thematic investing tools using Bloomberg data and Databricks Platform. Explore cloud-based data management, machine learning, and visualization techniques for portfolio optimization.