Building Hyper-Personalized LLM Applications with Rich Contextual Data - DE4AI
Explore the concept of Full RAG (Retrieval-Augmented Generation) and its potential to revolutionize user experiences across industries in this 28-minute talk by Mike Del Balso, co-founder of Tecton. Examine four levels of context personalization, from ba…
Unified Data and AI Governance with Unity Catalog
Explore the challenges of fragmented governance in multi-vendor data and AI landscapes and discover how Unity Catalog can revolutionize your organization's governance strategy. Learn about the complexities and inefficiencies arising from tool sprawl in c…
Real-Time Data Streaming Architectures for Generative AI
Explore the evolution of data processing architectures for Generative AI in this 12-minute talk by Emily Ekdahl at the MLOps.community event. Discover how real-time data streaming solutions using Apache Kafka and Apache Flink are revolutionizing the way…
Chronon: Airbnb's Open-Source Data Platform for AI and ML Applications
Explore Chronon, an open-source data platform for AI and ML applications, in this 13-minute talk by Nikhil Simha, CTO and co-founder of zipline.ai. Discover the technical problems Chronon solves and how organizations can leverage it to accelerate their A…

Data and AI World Tour 2024 Bangkok - Deep Dive on Data Management, AI, and Industry Applications
Dive into a comprehensive 2.5-hour conference session from the Data + AI World Tour 2024 in Bangkok, exploring cutting-edge technologies in data management, warehousing, governance, and generative AI for enterprises. Gain insights from industry leaders o…
Putting the AI Back in Medallion Lake Design
Explore a comprehensive analysis of lakehouse design and its integration with AI in this insightful 13-minute talk by Simon Whiteley, a Databricks Beacon and Microsoft MVP. Delve into the challenges companies face when adopting lakehouses and learn how t…

A Kafka Producer's Request: From Send() to Disk and Back
Explore the intricate journey of data into Apache Kafka® in this 49-minute conference talk from Devoxx. Delve into the complex process behind the seemingly simple producer.send() call, tracing the path of a request from its inception to disk storage and…
Data Streaming with Confluent: Stream, Connect, Govern, and Process Information
Explore the world of data streaming through this 39-minute conference talk from Devoxx. Dive into Confluent's Data Streaming Platform and discover how to Stream, Connect, Govern, and Process large volumes of information effectively. Learn about the revol…
Realtime Streaming for Anomaly Detection - An End-to-End Data Engineering Project
Build a real-time anomaly detection system using streaming data engineering techniques. Learn end-to-end implementation for monitoring and identifying unusual patterns in data streams.

15 Essential Do's and Don'ts with Apache Kafka
Discover 15 crucial best practices for Apache Kafka, covering naming conventions, replication, partitioning, data quality, and more. Gain practical insights to optimize your Kafka environment.
Data Versioning in Generative AI: A Pathway to Cost-Effective ML
Explore data versioning strategies for Generative AI, focusing on managing large-scale unstructured data and optimizing resource usage in model scoring and API interactions.
Quick Deploy Model Serving in Ranking Systems
Discover how to streamline model deployment in ranking systems using ElasticSearch plugins and MLeap bundles for efficient, error-free updates and seamless integration with existing infrastructure.
Systematic Approaches and Creativity - Building DoorDash's ML Platform During the Pandemic
Explore DoorDash's ML platform development journey, focusing on collaboration, guardrails, principled approaches, and architecture powering billions of daily predictions for diverse use cases.
Cloud Platform Observability: Streaming Logs from AWS Firehose to Dynatrace
Integrate AWS Firehose logs with Dynatrace Grail for AI-powered observability. Learn setup, analysis, and multi-cloud log management to mitigate issues and enhance security.
How Not to Let Your Data and Model Drift Away Silently
Discover strategies to prevent data and model drift, ensuring ML models maintain performance and value over time in production environments.
Complete ML Lifecycle with MLflow - Learn Its Four Components
Explore MLflow's four components to simplify the machine learning lifecycle, from experimentation to production, enhancing reproducibility and accelerating development.
Building a CML Pipeline with Spark and Kafka - YOW! 2018
Explore building a CML pipeline using Apache Spark and Kafka. Learn functional programming techniques for efficient data processing and machine learning workflows.
A Brief History of Data - From Early Computing to Real-Time Streaming
Explore the evolution of data management from early computing to modern real-time systems. Gain insights into technological advancements shaping our understanding and utilization of data.
Supercharging Recommender Systems - Unleashing the Power of Distributed Model Training
Explore distributed model training techniques to enhance recommender systems, boosting performance and scalability for production environments.
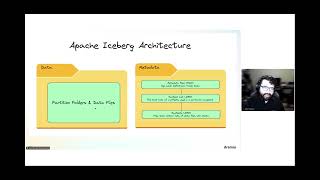
The Who, What, and Why of Data Lake Table Formats
Explore data lake table formats, their creators, purposes, and significance in modern data architecture. Gain insights into optimizing data management and analytics.
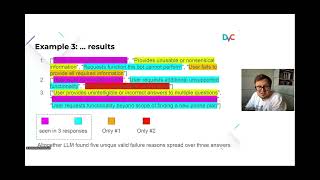
Data Versioning in Generative AI - A Pathway to Cost-effective Machine Learning
Explore data versioning strategies for generative AI, focusing on cost-effective techniques to minimize processing time and API calls while enhancing collaboration and efficient versioning of annotations and embeddings.