Tales at Scale - Analytics at 1000 QPS and Beyond
Explore high-performance analytics techniques for handling 1000+ queries per second, covering Apache Druid, CPU/IO optimization, and scaling strategies for heterogeneous workloads.
Apache Log Visualization with Elasticsearch and ELK Stack
Learn to visualize Apache logs using Elasticsearch and ELK Stack on Ubuntu. Set up Elastic Stack, configure components, and create visualizations for effective log analysis and monitoring.

Changing the Face of Parking: Lessons Learned from SpotHero's Intelligent, Dynamic Rate Board
Optimize parking pricing with real-time data and machine learning. Learn how SpotHero revolutionized the $30B parking industry using IoT sensors and ML models for dynamic, minute-by-minute rate adjustments.
The Risks of Excluding the Disengaged From Your Dataset
Explore the importance of inclusive datasets in machine learning for accurate predictions and reliable insights across various domains.
Challenges and Learnings of Machine Learning at Scale
Explore challenges and learnings of training millions of models efficiently, optimizing costs, and achieving high-performance daily predictions in machine learning.
Pandas 2, Dask or Polars? Quickly Tackling Larger Data on a Single Machine
Explore Pandas 2, Dask, and Polars for efficient large data processing on a single machine. Compare features, performance, and ecosystem compatibility to choose the best tool for your research workflow.
Building an Open Data Lakehouse Using Apache Spark, Apache Iceberg and Dremio
Explore the evolution of big data to data lakehouses, focusing on open architecture development, security, governance, and augmentation using Dremio, Apache Spark, and Apache Iceberg.
Introducing Your Databricks Flight Assistant - Lakehouse AI Copilot
Explore Databricks' Lakehouse Assistant: Chat in English to generate SQL queries, scripts, and code explanations while navigating the Lakehouse with ease.
Generate Test Data Quick, Easy and in Large Volumes with the Databricks Labs Data Generator
Generate terabytes of proper test data quickly and easily using Databricks Labs Data Generator for dev environments across Azure, AWS, and GCP.
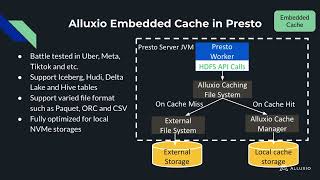
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.
New Features of Apache NiFi - Tips and Techniques
Explore Apache NiFi's latest features, processors, and best practices. Build efficient data flows using cutting-edge techniques, with tips and guides for optimal implementation.
Utilizing Real-Time Transit Data for Travel Optimization
Optimize travel using real-time transit data from NYC's MTA. Learn to process and analyze public data feeds with Apache tools for efficient route planning and decision-making.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
The Free Lunch is Over: Dealing with Unstructured Data in the Era of LLMs
Explore unstructured data processing using ML, LLMs, and Apache tools. Learn to handle audio, images, and text with vector embeddings for natural language analysis in data engineering pipelines.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Declarative Reasoning with Timelines: The Next Step in Event Processing
Explore declarative reasoning with timelines for advanced event processing. Learn stream-native query abstractions and simplified time-based reasoning techniques for modern data processing challenges.
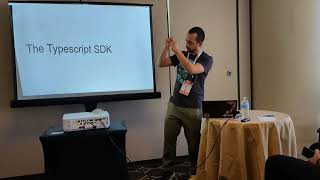
Batch and Stream Analysis with TypeScript Using Apache Beam
Explore batch and stream analysis using Beam's Typescript SDK. Learn API choices, usability, and functionality through demos. Discover how to leverage Typescript for efficient data processing workflows.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.
Spark SQL Shuffle Join Optimization at eBay
Optimize Spark SQL shuffle join performance with advanced techniques like unwrapping join conditions, enhancing shuffle exchange reuse, and pushing down partial aggregations.
Optimizing HDFS Performance: Balanced Utilization of Hardware Accelerators and ARM64 Multi-Implementation - Transparent Encryption
Optimize HDFS Transparent Encryption performance by balancing CPU cores and hardware accelerators. Learn to leverage OpenSSL 3.0 for dynamic resource allocation and improved efficiency in cloud services.