Using Big Data to Create Engagement Agility - Jason McClay G2G3
Explore human-centered design, engagement strategies, and innovative approaches to mandatory training using big data and simulations for improved organizational outcomes.
Big Data and Cyber Security - David Stubley
Explore the intersection of big data and cybersecurity, covering data management, visualization, and key drivers in this informative talk by David Stubley.
Big Data Isn't Big - Dr Jamie Graves
Explore how to effectively leverage big data for business insights, focusing on meaningful analysis, targeted approaches, and overcoming common challenges in data management.
Diving into Delta Lake: How DELETE, UPDATE, and MERGE Work - Part 3
Explore Delta Lake's internals: DELETE, UPDATE, and MERGE operations, transaction log mechanics, and performance optimization techniques for efficient data management.
How to Build a Cloud Data Platform - Part 1: Architecture
Learn to build a unified cloud data platform using Delta Lake, combining data warehouses and lakes for improved reliability, performance, and operations.
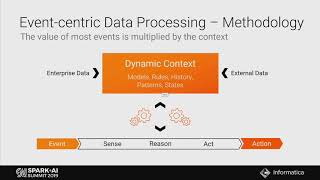
AI-Powered Streaming Analytics for Real-Time Customer Experience
Explore AI-powered streaming analytics for real-time customer engagement. Learn to capture, process, and respond to data from various sources using Spark Structured Streaming for improved customer experiences.
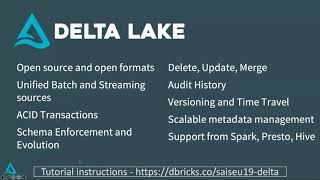
Building Data Intensive Analytic Applications on Top of Delta Lakes
Explore Delta Lake's ACID transactions for Apache Spark, enhancing data reliability and query performance. Learn to address challenges in modern data engineering through hands-on examples and practical applications.
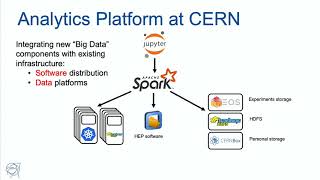
Deep Learning Pipelines for High Energy Physics Using Apache Spark and Distributed Keras
Explore CERN's Apache Spark-based data pipeline for deep learning in High Energy Physics. Learn about distributed training of neural network classifiers using BigDL and Analytics Zoo for improved event filtering at LHC experiments.
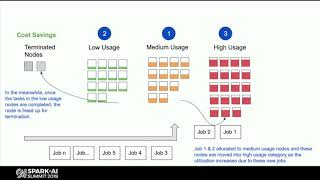
Downscaling Apache Spark Clusters - Challenges and Solutions
Explore techniques to improve downscaling in Spark-on-YARN clusters, addressing container fragmentation and shuffle data challenges for efficient resource management and faster autoscaling.
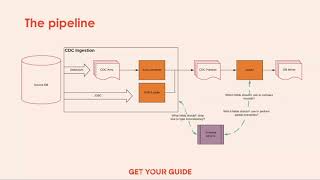
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.
Best Practices for Building and Deploying Data Pipelines in Apache Spark
Learn best practices for building and deploying efficient, reproducible data pipelines in Apache Spark. Discover a toolkit that simplifies pipeline creation for non-engineers and explore deployment strategies.

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.
Apache Spark Core - Practical Optimization Techniques - Partition Shaping and Job Optimization
Explore Apache Spark optimization techniques, including partition shaping, join and aggregate optimizations, and multi-dimensional parallelism to maximize cluster utilization and eliminate data skew.
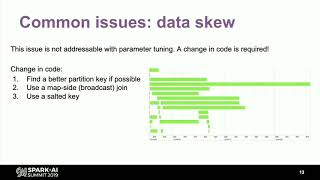
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.
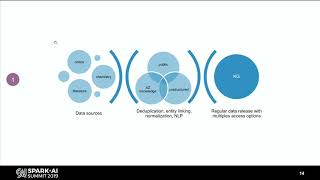
Building a Knowledge Graph with Spark and NLP for Novel Drug Recommendations
Explore drug discovery using knowledge graphs, NLP, and Spark. Learn techniques for efficient data processing, entity recognition, and relationship extraction to enhance pharmaceutical research.
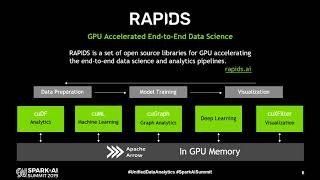
Accelerating Apache Spark with GPUs Using RAPIDS
Explore GPU acceleration for data science with RAPIDS, offering significant performance gains over CPU-only solutions. Learn its functionality, architecture, and integration with Apache Spark for large-scale computation.
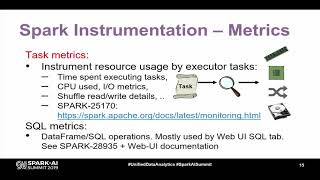
Performance Troubleshooting Using Apache Spark Metrics - Databricks Talk
Explore Apache Spark metrics for performance troubleshooting in distributed data processing. Learn to deploy dashboards, use sparkMeasure, and leverage Spark 3.0 improvements for optimizing workloads.
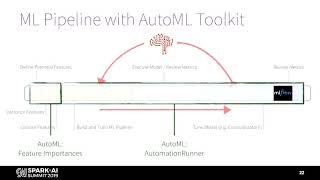
Augmenting Machine Learning with Databricks Labs AutoML Toolkit
Explore how Databricks Labs AutoML Toolkit simplifies and optimizes machine learning processes, from data preparation to model optimization, using financial loan risk data examples.
Different Streaming Methods with Apache Spark and Kafka
Explore real-time analytics using Apache Spark and Kafka. Learn about streaming methods, overcoming technical challenges, and innovative solutions for handling billions of daily events in a scalable, cost-efficient manner.
Simplify and Scale Data Engineering Pipelines with Delta Lake
Learn to build scalable data engineering pipelines using Delta Lake's multi-hop architecture. Discover how to progress from raw data ingestion to machine learning-ready datasets efficiently and effectively.
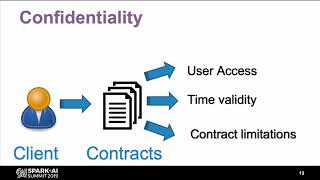
Revolutionizing Legal Industry with Spark, NLP and Azure Databricks - Clifford Chance Case Study
Explore how a top law firm revolutionizes operations using advanced analytics, Spark, NLP, and Azure Databricks to handle millions of legal documents and enhance client relationships.