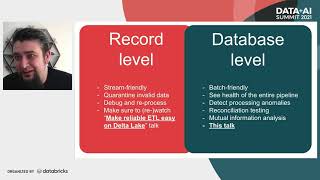
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.
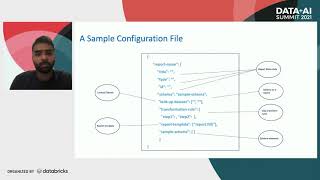
Configuration-Driven Reporting on Large Datasets Using Apache Spark
Configurable enterprise framework for generating and distributing diverse reports from large financial datasets using Apache Spark, with dynamic scheduling and data transformation capabilities.
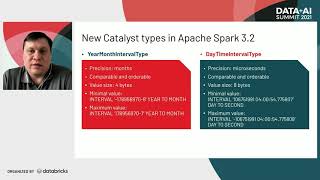
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
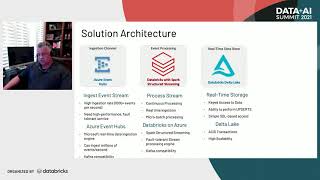
Build Real-Time Applications with Databricks Streaming - Fire Department Use Case
Learn to build real-time applications using Databricks Streaming, focusing on a fire department use case. Explore architecture, data sources, and implementation for live tracking of equipment, personnel, and incidents.
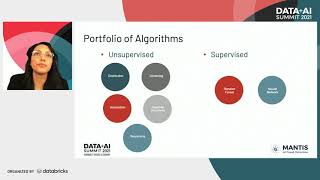
Wizard Driven AI Anomaly Detection with Databricks in Azure
Explore wizard-driven AI anomaly detection for fraud prevention using Databricks. Learn unsupervised and supervised methods, aggregation frameworks, and human-in-the-loop feedback to improve models over time.
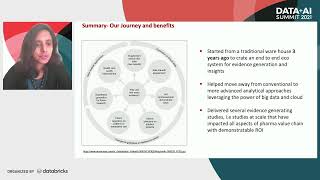
Real-World Evidence and Patient Analytics Using Databricks - A Use Case
Explore real-world health data analytics using Databricks, including insights generation, data security, and advanced use cases. Learn about big data ingestion and cloud-based platform industrialization for life sciences.
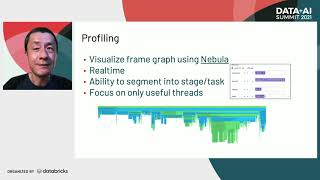
Migrating ETL Workflows to Apache Spark at Scale - Pinterest's Experience
Explore Pinterest's journey migrating ETL workflows to Apache Spark, covering challenges, solutions, and performance improvements. Learn about semantic gaps, thrift objects, and innovative Spark profiling techniques.
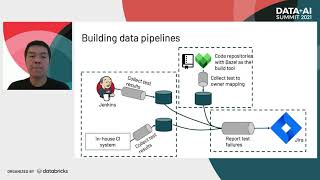
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
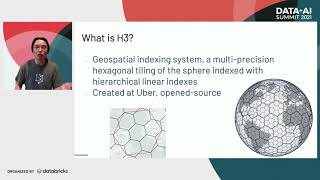
Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
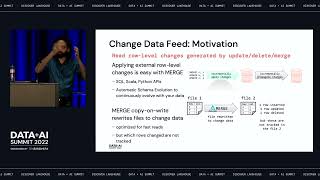
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
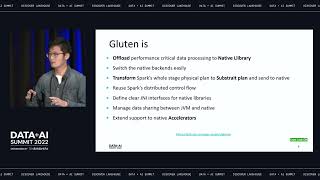
Gazelle-JNI: Offloading Spark SQL to Native Engines for Execution Acceleration
Explore Gazelle-Jni, a middle layer integrating native SQL engines with Spark SQL for accelerated execution through Substrait-transformed physical plan offloading.
Enable Production ML with Databricks Feature Store
Simplify production ML with Databricks Feature Store. Learn to overcome data challenges, enable real-time inference, and streamline ML projects using a unified data lakehouse platform integrated with Apache Spark and MLflow.

Delta Live Tables: Modern Software Engineering for ETL Pipelines
Learn how Delta Live Tables simplifies ETL, enhances data pipeline reliability, and automates tasks. Discover modern software engineering practices for efficient data transformation and improved analytics, data science, and ML outcomes.
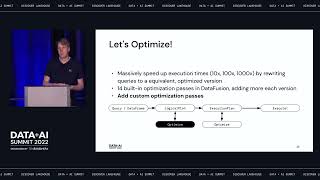
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
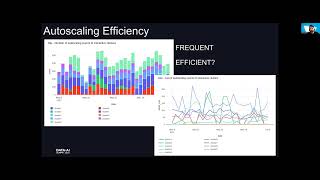
Databricks and Enterprise Observability with Overwatch - Understanding Cost, Utilization, and Workloads
Explore Overwatch's capabilities for monitoring Databricks platform costs, utilization, and workloads. Learn implementation, use cases, and solutions to common observability challenges.
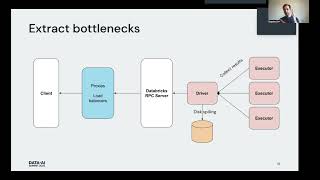
Cloud Fetch: High-Bandwidth Connectivity for BI Tools - Databricks
Explore high-bandwidth connectivity for BI tools using Cloud Fetch, a parallel data extraction mechanism that significantly speeds up query result retrieval from Databricks SQL endpoints.
Recent Parquet Improvements in Apache Spark - Vectorized Complex Types and Column Index Support
Explore recent improvements in Apache Spark's Parquet performance, including vectorized read support for complex types and column index support, leading to significant speed enhancements and efficient data processing.
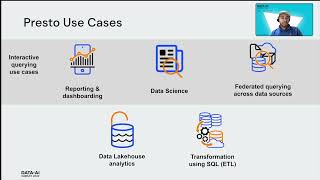
An Introduction to Open Source Presto
Explore Presto, a distributed SQL engine for data lake analytics. Learn its features, benefits, and use cases through an introduction and demo on AWS implementation.
NBA Analytics - Evolution and Impact in Professional Sports
Explore the evolution of sports analytics in the NBA, its impact on teams, and how data drives competitive advantage in professional basketball.
Scaling XGBoost for Thousands of Features with Databricks
Scaling XGBoost for online advertising: Learn to handle thousands of features, optimize model training, and avoid common pitfalls in both Python and Scala implementations on Spark.
Databricks University Alliance: Teaching with Databricks - Community Lightning Talks
Professors share experiences using Databricks in classrooms, covering course content, platform setup, and key observations. Insights from diverse universities on teaching data science and analytics with Databricks.