
Big Data - They Know Everything About You
Explore the clash between privacy and security in the era of big data, examining its impact on personal information, technological advancements, and potential for preventing terrorism.
How Digital Data Collection Methods Impact Scientific Inference - Dr. Rebekah Tromble
Explore how digital data collection methods impact scientific inference, focusing on Twitter data analysis, APIs, and logit regression. Learn to navigate challenges in social and cultural research.
Funnel Analysis with Apache Spark and Druid for Advertising Campaign Effectiveness
Learn to perform funnel analysis at scale using Apache Spark, Druid, and DataSketches. Discover techniques for measuring campaign effectiveness and analyzing user behavior in chronological order for large-scale advertising campaigns.
Degrading Performance - Understanding and Solving Small Files Syndrome
Learn how small files impact data pipeline performance, understand cloud storage and Apache Spark interactions, and discover DeltaLake solutions for improved efficiency in handling massive datasets.
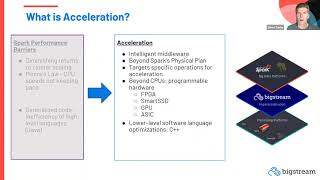
Turbocharging Spark with Samsung SmartSSD Computational Storage Devices
Discover how Samsung SmartSSD® with Xilinx FPGAs accelerates Spark, offering 2x-8x performance gains without code changes. Learn about the technology, benchmarks, and TCO savings.
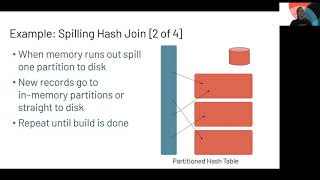
Photon: Accelerating SQL Queries on Databricks Lakehouse Platform
Explore Photon, a C++ component for efficient query execution in Databricks Lakehouse. Learn about its vectorized processing, compatibility with Apache Spark, and performance enhancements for data-driven decision-making.
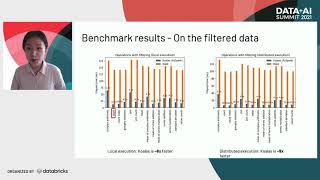
Koalas: Scaling Pandas APIs on Apache Spark - Performance and Comparison with Dask
Explore Koalas: pandas-like APIs for big data on Apache Spark. Compare performance with Dask, learn about recent updates, and understand its scalability for data science tasks.
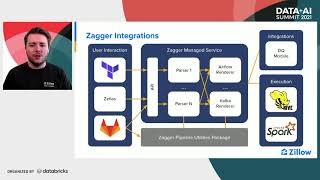
Empowering Developers with Self-Service ETL - Zillow's Approach
Zillow's self-service ETL solutions empower teams to build, maintain, and monitor data pipelines, abstracting complex processes and catering to diverse user needs while leveraging internal services for efficient implementation.
Advancing GPU Analytics with RAPIDS Accelerator for Apache Spark and Alluxio
Learn to accelerate GPU analytics using RAPIDS for Apache Spark and Alluxio, enabling faster data access and processing for AI and analytics workloads across any cloud environment.
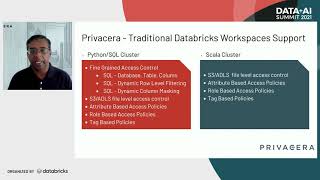
Accelerating Data Science Initiatives with Databricks and Privacera
Explore how Databricks' SQL Analytics and Privacera's governance capabilities integrate to provide rapid, secure data access for advanced analytics while ensuring compliance with privacy regulations.
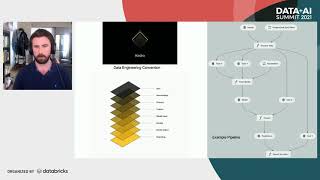
A Collaborative Data Science Development Workflow Using Kedro and MLflow
Explore a collaborative data science workflow using Kedro pipelines, MLflow tracking, and cloud-agnostic GPU containers for efficient model development, training, and production deployment.
What's New with Databricks Machine Learning
Explore Databricks' latest ML innovations, from data preparation to model deployment, in a detailed demo showcasing simplified lifecycle management and enhanced productivity features.
Growing the Delta Ecosystem - Delta-RS for Rust and Python
Explore delta-rs, a Rust library extending Delta Lake beyond Spark. Learn its current capabilities, roadmap, and real-world application in kafka-delta-ingest for high-throughput data transfer.
AI at Scale: Industrializing ML with Databricks
Learn to industrialize ML applications, accelerate model delivery, and optimize data science workflows while maintaining high governance standards using Databricks Lakehouse platform for enterprise-scale AI solutions.
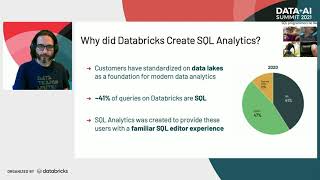
Building Lakehouses on Delta Lake with SQL Analytics
Learn to build lakehouses using Delta Lake, perform SQL analytics, and connect BI tools. Explore data management techniques, governance models, and implementation examples for efficient data processing and analysis.
Make Reliable ETL Easy on Delta Lake
Learn to simplify ETL development on Delta Lake, improving data quality and scaling operations. Discover how Databricks streamlines the ETL lifecycle for efficient data engineering and management.
Delta Lake Streaming - Internals and Query Progress Logs
Explore Delta Lake streaming internals, focusing on structured streaming components, Query Progress Logs, and checkpoint directories for efficient real-time data pipeline management.
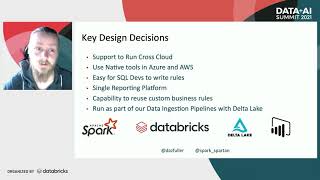
Building Data Quality Pipelines with Apache Spark and Delta Lake
Learn to build robust data quality pipelines using Apache Spark and Delta Lake. Explore rule templates, reporting models, and PowerBI integration for effective data remediation and self-healing in enterprise environments.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
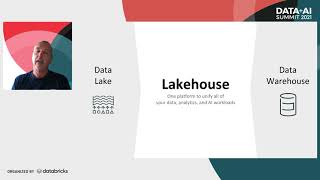
Creating a Lakehouse on AWS
Learn to build a Lakehouse on AWS, combining data lake affordability with data warehouse performance. Discover integration with AWS services and real-world examples of high-performance, cost-effective analytics solutions.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.