Example Memorization in Learning: Batch and Streaming - Differential Privacy for ML
Explore example memorization in machine learning, covering batch and streaming scenarios, space requirements, and implications for natural models and future research directions.
Future of AI and ML in Software Testing
Explore AI's impact on software testing, including challenges, self-healing scripts, and future contributions. Learn to improve processes and implement risk-based methods using AI insights.
Stream Processing at the Edge with Apache Kafka
Explore edge computing with Apache Kafka for improved performance and resiliency. Learn use cases, cloud integration, and Kubernetes management using GitOps. Includes IoT data processing demo.
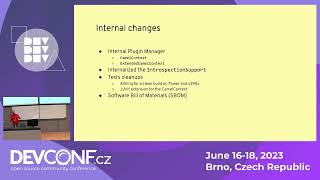
Apache Camel 4: What to Expect
Explore Apache Camel 4's major features, roadmap, and potential upgrade impacts. Learn about performance improvements, deprecated components, and migration strategies from earlier versions.
Managing the Camel Development Lifecycle Within VS Code
Explore Apache Camel development in VS Code: initialize routes, run integrations, edit graphically, debug efficiently, and deploy seamlessly using the Extension Pack for Apache Camel.
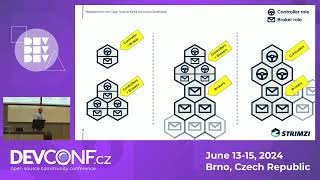
Apache Kafka Without ZooKeeper - Transitioning to KRaft
Explore Apache Kafka's transition from ZooKeeper to KRaft, understanding advantages, challenges, and implications for Kubernetes deployments and the Strimzi project.
Feeding ML Models with Real-Time Database Data
Explore real-time data ingestion from databases to ML models using Change Data Capture. Learn about Debezium, challenges, and future improvements with a live TensorFlow demo.
Transitioning from Debezium ElasticSearch to Postgres for Streamlined Resilience
Explore backend optimization by transitioning from Debezium ElasticSearch to Postgres. Learn about foreign data wrapper, logical replication, and database consolidation for enhanced resilience and simplified infrastructure.
Building a Distributed Search Engine for Logs
Explore efficient architecture for building a distributed search engine to handle terabytes of logs, inspired by Snowflake's compute-storage separation approach.
Securing Apache Spark Big Data Operations: Threats, Best Practices, and Pragmatic Steps
Explore Apache Spark security best practices, threat modeling, and practical steps to safeguard big data operations in various environments.
A Holistic Approach to Securing Spark-Based Data Engineering
Learn to secure Apache Spark-based data engineering applications. Explore security best practices, identify threats, prioritize requirements, and implement practical steps for Kubernetes and object storage environments.
A Data Lake on Your Cloud with Spark, Kubernetes and OpenStack
Explore data lake architecture using Spark, Kubernetes, and OpenStack for flexible, scalable, and cost-effective large-scale data processing on private cloud platforms.
Amr Awadallah's Journey: Data, Cloud Computing, AI, and Entrepreneurship
Explore Amr Awadallah's tech journey from Yahoo to Vectara, covering data processing, cloud computing, AI, and entrepreneurship. Gain insights on open-source models, GenAI adoption, and startup success factors.

A Fun and Absurd Introduction to Vector Databases
Explore vector databases for AI applications and natural language search. Learn to transform data into vectors, query effectively, and discover diverse use cases through engaging demonstrations.
Functional Programming and Scala for Machine Learning - YOW! 2015
Explore how functional programming and Scala can revolutionize machine learning, offering strongly-typed solutions for efficient algorithm implementation and scalable data processing.
Maintaining the Databricks Terraform Provider - A Journey of Growth and Learning
Insights into Databricks Terraform provider's evolution, development challenges, and user anti-patterns from a maintainer's perspective, highlighting growth and lessons learned.
Building GenAI-Powered Solutions Using Mosaic ML, DBRX LLM and LLMOps
Explore LLMs and Generative AI's potential to revolutionize industries. Learn about Databricks Mosaic ML Training Platform, DBRX models, and LLMOps for streamlined AI adoption and innovation in healthcare and insurance.
Texas Rangers' Championship Success with a Data Intelligence Platform
Explore how the Texas Rangers leveraged Databricks' Data Intelligence Platform and GenAI for strategic insights, predictive analytics, and World Series victory.
Enabling Trusted AI with Databricks and Informatica - KPMG Case Study
Discover how KPMG leverages Databricks and Informatica to build trusted AI models, addressing data quality, governance, and ethical challenges for data-driven decision-making and business success.
Streaming Data Pipelines From Supernovas to LLMs
Hands-on tutorial for building real-time data pipelines using Databricks, from ingesting NASA supernova data to implementing LLMs with RAG. Covers ETL, stream processing, and natural language analytics.
AT&T's Journey Towards a Serverless Data Intelligence Platform
Explore AT&T's evolution on Databricks Platform, scaling data projects with automated pipelining, serverless SQL warehouses, and AI/ML use cases while meeting security and regulatory requirements.