Beyond Standard Deep Learning Models for Time Series and Sequences
Explore advanced techniques for temporal data analysis, including confident predictions and adaptive computational time models for improved sequence-to-sequence processing.
Attention Is All You Need - A Landmark Paper in AI
Explore the groundbreaking "Attention Is All You Need" paper, its impact on modern AI, and the potential of transformer architecture in various applications beyond machine translation.
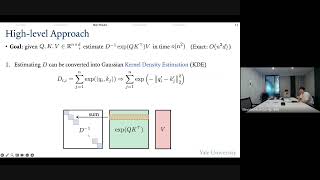
Accelerating Transformers via Kernel Density Estimation - Google TechTalk
Explore efficient Transformer acceleration using kernel density estimation. Learn innovative techniques for handling long sequences and improving performance in deep learning models.
LLMs and Transformers Demystified: Introduction to AI Engineering - Lecture 1
Demystify transformers and LLMs through intuitive weather analogies. Explore the architecture's impact on AI, from 'Attention is All You Need' to modern applications like ChatGPT.
Attention to Quantum Complexity
Explore quantum complexity through advanced concepts and cutting-edge research, presented by Cornell University expert Eun-Ah Kim at a prestigious international conference.

Informer Architecture Explained - Complete Guide
Comprehensive exploration of Informer encoder architecture, detailing its components and implementation for advanced time series forecasting and sequence modeling tasks.

Informer: Training and Inference
Explore time series prediction using Informer, a transformer-based model. Learn to train and make predictions through hands-on coding, enhancing your skills in advanced forecasting techniques.
MIT 6.S191 - Recurrent Neural Networks
Comprehensive lecture on Recurrent Neural Networks, covering theory, implementation, and applications. Explores sequence modeling, LSTM, attention mechanisms, and practical examples in deep learning.

Informer: Complete Code from Scratch - Time Series Transformer Analysis
Line-by-line exploration of the time series transformer, focusing on implementation details and code structure for deep learning enthusiasts and practitioners.
Vision Transformers (ViTs) - A Beginner's Guide to Image Processing with Transformers
Dive into Vision Transformers (ViTs), exploring core concepts like linear projection, multihead attention layers, and patch embedding in a beginner-friendly, comprehensive walkthrough.
Vision Transformer - Lecture 16
Dive into Vision Transformers architecture and implementation, exploring their role in computer vision tasks through expert insights and practical applications in machine learning.
Vision Transformer for Efficient Machine Learning - Lecture 16
Dive into Vision Transformer architecture and implementation with MIT Prof. Song Han, exploring key concepts and practical applications in modern computer vision and machine learning.
Long-Context Large Language Models - Lecture 15
Dive into advanced techniques for handling extended context in Large Language Models, exploring efficiency strategies and implementation methods for enhanced AI processing capabilities.

Deep Dive into ChatGPT: Architecture and Comparison with Bard and LLaMa
Explore ChatGPT's architecture, implementation, and evolution. Compare with Bard and LLaMa. Learn to build tinyGPT. Gain insights into transformers, attention mechanisms, and the GPT family of models.
Transformer and Large Language Models - Part I - Lecture 12
Explore Transformer architecture and Large Language Models in this comprehensive MIT lecture, covering key concepts and recent advancements in AI.
Transformer and Large Language Models - Part I - Lecture 12
Explore Transformer architecture and Large Language Models in this comprehensive MIT lecture, covering key concepts and recent advancements in AI.
Transformer and Large Language Models - Part II - Lecture 13
Explore advanced concepts of Transformers and Large Language Models in this in-depth lecture from MIT's EfficientML course.
Transformer and Large Language Models - Part II - Lecture 13
Explore advanced concepts of Transformers and Large Language Models, focusing on efficiency and optimization techniques in AI and machine learning.
Vision Transformer - Lecture 14
Explore Vision Transformers in deep learning, covering architecture, training, and applications. Gain insights into this powerful model for computer vision tasks.
SparQ Attention: Bandwidth-Efficient LLM Inference
Explore SparQ Attention, a technique for increasing LLM inference throughput by reducing memory bandwidth in attention blocks through selective history fetching, applicable to off-the-shelf models without retraining.
Toward Length Extrapolatable Transformers
Explore innovative techniques for enhancing transformer models' ability to handle longer sequences, improving their performance and scalability in natural language processing tasks.