
GPT-2 and Transformers
Explore text-based AI models, focusing on GPT-2 and Transformers. Learn about their architecture, capabilities, and potential applications in natural language processing.

Recurrent Neural Networks, Transformers, and Attention
Explore recurrent neural networks, transformers, and attention mechanisms in deep learning. Learn design principles, applications, and advanced concepts like LSTM and backpropagation through time.

Pytorch Seq2Seq with Attention for Machine Translation
Build a Seq2Seq model with Attention in PyTorch for German-to-English machine translation, applying it to the Multi30k dataset and learning from scratch.
On Localization in Language Models
Explore the role of individual components in language models, their characterization, and how analyzing internal structures can elucidate behavior in memorization, gender bias, and factual recall.
Flash Attention 2.0 with Tri Dao - Discord Server Talks
Explore Flash Attention 2.0 with author Tri Dao, covering its motivation, improvements, and future directions. Gain insights into memory bottlenecks and IO awareness in attention mechanisms for long sequences.
Transformer Encoder in 100 Lines of Code
Learn to implement a Transformer Encoder from scratch in Python. Explore key concepts like attention mechanisms, layer normalization, and feed-forward networks through hands-on coding.
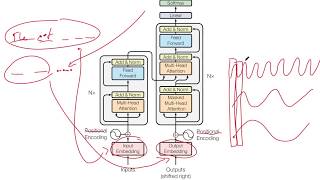
Attention Is All You Need
Explore the groundbreaking Transformer architecture, revolutionizing sequence transduction with attention mechanisms. Learn its superior performance in machine translation and generalization to other NLP tasks.
Recurrent Neural Networks and Models of Computation - Edward Grefenstette, DeepMind
Exploring recurrent neural networks and memory-enhanced architectures, analyzing their computational capabilities and efficiency in relation to traditional models of computation.

Parameter Sharing - Recurrent and Convolutional Nets
Explore parameter sharing in recurrent and convolutional neural networks, covering hypernetworks, RNNs, LSTMs, attention mechanisms, and ConvNets, with insights on architecture, training, and biological inspiration.
Attention and the Transformer
Explore self-attention, key-value stores, and transformer architecture in deep learning. Learn to implement attention mechanisms and understand encoder-decoder paradigms for advanced neural network design.

CNN Applications, RNN, and Attention
Explore CNN applications in digit recognition, object detection, and semantic segmentation. Dive into RNNs, addressing their challenges with attention mechanisms, GRUs, LSTMs, and Seq2Seq models.
Memory Augmented Networks
Learn about memory augmented networks, including architecture, attention mechanisms, and applications in machine translation, with a focus on improving generalization in deep learning models.

CS480-680 Lecture 19 - Attention and Transformer Networks
Explore attention mechanisms, transformer networks, and their applications in machine learning, including multihead attention and normalization techniques.
MAST - A Memory-Augmented Self-Supervised Tracker
Learn about MAST, a novel memory-augmented self-supervised tracker that enhances video tracking and segmentation using attention mechanisms and innovative algorithms.
Graph Representation Learning and Its Applications to Biomedicine
Graph representation learning techniques for biomedical applications, focusing on SubGNN for disentangled subgraph embeddings and their use in predicting disease treatments and safe drug combinations.
Question Answering for Language and Vision
Explore advanced techniques in question answering for language and vision, including joint models, multitask learning, and neural networks with Richard Socher from MetaMind.
Driving with Attention
Explore innovative sensor fusion techniques for autonomous driving, focusing on TransFuser and NEAT models that leverage attention mechanisms to improve perception and decision-making in complex traffic scenarios.
Fast Attention Requires Bounded Entries
Explore the relationship between fast attention mechanisms and bounded entries in machine learning, with insights from Josh Alman's research on sketching and algorithm design.
AI News: Open Source Advancements and Recent Developments
Explore latest AI advancements: new models, papers, and tools. Learn about HyperAttention, MemGPT, Self-RAG, PaLI-3, Fuyu-8B, MistralLite, and more. Stay updated on AI developments in various domains.

Coding a ChatGPT-Like Transformer From Scratch in PyTorch
Step-by-step tutorial on building a ChatGPT-like Transformer from scratch in PyTorch, covering data preparation, position encoding, attention mechanisms, and model training for natural language processing.

Transformer Models: Understanding Their Architecture and Functionality - Part 3
Demystifying Transformer models with visuals and examples, covering key concepts like attention mechanism, tokenization, embeddings, and fine-tuning for various NLP tasks.