
Autoregressive Long-Context Music Generation with Perceiver AR
Explore autoregressive long-context music generation using Perceiver AR, presented by DeepMind's Cătălina Cangea. Gain insights into cutting-edge AI techniques for creating music.
From RNNs to Transformers - A Journey Through Language Modeling
Explore the evolution of language models from RNNs to Transformers, understanding attention mechanisms and investigating the minimal requirements for coherent language generation in AI systems.
Revealing the Unseen: Visualizing Attention in Transformer Models
Dive into the visualization techniques of attention mechanisms in Transformer models, understanding their inner workings and practical applications through expert insights.
Making LLMs Fully Utilize Context - A Data-Driven Approach
Discover how to enhance LLM context utilization through Microsoft's data-driven approach, exploring information-intensive training methods and practical solutions for improved context awareness and reasoning capabilities.
LongRoPE and Theta Scaling for Extended Context Length in LLMs - Part 2
Delve into advanced techniques for extending LLM context lengths through LongRoPE and Theta Scaling, exploring methods to enhance model performance from 8K to 4M tokens.
Understanding Retrieval Heads in Large Language Models - From Discovery to Applications
Discover groundbreaking research on retrieval heads in transformer architecture, exploring their impact on RAG systems, long-context processing, and chain-of-thought reasoning for enhanced AI capabilities.
RecurrentGemma: Moving Past Transformers with Griffin Architecture for Long Context Length
Explore Google's RecurrentGemma-2B architecture, featuring Griffin's innovative approach to language modeling that surpasses traditional transformers with enhanced efficiency and long-context processing capabilities.
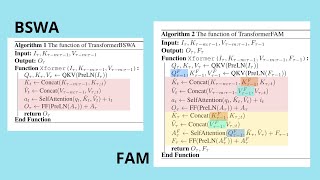
TransformerFAM and BSWA: Understanding Feedback Attention Memory and Block Sliding Window Attention
Dive into Google's revolutionary TransformerFAM architecture, exploring how feedback attention mechanisms and working memory enhance AI's ability to process indefinite sequence lengths with improved efficiency and context awareness.
INFINI Attention: Efficient Infinite Context Transformers with 1 Million Token Context Length
Explore Google's Infini-attention transformer mechanism, featuring compressive memory integration for handling million-token sequences and efficient long-term information processing.
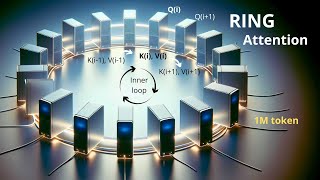
Ring Attention and Blockwise Transformers for Extended Context Length in Language Models
Dive into the technical mechanics of Ring Attention, exploring how it achieves million-token context lengths in large language models through blockwise parallel transformers and efficient implementation.
StreamingLLM: Enabling Infinite Sequence Length in Large Language Models
Dive into StreamingLLM's framework for extending LLM attention windows to handle infinite sequences, featuring practical implementation insights and code analysis.
LongNet: Understanding Transformer Scaling to 1 Billion Tokens - A Technical Overview
Dive into Microsoft's LongNet transformer architecture, exploring how dilated attention mechanisms enable processing of billion-token sequences and advance the field towards artificial general intelligence.
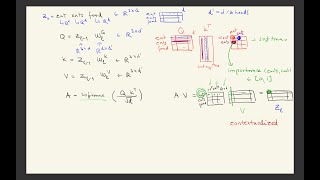
Pairwise Feature Importance and Effective Attention in Self-Attention Networks
Dive into advanced concepts of attention mechanisms, exploring effective attention computation, norm-based analysis, and practical applications in neural networks.
Phase Transitions in Dot-Product Attention Layer Learning - New AI Discovery
Explore groundbreaking research on phase transitions in LLM attention mechanisms, revealing key insights into semantic learning and potential breakthroughs in AI model efficiency.
Deep Learning: Transformers and Encoder-Decoder Architecture - Lecture 10
Dive into transformer architectures, exploring encoder-decoder mechanisms and positional embeddings for advanced deep learning applications.
Attention Mechanism and Self-Attention in Deep Learning - Lecture 9
Dive into attention mechanisms and self-attention concepts in deep learning, exploring their revolutionary impact on NLP and discovering practical applications in sequence models.
Transformer Types and Practical Considerations
Explore different transformer architectures and key implementation factors for building effective natural language processing models and applications.
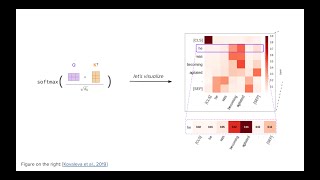
Attention and Transformer Encoder Architecture
Master the inner workings of Transformer encoders and attention mechanisms in deep learning, exploring their architecture, self-attention calculations, and practical applications in modern AI.
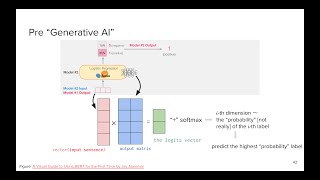
Transformer Decoder - Pretraining and Finetuning
Master transformer decoder architecture fundamentals, exploring pretraining methods and effective finetuning techniques for advanced natural language processing applications.
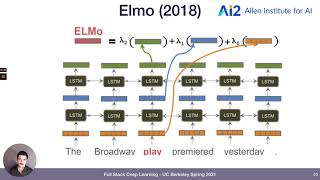
Transfer Learning and Transformers - Full Stack Deep Learning - Spring 2021
Explore transfer learning's evolution from computer vision to NLP, diving into embeddings, language models, and the revolutionary Transformer architecture. Gain insights into various models and their applications.
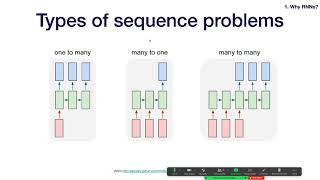
Recurrent Neural Networks - Full Stack Deep Learning - Spring 2021
Explore Recurrent Neural Networks: architecture, challenges, solutions, and applications. Dive into LSTMs, bidirectionality, attention mechanisms, CTC loss, and non-recurrent sequence models like WaveNet.