Navigating Forgetfulness and Intelligence in AI
Explore AI's memory dynamics, learning challenges, and the interplay between forgetfulness and intelligence. Gain insights into how AI systems remember, forget, and process information over time.
Fast Multipole Attention: A Divide-and-Conquer Attention Mechanism for Long Sequences
Innovative divide-and-conquer strategy for efficient attention in long sequences, reducing complexity while maintaining global receptive field. Potential to enhance large language models with extended context processing.

Scalable MatMul-free Language Modeling - Paper Explained
Explore innovative MatMul-free language modeling techniques using quantization and recurrence, achieving comparable performance to traditional models while significantly reducing computational costs and memory usage.
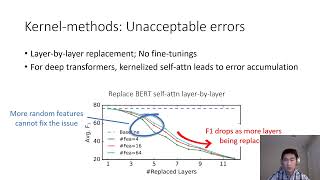
The NLP Task Effectiveness of Long-Range Transformers
Explore the effectiveness of long-range Transformer variants on NLP tasks, comparing their performance and analyzing attention behaviors to uncover strengths and limitations.
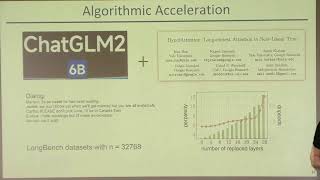
Long-context Attention in Near-Linear Time
Explores HyperAttention, an innovative approach to tackle computational challenges in long-context LLMs, offering significant speed improvements while maintaining performance across various datasets.
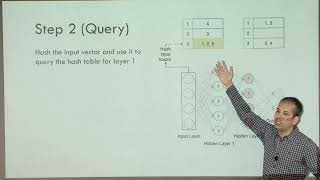
Sub-Linear Algorithms Meets Large Language Models
Explore emerging ideas and successful trends in sub-linear algorithms for future LLMs, addressing compute, memory, and energy challenges in training and inference.
Hello Deep Learning
Explore deep learning from scratch, building an OCR solution for handwritten letters. Learn the fundamentals of machine learning and gain insights into the world of AI and neural networks.
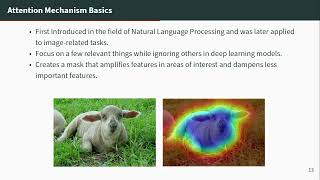
Chan Vese Attention U-Net - An Attention Mechanism for Robust Segmentation
Explore an innovative attention mechanism for robust image segmentation using Chan Vese Attention U-Net, enhancing segmentation accuracy and efficiency.
Raising the Ki of a SciML Model - Enhancing GOKU-nets for Scientific Machine Learning
Explore advanced SciML techniques with GOKU-UI, enhancing Latent ODEs through attention mechanisms and multiple shooting. Learn to improve model performance and data efficiency for complex system modeling.

Transformer Models and BERT Model: Overview
Explore Transformer architecture and BERT model, understanding key components and applications in text classification, question answering, and natural language inference.
Creating Image Captioning Models: Overview and Components
Learn to build deep learning image captioning models, exploring encoder-decoder architecture, training techniques, and evaluation methods for accurate visual descriptions.
Cost-Efficient Large Language Model Serving for Multi-turn Conversations with CachedAttention
Innovative attention mechanism for efficient LLM serving in multi-turn conversations, reducing computation costs and improving performance through hierarchical KV caching and optimized cache management.

Informer Encoder Architecture Explained
Explore the Informer Encoder architecture, its key components, and implementation details for advanced time series forecasting and sequence modeling tasks.
Transformers Are RNNs- Fast Autoregressive Transformers With Linear Attention
Explore a novel approach to transformers using linear attention, reducing computational complexity and revealing connections to RNNs. Gain insights into faster, more efficient deep learning models for long sequences.
BERTology Meets Biology - Interpreting Attention in Protein Language Models
Explores how BERT models trained on protein sequences learn biological properties, revealing insights into protein structure, binding sites, and biophysical characteristics through attention mechanism analysis.
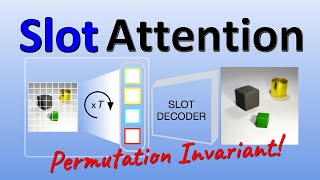
Object-Centric Learning with Slot Attention
Explanation of a novel deep learning module for object-centric visual scene understanding. Covers architecture, algorithm, experiments, and implications of Slot Attention for improved object recognition and reasoning.
Recurrent Neural Networks and Transformers
Comprehensive exploration of recurrent neural networks, LSTMs, and attention mechanisms in deep learning, covering theory, implementation, and applications for sequence modeling tasks.
Attention with Linear Biases Explained
Explore attention mechanisms with linear biases in transformer models, enabling efficient extrapolation to longer sequences without explicit positional embeddings.
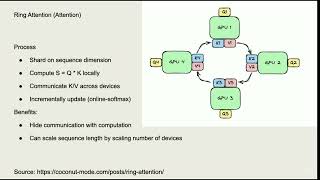
Unraveling Long Context: Existing Methods, Challenges, and Future Directions
Explore the complexities of scaling transformer models for longer context, examining current methodologies, implementation hurdles, and emerging solutions in AI development.
Understanding I-JEPA: A Non-Generative Approach to Self-Supervised Learning from Images
Dive into Meta AI's I-JEPA framework for self-supervised image learning, exploring its architecture, methodology, and advantages over traditional approaches in computer vision and neural networks.
A User Guide to Transformers
Explore practical applications of transformers with minimal examples for various scenarios, enhancing your understanding of this innovative data analysis tool.