Different Streaming Methods with Apache Spark and Kafka
Explore real-time analytics using Apache Spark and Kafka. Learn about streaming methods, overcoming technical challenges, and innovative solutions for handling billions of daily events in a scalable, cost-efficient manner.
Simplify and Scale Data Engineering Pipelines with Delta Lake
Learn to build scalable data engineering pipelines using Delta Lake's multi-hop architecture. Discover how to progress from raw data ingestion to machine learning-ready datasets efficiently and effectively.
Revolutionizing Legal Industry with Spark, NLP and Azure Databricks - Clifford Chance Case Study
Explore how a top law firm revolutionizes operations using advanced analytics, Spark, NLP, and Azure Databricks to handle millions of legal documents and enhance client relationships.
Introduction to Databricks Lakehouse Platform Architecture and Security
Explore Databricks Lakehouse Platform's architecture, focusing on data reliability, Delta Lake features, and Photon's performance enhancements for efficient data management and analytics.
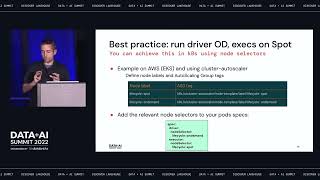
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.
Improving Apache Spark Application Processing Time - Configuration and Optimization Techniques
Optimize Spark streaming app performance through configurations, code improvements, and custom data source implementation for processing 700 MB/s of compressed data with strict KPIs.
Implementing End-to-End Demand Forecasting with Databricks and MLflow
Discover how to implement a scalable demand forecasting solution using Databricks and MLflow, improving retail efficiency and reducing food waste through accurate production and delivery planning.
Apache Spark on Kubernetes - Lessons Learned from Launching Millions of Spark Executors
Lessons learned from running massive Spark workloads on Kubernetes at Apple, covering orchestration, resource management, monitoring, and optimization for scalability and performance.
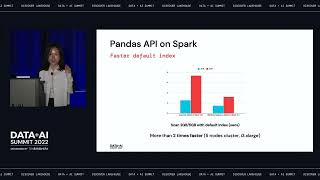
PySpark in Apache Spark 3.3 and Beyond
Explore PySpark's evolution in Apache Spark 3.3, including improved Pandas API, enhanced productivity features, and future developments. Learn about new functionalities, usability improvements, and performance enhancements.
Migrating Pinterest Apache Spark Clusters from HDFS to S3
Explore Pinterest's migration of Apache Spark clusters from HDFS to S3, addressing technical challenges, optimizing performance, and achieving a smooth transition process.
Deploying Apache Spark Jobs on Kubernetes with Helm and Spark Operator
Learn to deploy Scala Spark jobs on Kubernetes using Helm and Spark Operator. Live coding demo shows scalable, flexible deployments with minimal custom configurations for stress-free implementation.
User Defined Aggregation in Apache Spark - From Challenges to Improvements
Explore Apache Spark's User Defined Aggregate Functions (UDAFs), their evolution, and improvements in Spark 3.0. Learn to create custom aggregations, enhance performance, and contribute to the Spark community.
Best Practices for Building Robust Data Platforms with Apache Spark and Delta
Learn best practices for building robust data platforms using Apache Spark and Delta. Gain insights on optimizing performance, scaling, security, and cost-effectiveness in big data architectures from real-world experiences.
Patterns and Operational Insights for Large-Scale Delta Lake Workloads
Explore effective Delta Lake patterns, optimization techniques, and operational insights for managing large-scale data workloads on Databricks, including streaming ETL, data enrichment, and analytics.
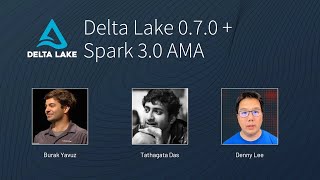
Delta Lake 0.7.0 and Spark 3.0 - Ask Me Anything Session
Illuminating AMA session with Apache Spark and Delta Lake experts. Explore Spark 3.0 and Delta Lake's latest features, use cases, and development insights. Perfect for data engineers seeking cutting-edge knowledge.
Koalas - Scaling Pandas API on Apache Spark
Learn to scale pandas operations to big data using Koalas, an open-source project implementing the pandas API on Apache Spark. Transition seamlessly from single-machine to distributed environments for large-scale data science.
Healthcare Claim Reimbursement Using Apache Spark - Optum's System Transformation
Optimizing healthcare claim processing with Apache Spark: Improved performance, reduced costs, and enhanced capabilities for hospitals' revenue recovery through efficient data processing and analysis.
Cloud-Native Apache Spark Scheduling with YuniKorn on Kubernetes
Explore cloud-native Apache Spark scheduling on Kubernetes using YuniKorn. Learn about efficient resource management, quota handling, and auto-scaling for large-scale Spark jobs in cloud environments.

Bringing Satellite and Drone Imagery into Data Science Workflows
Explore satellite and drone imagery analysis in data science workflows using RasterFrames, a Spark SQL extension with Python API for processing spatial image data and integrating with ML frameworks.
Scaling Data and ML with Apache Spark and Feast - Feature Engineering for Production
Explore scaling data and ML with Apache Spark and Feast, focusing on feature engineering challenges and solutions for big data-driven machine learning in production environments.
Accelerating Apache Spark Shuffle for Data Analytics on Cloud with Remote Persistent Memory Pools
Innovative solution for accelerating Apache Spark shuffle operations using remote persistent memory pools, improving performance, scalability, and reliability in cloud-based big data analytics.