Composable Data Processing with Apache Spark - Scaling Development and Error Handling
Learn about SIP, an extensible plugin framework for Apache Spark that enhances data processing efficiency, error handling, and scalability in Adobe's Experience Platform.
Re-Imagining Apache Spark Development - Tools for Productivity and Standardization
Exploring next-gen tools for Apache Spark development, focusing on productivity, code standardization, metadata, lineage, and CI/CD agility to overcome limitations of traditional ETL tools.
Introducing Apache Spark 3.0 - A Decade of Progress and Future Outlook
Apache Spark 3.0: Reflecting on a decade of progress and unveiling new features to enhance data processing accessibility, speed, and compatibility across various sources and environments.
Slowly Changing Dimensions Type 2 in Data Lakes - Tech Chat
Explore Slowly Changing Dimensions Type 2 in data lakes using Delta Lake, focusing on market segmentation for a climbing eCommerce site. Learn to track historical and current data effectively.
State of the Industry - Machine Learning Platforms and MLOps
Explore the state of MLOps and ML platforms with industry leaders, focusing on challenges, common components, and Databricks' approach to unified data analytics and machine learning.
Predictive Maintenance on IoT Data for Early Fault Detection with Delta Lake
Explore predictive maintenance using IoT data and Delta Lake for early fault detection. Learn about Industry 4.0 applications, data analytics, and machine learning techniques for improved efficiency and cost savings.
How to Build a Cloud Data Platform - Machine Learning and Business Intelligence - Part 4
Learn to leverage Delta Lake for dashboards and advanced analytics, enabling downstream teams with machine learning and business intelligence capabilities on a unified data platform.
Diving into Delta Lake: How DELETE, UPDATE, and MERGE Work - Part 3
Explore Delta Lake's internals: DELETE, UPDATE, and MERGE operations, transaction log mechanics, and performance optimization techniques for efficient data management.
How to Build a Cloud Data Platform - Part 1: Architecture
Learn to build a unified cloud data platform using Delta Lake, combining data warehouses and lakes for improved reliability, performance, and operations.
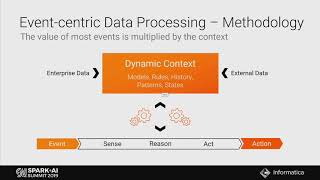
AI-Powered Streaming Analytics for Real-Time Customer Experience
Explore AI-powered streaming analytics for real-time customer engagement. Learn to capture, process, and respond to data from various sources using Spark Structured Streaming for improved customer experiences.
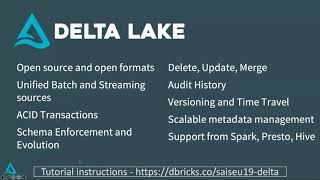
Building Data Intensive Analytic Applications on Top of Delta Lakes
Explore Delta Lake's ACID transactions for Apache Spark, enhancing data reliability and query performance. Learn to address challenges in modern data engineering through hands-on examples and practical applications.
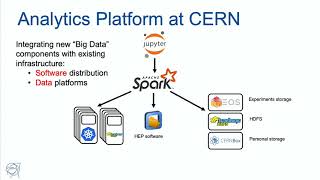
Deep Learning Pipelines for High Energy Physics Using Apache Spark and Distributed Keras
Explore CERN's Apache Spark-based data pipeline for deep learning in High Energy Physics. Learn about distributed training of neural network classifiers using BigDL and Analytics Zoo for improved event filtering at LHC experiments.
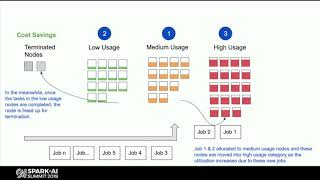
Downscaling Apache Spark Clusters - Challenges and Solutions
Explore techniques to improve downscaling in Spark-on-YARN clusters, addressing container fragmentation and shuffle data challenges for efficient resource management and faster autoscaling.
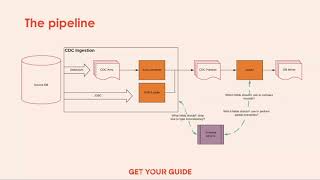
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.
Best Practices for Building and Deploying Data Pipelines in Apache Spark
Learn best practices for building and deploying efficient, reproducible data pipelines in Apache Spark. Discover a toolkit that simplifies pipeline creation for non-engineers and explore deployment strategies.

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.
Apache Spark Core - Practical Optimization Techniques - Partition Shaping and Job Optimization
Explore Apache Spark optimization techniques, including partition shaping, join and aggregate optimizations, and multi-dimensional parallelism to maximize cluster utilization and eliminate data skew.
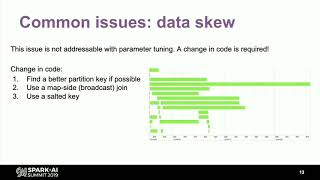
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.
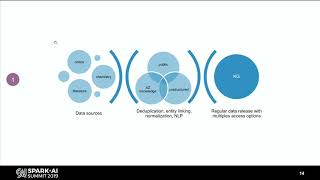
Building a Knowledge Graph with Spark and NLP for Novel Drug Recommendations
Explore drug discovery using knowledge graphs, NLP, and Spark. Learn techniques for efficient data processing, entity recognition, and relationship extraction to enhance pharmaceutical research.
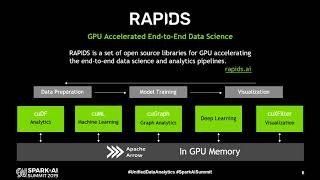
Accelerating Apache Spark with GPUs Using RAPIDS
Explore GPU acceleration for data science with RAPIDS, offering significant performance gains over CPU-only solutions. Learn its functionality, architecture, and integration with Apache Spark for large-scale computation.
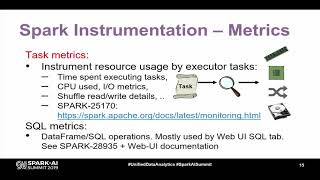
Performance Troubleshooting Using Apache Spark Metrics - Databricks Talk
Explore Apache Spark metrics for performance troubleshooting in distributed data processing. Learn to deploy dashboards, use sparkMeasure, and leverage Spark 3.0 improvements for optimizing workloads.