Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
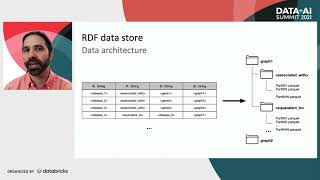
Drug and Vaccine Discovery Using Knowledge Graphs and Apache Spark
Explore how GSK uses knowledge graphs and Apache Spark to build a massive medical database, enabling advanced drug and vaccine discovery through innovative data querying and machine learning techniques.
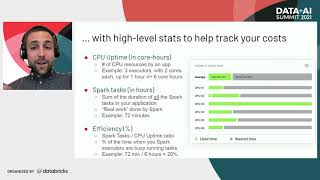
Delight - Improved Apache Spark UI for Performance Troubleshooting
Explore Delight, a free monitoring dashboard for Apache Spark. Learn to troubleshoot and optimize data engineering pipelines using system metrics and Spark information for improved performance and cost-effectiveness.
Deep Dive into New Features of Apache Spark 3.1
Explore Apache Spark 3.1's new features: ANSI SQL compliance, streaming enhancements, Python improvements, and performance optimizations for faster, easier, and smarter data processing.
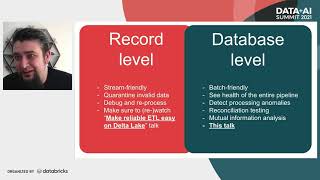
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.
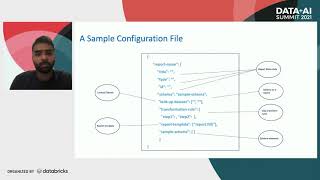
Configuration-Driven Reporting on Large Datasets Using Apache Spark
Configurable enterprise framework for generating and distributing diverse reports from large financial datasets using Apache Spark, with dynamic scheduling and data transformation capabilities.
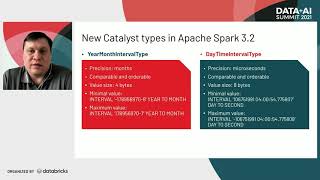
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
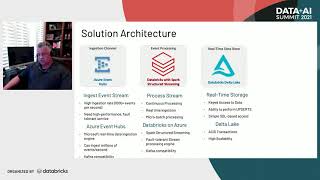
Build Real-Time Applications with Databricks Streaming - Fire Department Use Case
Learn to build real-time applications using Databricks Streaming, focusing on a fire department use case. Explore architecture, data sources, and implementation for live tracking of equipment, personnel, and incidents.
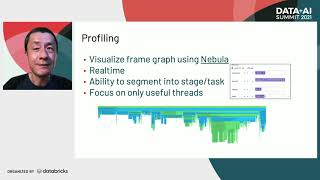
Migrating ETL Workflows to Apache Spark at Scale - Pinterest's Experience
Explore Pinterest's journey migrating ETL workflows to Apache Spark, covering challenges, solutions, and performance improvements. Learn about semantic gaps, thrift objects, and innovative Spark profiling techniques.
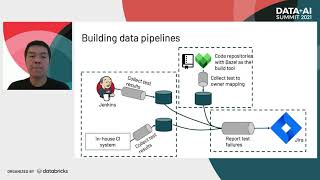
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
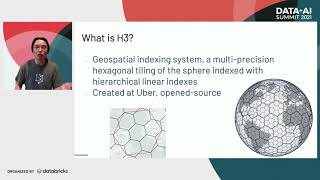
Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
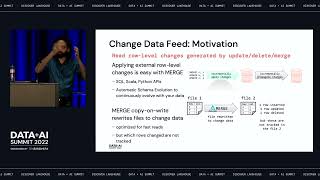
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
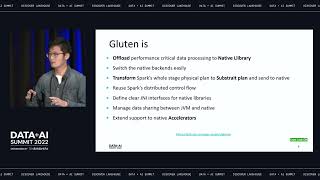
Gazelle-JNI: Offloading Spark SQL to Native Engines for Execution Acceleration
Explore Gazelle-Jni, a middle layer integrating native SQL engines with Spark SQL for accelerated execution through Substrait-transformed physical plan offloading.
Enable Production ML with Databricks Feature Store
Simplify production ML with Databricks Feature Store. Learn to overcome data challenges, enable real-time inference, and streamline ML projects using a unified data lakehouse platform integrated with Apache Spark and MLflow.

Delta Live Tables: Modern Software Engineering for ETL Pipelines
Learn how Delta Live Tables simplifies ETL, enhances data pipeline reliability, and automates tasks. Discover modern software engineering practices for efficient data transformation and improved analytics, data science, and ML outcomes.
Recent Parquet Improvements in Apache Spark - Vectorized Complex Types and Column Index Support
Explore recent improvements in Apache Spark's Parquet performance, including vectorized read support for complex types and column index support, leading to significant speed enhancements and efficient data processing.
Scaling XGBoost for Thousands of Features with Databricks
Scaling XGBoost for online advertising: Learn to handle thousands of features, optimize model training, and avoid common pitfalls in both Python and Scala implementations on Spark.

Discover the Data Lakehouse: Simplifying Data Architecture for Analytics and ML
Explore the data lakehouse architecture for managing massive data, supporting diverse analytics and ML requirements across multi-cloud environments, and enabling data teams to derive value efficiently.
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.