Productionizing Machine Learning Pipelines with Databricks and Azure ML
Jumpstart ML projects with Databricks and Azure ML. Learn to build, track, and deploy production-ready pipelines using tools like MLflow, TensorFlow, and PyTorch for efficient, reproducible data science workflows.
Azure and Databricks Enabling Personalized Customer Experience at CVS Health
Explore how CVS Health leveraged Azure and Databricks to personalize customer experiences, implement machine learning models, and drive business value through data-driven decision-making and experimentation.
The Killer Feature Store - Orchestrating Spark ML Pipelines and MLflow for Production
Explore feature store implementation as an orchestration engine for ML pipeline stages using Spark and MLflow, focusing on deployment management, A/B testing, discovery, and governance.
Benchmarks and How-Tos for Convolutional Neural Networks on HorovodRunner-Enabled Apache Spark Clusters
Explore benchmarks and implementation techniques for distributed deep learning using HorovodRunner on Apache Spark clusters, focusing on CNN tasks and scaling efficiency for both GPU and CPU clusters.
Tuning Machine Learning Models - Scaling, Workflows, and Architecture
Automating and scaling ML model tuning using Hyperopt and Apache Spark. Best practices for workflows, architecture, and optimization in hyperparameter tuning for improved performance and accuracy.
Apache Spark NLP for Healthcare - Building Real-World AI Systems
Explore real-world healthcare AI systems using NLP, covering patient risk prediction, diagnosis automation, and revenue optimization. Learn key considerations for building domain-specific models and scalable ML pipelines.
Zeus - Uber's Highly Scalable Distributed Shuffle as a Service
Explore Uber's Zeus: a highly scalable, distributed shuffle service powering data processing. Learn its architecture, integration with Spark, and performance advantages over traditional external shuffle methods.
Efficient Distributed Hyperparameter Tuning with Apache Spark
Learn to efficiently distribute hyperparameter tuning workloads using Apache Spark, avoiding common pitfalls and optimizing performance. Explore best practices with Hyperopt and joblib-spark for scaling ML model training.
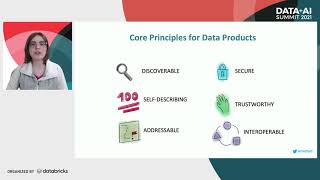
Architect's Open-Source Guide for Data Mesh Architecture
Explore Data Mesh architecture, its principles, benefits, and implementation challenges. Learn about open-source tools like Apache Spark for building effective Data Mesh systems in real-world scenarios.
Monitoring ML Models, IoT Data, and Quality Checks on Delta Lake - Quby's Approach
Discover how Quby monitors IoT data, ML models, and data quality using Databricks. Learn about Delta Lake, MLflow, and Slack integration for efficient data processing and model performance tracking.
Quick to Production: Integrating Spark and TensorFlow for Efficient MLOps
Learn to quickly deploy deep learning models using Spark and TensorFlow, simplifying MLOps for data scientists. Explore distributed computing, feature engineering, and leveraging TensorFlow ecosystem libraries for efficient model production.
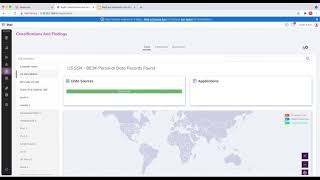
Identifying Sensitive Data and Mitigating Risk in Apache Spark and Databricks
Discover sensitive data in Apache Spark and Databricks using BigID's platform. Learn to scale discovery, label data, and apply necessary guardrails for compliance and risk mitigation in data analytics.
Efficient Scheduling of High Performance Batch Computing for Analytics Workloads with Volcano
Explore how ING uses Volcano scheduler for efficient, multi-tenant large-scale processing in advanced analytics, enabling dynamic allocation and resource fairness for over 300 internal projects.
Training Foundation Model Workloads on Kubernetes at Scale with MCAD
Explore how IBM's Vela supercomputer uses MCAD to queue custom resources for large-scale AI training on Kubernetes, enabling flexible frameworks and fault tolerance across hundreds of GPUs.
Real-Time Event Processing and Handling Stateful Applications on Apache Mesos
Explore real-time event processing and stateful applications on Apache Mesos, focusing on industrial use cases, PaaS journey, and stream processing platforms. Learn from GE Digital's experience in handling complex workloads.
Scala and Spark in the New Deep Learning Era
Explore integrating large language models into big data infrastructures using Apache Spark, Scala, and BigDL. Learn distributed fine-tuning for pre-trained models and their representation as Spark estimators.
Fink on Kubernetes - Efficient Management of Massive Alert Streams for Astronomical Object Identification
Explore how Kubernetes enables real-time processing of massive astronomical data streams, facilitating scientific discoveries through cloud-based infrastructure and distributed computing frameworks.
A Short Summary of the Last Decades of Data Management - GOTO 2024
Explore the evolution of data management over decades, from monolithic systems to open-source engines and cloud computing, examining key trends, successes, and failures in this trillion-dollar industry.
Flare - Optimizing Apache Spark for Scale-Up Architectures and Medium-Size Data
Optimizing Apache Spark for medium-size data on single powerful servers. Flare accelerator module delivers significant speedups using code generation techniques inspired by main-memory database systems.
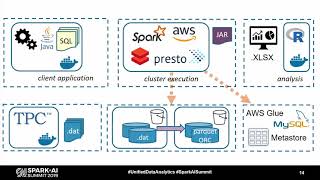
Performance Analysis of Apache Spark and Presto in Cloud Environments
Comparative analysis of Apache Spark and Presto on Amazon EMR, focusing on SQL performance using TPC-DS benchmark. Explores execution times, costs, and optimization techniques to guide big data analytics platform selection.
How Delta Lake with Azure Databricks Can Accelerate Your Big Data Workloads by 100x
Explore advanced Delta Lake features on Azure Databricks for reliable, scalable data lakes. Learn optimizations for analytics and ML workloads, including file compaction, Z-Order partitioning, and unified batch/streaming.