Cloud Migration and Cost Optimization in the Databricks Lakehouse
Revolutionize data environments with Delta Lake and Unity Catalog, achieving cloud migration in under 6 months and 90% cost reduction. Benefit from data lakehouse advantages like time travel and unified governance.
BigQuery Native Integration with Delta Lake - The Latest Announcement
Explore BigQuery's native querying of Delta Lake tables, enhancing data strategy with improved performance and cross-cloud capabilities. Learn about GCP's open platform integrations and interoperability features.
Exploring UDTFs and Polymorphism in PySpark
Learn to create and enhance User-Defined Table Functions in PySpark, including polymorphic UDTFs for flexible data processing. Gain practical insights through examples and expert guidance.
Running Data Applications on Google Kubernetes Engine (GKE) - From Stateless to Stateful Workloads
Discover how Kubernetes has evolved to effectively manage stateful applications, from databases and big data to machine learning workloads on Google Kubernetes Engine.
Molecule Testing for Ansible-Driven Data Lake Deployments on Kubernetes
Master automated data lake deployment workflows using Molecule, Ansible, and Kubernetes. Learn to set up and test multi-node clusters with essential data services like Elasticsearch, JupyterHub, Spark, and Airflow.
Product Recommendation System on Kubernetes Using Argo Workflows
Learn to build a product recommendation system using Argo Workflows on Kubernetes. Explore DataOps, pipelines, and tools like Minio and Apache Spark for efficient data processing and analysis.
Efficient MLOps: Developing and Deploying ML Models with Databricks
Explore efficient MLOps framework design for ML model development and deployment, covering environment management, CI/CD pipelines, and tools like Unity Catalog and MLflow for model monitoring and progression.
Build Open Format Data Lakehouse
Explore open format data lakehouse architecture, benefits, and implementation strategies for efficient cloud-native data management and analytics.
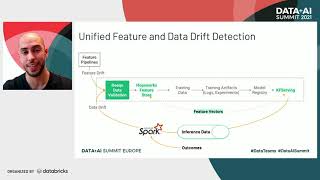
KFServing - Model Monitoring with Apache Spark and Feature Store
Explore an open-source platform for scalable model serving and monitoring using KFServing, Hopsworks Feature Store, and Spark Streaming. Learn continuous data drift detection and see a live demonstration.
Unified MLOps: Feature Stores and Model Deployment
Explore a new MLOps approach merging databases, feature stores, and ML for scalable model production. Learn about Splice Machine's hybrid database and its applications in feature engineering and model deployment.
Machine Learning at Scale with MLflow and Apache Spark
Explore Société Générale's journey in scaling machine learning, focusing on MLflow and Apache Spark for production deployment, CI/CD pipelines, and overcoming challenges in large-scale ML implementation.
Scalable AI for Environmental and Social Impact
Explore Microsoft's AI contributions to Apache Spark and Machine Learning, focusing on environmental and social impact projects like art exploration and endangered species protection.
Tools for Building the Real-Time Organization
Explore tools and architectures for processing real-time data streams, enabling organizations to make faster, better decisions through event-based systems and reactive platforms.
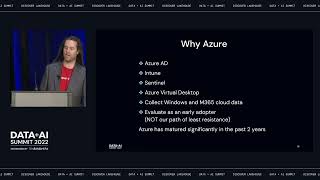
Building a Petabyte-Scale Cybersecurity Data Mesh in Azure with Delta Lake - HSBC Case Study
Explore HSBC's innovative approach to building a petabyte-scale cybersecurity data mesh in Azure, leveraging Delta Lake to address unique challenges and empower analysts with a unified, scalable platform.
Introducing MLflow for End-to-End Machine Learning on Databricks
Learn to predict life expectancy using health data with MLflow. Covers data engineering, exploration, model tuning, and deployment on Databricks' unified analytics platform powered by Apache Spark.
Combining Machine Learning and MLflow with Lakehouse Architecture - Data Brew Episode 5
Explore how Quby leverages ML and MLflow with their lakehouse to extract value from IoT sensor data, moving from batch to real-time streaming for energy optimization and customer insights.
MATS Stack for Cross-System Orchestration of Machine Learning Pipelines
Explore the MATS stack for orchestrating ML pipelines across systems, featuring MLFlow, Airflow, Tensorflow, and Spark. Learn how Avast leverages this approach for efficient phishing detection and streamlined ML workflows.
Spark NLP - State-of-the-Art Natural Language Processing at Scale
Discover scalable NLP techniques using Apache Spark, covering core algorithms, BERT embeddings, and multi-lingual challenges. Learn to build efficient pipelines for various NLP tasks through practical demonstrations.
Data Mesh in Practice - Beyond the Data Lake for Fashion E-Commerce
Explore Zalando's journey from centralized Data Lake to distributed Data Mesh architecture, emphasizing data ownership, quality, and accessibility through decentralized domain-focused approach and Data Products concept.
Taking Machine Learning to Production with MLflow - New Features and Best Practices
Explore MLflow's latest features for productionizing machine learning, including model management, CI/CD, data schemas, and integration with PyTorch for seamless deployment and operation of ML applications.
Introducing MLflow for End-to-End Machine Learning on Databricks
Explore end-to-end machine learning with MLflow on Databricks: from data engineering to model deployment, using health data to predict life expectancy through Spark, hyperopt, and interactive dashboards.