Introduction to Quantization in Cubase - Making MIDI Notes Sound Natural
Master the art of quantization in Cubase to correct and naturalize recorded notes through practical demonstrations and essential techniques for achieving professional-sounding results.
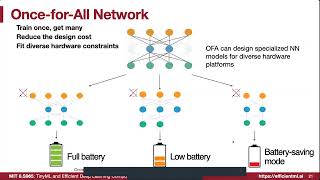
TinyML and Efficient Deep Learning Computing - Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices, covering model compression, pruning, quantization, and more.
TinyML and Efficient Deep Learning Computing - Lecture 24: Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices. Gain hands-on experience with mobile AI and quantum machine learning.
AWQ for LLM Quantization - Efficient Inference Framework for Large Language Models
Explore Activation-aware Weight Quantization (AWQ) for efficient large language model deployment, reducing memory requirements while preserving performance across domains and modalities.
Compressing Large Language Models (LLMs) with Python Code - 3 Techniques
Explore three LLM compression techniques: quantization, pruning, and knowledge distillation. Learn to implement these methods with Python code examples for efficient model optimization.
Quantum Theory of Light - Operator Approach to Solving Harmonic Oscillator Problem
Explore the operator approach to solving quantum harmonic oscillator problems in the context of quantum theory of light.
MLOps: Logging and Loading Microsoft Phi3 Mini 128k in GGUF with MLflow
Learn to log and load quantized LLama.cpp models in MLflow, create Python classes, and perform inference using Microsoft Phi3 mini 128k in GGUF format.
How to Quantize a Large Language Model with GGUF or AWQ
Learn to quantize large language models using GGUF and AWQ. Explore techniques, compare methods, and gain practical skills for efficient model compression and deployment.
Quant-LLM: Accelerating Large Language Model Serving via FP6-Centric Algorithm-System Co-Design
Innovative GPU kernel design enables efficient 6-bit quantization for large language models, significantly improving inference speed while maintaining quality across various applications.
Inside TensorFlow - TF Model Optimization Toolkit - Quantization and Pruning
Explore TensorFlow's Model Optimization Toolkit, focusing on quantization and pruning techniques to enhance model efficiency and performance in deep learning applications.
TensorFlow Model Optimization - Quantization and Pruning
Explore TensorFlow model optimization techniques like quantization and pruning to enhance performance, reduce resource usage, and improve efficiency in machine learning applications.
Advanced Quantization Techniques in Logic Pro - Lesson 43
Master advanced quantization techniques in Logic Pro, from region and event-based editing to complex tuplets, swing grooves, and Q parameters for precise MIDI control and rhythm manipulation.
Memory Optimization Techniques for On-Device Large Language Models
Discover advanced memory optimization techniques for deploying large language models on devices with limited resources, focusing on key-value caching and dynamic compression methods.
Deploying GenAI on Edge Devices with ExecuTorch - Technical Overview
Discover how to deploy machine learning models on edge devices using ExecuTorch, featuring insights on memory optimization, hardware compatibility, and efficient model conversion techniques.
Unlocking Local LLMs with Quantization
Discover how quantization optimizes LLMs for local deployment, from pre-training techniques to fine-tuning methods and inference optimization using cutting-edge approaches and community tools.
Fine-Tuning Self-Rewarding Language Models with Mistral 7B
Dive into implementing Meta's Self-Rewarding Language Model with Mistral 7B, covering fine-tuning techniques, data preparation, prompt generation, and practical demonstrations.
Understanding 1-Bit Large Language Models - From Theory to Implementation
Dive into the revolutionary concept of 1-bit Large Language Models, exploring how weights can be represented with simple integers (0, 1, -1) instead of complex floating-point numbers.
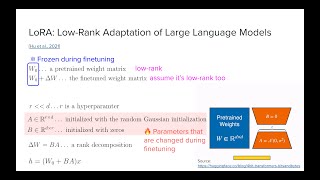
Parameter-Efficient Finetuning - QLoRA and LoRA Methods
Explore parameter-efficient fine-tuning techniques with LoRA and QLoRA, learning how to optimize large language models while maintaining performance and reducing computational costs.
Leveraging Vector Databases for Advanced Search
Dive into vector databases, embedding techniques, and advanced search algorithms, exploring AWS solutions for implementing efficient vector-based search systems and quantization methods.
AI Model Efficiency Toolkit (AIMET) - Lecture 25
Explore AI model efficiency techniques with Qualcomm's toolkit. Learn about adaptive rounding, autocon, and transformer quantization for optimized inference and training on resource-constrained devices.
AI Model Efficiency Toolkit (AIMET) - Lecture 25
Explore AI model efficiency techniques with Qualcomm AI Research. Learn about AIMET, community research, core technologies, and industry applications for optimizing deep learning models.