QLoRA - How to Fine-tune an LLM on a Single GPU with Python Code
Learn to fine-tune large language models on a single GPU using QLoRA. Explore quantization techniques, LoRA, and practical implementation with Python code for custom YouTube comment responses.
The Era of 1-bit LLMs Explained - BitNet b1.58 and New Scaling Laws
Explore groundbreaking research on BitNet b1.58, a ternary parameter model matching full-precision Transformers while offering improved cost-effectiveness and defining new LLM scaling laws.
8-bit Methods for Efficient Deep Learning
Explore 8-bit methods for efficient deep learning, focusing on quantization techniques, optimizers, and inference for large language models to improve efficiency without performance loss.
DGEMM on Integer Tensor Cores - NHR Perflab Seminar
Explore double-precision matrix multiplication using Int8 Tensor Cores and the Ozaki scheme, focusing on high-precision computation with lower-precision hardware for machine learning applications.
Pruning and Quantizing ML Models With One Shot Without Retraining
Adapt advanced pruning and quantization methods for ML models, achieving 4X speedup with 99% accuracy in minutes, using Computer Vision and NLP examples.
Unlock Faster and More Efficient LLMs with SparseGPT - Neural Magic
Optimize LLMs with SparseGPT: prune and quantize models for efficient CPU deployment at GPU speeds. Explore one-shot compression, benchmarks, and practical implementation.
Deploy Fast and Accurate YOLOv8 Object Detection Models on CPUs
Optimize YOLOv8 models for 10x smaller, 8x faster performance on CPUs. Learn sparsification techniques, quantization, and deployment strategies for efficient computer vision applications.
Deploy LLMs More Efficiently with vLLM and Neural Magic
Explore vLLM's efficiency for LLM deployment and Neural Magic's enterprise solutions for cost-effective, scalable AI model services.
Serve a Custom LLM for Over 100 Customers - GPU Selection, Quantization, and API Setup
Learn to deploy and serve custom LLMs efficiently for multiple customers. Master server selection, API software, GPU optimization, and quantization techniques for cost-effective, high-performance model serving.
What's in a Vector Database? - Understanding Vector Storage and AI Integration
Explore vector databases' unique features, including indexing, hybrid searches, and AI integration. Learn how they differ from traditional databases and their role in modern AI applications.
Koszul Duality on Quantizations of Bionic Symplectic Varieties
Explore Koszul duality in quantizations of bionic symplectic varieties, focusing on localization theorems, DQ-modules, and geometric category O. Gain insights into recent advancements in filtered Koszul duality.
Neural Architecture Search (Part II) - Lecture 8
Explore neural architecture search techniques, including hardware-aware approaches and joint optimization of hardware and neural architectures. Learn applications and advancements in efficient deep learning design.
Quantization in Neural Networks - Lecture 5
Explore neural network quantization, including numeric data types, K-means-based quantization, and linear quantization for efficient deep learning on resource-constrained devices.
Neural Architecture Search for Efficient Deep Learning - Lecture 9
Explore advanced neural architecture search techniques for efficient deep learning on resource-constrained devices. Gain insights into model optimization for mobile and IoT applications.
Neural Architecture Search (Part II) - Lecture 8
Explore neural architecture search techniques, including hardware-aware approaches and joint optimization of hardware and neural architectures. Learn applications and advancements in efficient deep learning design.
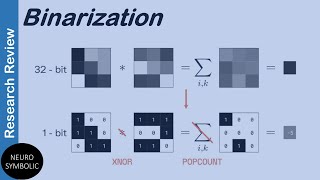
Introduction to Binarized Neural Networks
Explore binarized neural networks: motivation, quantization benefits, core concepts, training methods, and recent developments in this cutting-edge AI field.
How to Pick a GPU and Inference Engine for Large Language Models
Explore GPU selection and inference engine optimization for large language models. Compare quantization effects, software options, and cost-efficiency across various GPUs and model sizes.
Knizhnik-Zamolodchikov from Quantum Isomonodromy
Explore quantum isomonodromy and its connection to Knizhnik-Zamolodchikov equations in moduli space quantization.
From the A2 Quiver Towards the Painlevé I T Function
Explore quantisation of moduli spaces through the A2 quiver and Painlevé I T function, gaining insights into advanced mathematical concepts.
Heun Connection Matrix from Liouville Conormal Blocks and Darboux Theorem
Explore the Heun connection matrix, Liouville conormal blocks, and Darboux theorem in the context of quantizing moduli spaces.
Multi-GPU Fine-tuning with DDP and FSDP
Master multi-GPU fine-tuning techniques using DDP and FSDP. Explore VRAM optimization, distributed training strategies, and practical implementation with code examples and demos.