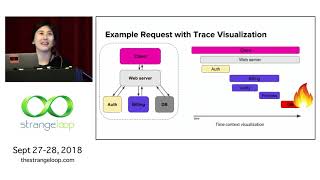
Understanding Microservices with Distributed Tracing
Explore distributed tracing for microservices: visualize request journeys, optimize performance, and gain system-wide insights. Learn implementation strategies and lessons from Lyft's adoption.
Everything You Wanted to Know About Distributed Tracing
Explore distributed tracing in microservices: concepts, implementation patterns, and troubleshooting techniques. Learn about OpenTelemetry and its benefits for modern, polyglot environments.
Observability for Emerging Infra - What Got You Here Won't Get You There
Explore modern infrastructure challenges and the shift from traditional monitoring to observability. Learn about event-driven approaches, complexity management, and the future of debugging distributed systems.
Why Kubernetes is Not Enough
Explore Farfetch's journey in migrating 500 microservices to Kubernetes, focusing on the creation of blueprints to manage service metadata and dependencies for improved agility and control.
Application Diagnostics in .NET Core 3.1
Explore advanced techniques for diagnosing and resolving issues in .NET Core 3.1 applications, including new APIs, command-line tools, and Visual Studio features for efficient troubleshooting and performance optimization.

Cultivating Production Excellence
Explore practices for managing complex distributed systems, including collaborative observability, Service Level Objectives, and risk analysis to enhance production excellence.
Navigating Microservices with .NET Core
Explore microservices and Kubernetes from a .NET Core perspective, covering key concepts, demos, and future trends in distributed systems architecture.
Asynchronous Distributed Systems
Explore microservice architectures, comparing synchronous and asynchronous models. Learn patterns like CQRS and Event Sourcing, and strategies for evolving systems towards asynchronous communication.
Distributed Tracing - How the Pros Debug Concurrent and Distributed Systems
Explore OpenTracing and Zipkin for debugging distributed systems. Learn to instrument applications, visualize operations across services, and enhance performance analysis in microservice architectures.
Distributed Tracing and Monitoring with OpenCensus
Explore distributed tracing and monitoring using OpenCensus, covering core concepts, implementation, and integration with various systems for enhanced cloud service observability.
Deploying SRE Training Best Practices to Production - What We Learned
Explore best practices for SRE training, including sequential learning, hands-on experiences, and continuous education. Learn from Google's insights on building effective SRE teams and fostering a culture of reliability.
Hunting for Risky Dependencies in the World of Microservices
Discover how to identify and mitigate hidden vulnerabilities in microservice architectures using OpenTelemetry, with real-world examples from Google Maps' high-risk dependencies.
Designing Resilient Data Pipelines
Strategies for resilient data pipelines: observability, immutable inputs, declarative pipelines, and data validation. Reduce operational complexity, update risks, and accuracy concerns in complex systems.
Optimizing for Learning
Explore cognitive science techniques to enhance SRE learning, incident response, and team collaboration. Optimize human observability for better system understanding and problem-solving.
Tracing Bare Metal with OpenTelemetry
Explore how Equinix Metal implemented OpenTelemetry tracing for bare metal provisioning, improving debugging and reliability across their global infrastructure.
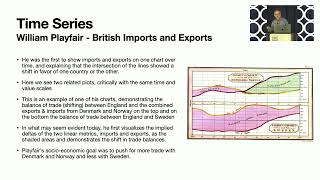
Improving How We Observe Our Observability Data - Techniques for SREs
Explore techniques to enhance observability data visualization for SREs, including multivariate relationships, small multiples, and sparklines, while avoiding common pitfalls in engineering presentations.
EBPF - The Next Power Tool of SREs
Explore eBPF, a revolutionary Linux kernel technology for infrastructure observation and protection. Learn its capabilities, use cases, and implementation for enhanced system reliability and security.
Evolution of Observability Tools at Pinterest
Explore Pinterest's journey in scaling observability tools, from metrics to log search and distributed tracing, as the company grew from startup to web-scale platform.
Are We All on the Same Page? Let's Fix That
Explore Adaptive Paging, an innovative alert handler that uses tracing and heuristics to identify and notify the team closest to the problem, reducing alert fatigue in complex distributed systems.
Tracing Real-Time Distributed Systems
Exploring distributed tracing in real-time data streaming systems, focusing on challenges and solutions for trading platforms, including session tracking, data flow management, and storage optimization.
Off the Beaten Path - Moving Observability Focus from Your Service to Your Customer
Explore shifting observability focus to customer experience, enhancing service reliability through direct engagement, innovative tools, and rethinking performance metrics for improved user satisfaction.