LLM Post-Training Techniques - Lecture 14
Dive into advanced LLM post-training techniques and deployment strategies, exploring optimization methods and practical implementation approaches for efficient language model deployment.
On-Device Training and Transfer Learning - Lecture 15
Explore on-device training and transfer learning techniques, focusing on memory bottlenecks, efficient algorithms like TinyTL, and system support for optimized on-device training.
On-Device Training and Transfer Learning - Lecture 15
Explore on-device training and transfer learning techniques, focusing on memory bottlenecks, efficient algorithms like TinyTL, and system support for optimized on-device training.
TinyEngine - Efficient Training and Inference on Microcontrollers - Lecture 17
Explore TinyEngine library for efficient neural network training and inference on microcontrollers. Learn techniques to optimize deep learning for resource-constrained devices.
Efficient Video Understanding and Generative Models - Lecture 19
Explore efficient video understanding and generative models, focusing on techniques for deploying neural networks on resource-constrained devices and optimizing deep learning applications.
Efficient Video Understanding and Generative Models - Lecture 19
Explore efficient video understanding and generative models, focusing on techniques for deploying neural networks on resource-constrained devices and optimizing deep learning applications.
Pruning and Sparsity in Machine Learning - Part II - Lecture 4
Explore advanced pruning techniques and sparsity concepts for efficient machine learning, focusing on practical applications and cutting-edge research in neural network optimization.
Quantization for Efficient Machine Learning - Part II
Explore advanced quantization techniques for efficient machine learning, including post-training and quantization-aware training methods.
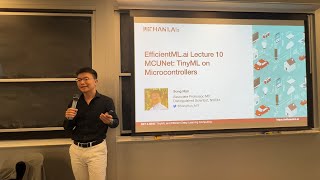
MCUNet: TinyML on Microcontrollers - Lecture 10
Explore MCUNet for TinyML on microcontrollers, covering efficient neural architecture design and deployment strategies for resource-constrained devices.
EfficientML.ai: Introduction to Efficient Machine Learning - Lecture 1
Explore efficient machine learning techniques and their applications in this introductory lecture from MIT's EfficientML course.
EfficientML.ai: Introduction to Efficient Machine Learning - Lecture 1
Explore efficient machine learning techniques and their applications in this comprehensive introduction to EfficientML.ai from MIT's Prof. Song Han.
Pruning and Sparsity in Machine Learning - Part II - Lecture 4
Explore advanced pruning techniques and sparsity concepts for efficient machine learning, focusing on practical applications and cutting-edge research in neural network optimization.
Pruning and Sparsity in Machine Learning - Part II - Lecture 4
Explore advanced pruning techniques and sparsity concepts for efficient machine learning, focusing on practical applications and cutting-edge research.
EfficientML.ai - Quantization Part I - Lecture 5
Explore quantization techniques for efficient machine learning, covering fundamental concepts and practical applications in neural network optimization.
EfficientML.ai - Quantization Part I - Lecture 5
Explore quantization techniques for efficient machine learning, covering fundamental concepts and practical applications in neural network optimization.
EfficientML.ai - Quantization Part II - Lecture 6
Explore advanced quantization techniques for efficient machine learning, including post-training and quantization-aware training methods.
EfficientML.ai: Quantization Part II - Lecture 6
Explore advanced quantization techniques for efficient machine learning, covering post-training and quantization-aware training methods to optimize model performance.
Neural Architecture Search Part II - Lecture 8
Explore advanced neural architecture search techniques, including evolutionary algorithms and reinforcement learning, to optimize deep learning models for efficiency and performance.
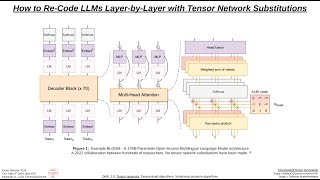
How to Re-Code LLMs Layer by Layer with Tensor Network Substitutions
Explore strategies for recoding Large Language Models using tensor network substitutions to enhance explainability, compression, and performance on smaller devices.
The Emergence of Essential Sparsity in Large Pre-trained Models
Explore essential sparsity in large pre-trained models, examining efficient handling of complex transformers and the impact of weight removal on performance.
Distill Whisper Explained - Robust Knowledge Distillation for Speech Recognition
Explore Distill-Whisper: a compact, efficient speech recognition model. Learn about its robust knowledge distillation, large-scale pseudo labelling, and performance compared to the larger Whisper model.