Compressing Large Language Models (LLMs) with Python Code - 3 Techniques
Explore three LLM compression techniques: quantization, pruning, and knowledge distillation. Learn to implement these methods with Python code examples for efficient model optimization.

Llama 3.2 - Multimodal and Edge Computing Advancements
Explore Llama 3.2's multimodal capabilities, edge computing potential, and performance benchmarks. Learn about its vision-tuned models, lightweight versions, and integration with Ollama.
How to Quantize a Large Language Model with GGUF or AWQ
Learn to quantize large language models using GGUF and AWQ. Explore techniques, compare methods, and gain practical skills for efficient model compression and deployment.
Quant-LLM: Accelerating Large Language Model Serving via FP6-Centric Algorithm-System Co-Design
Innovative GPU kernel design enables efficient 6-bit quantization for large language models, significantly improving inference speed while maintaining quality across various applications.
Composable Interventions for Language Models
Explore composable interventions for language models, enhancing accuracy and mitigating harmful outputs. Learn about interactions between different intervention types and their practical implications.
Memory Optimization Techniques for On-Device Large Language Models
Discover advanced memory optimization techniques for deploying large language models on devices with limited resources, focusing on key-value caching and dynamic compression methods.
Unlocking Local LLMs with Quantization
Discover how quantization optimizes LLMs for local deployment, from pre-training techniques to fine-tuning methods and inference optimization using cutting-edge approaches and community tools.
Understanding 1-Bit Large Language Models - From Theory to Implementation
Dive into the revolutionary concept of 1-bit Large Language Models, exploring how weights can be represented with simple integers (0, 1, -1) instead of complex floating-point numbers.
OpenAI Model Distillation and Evals Explained
Explore OpenAI's model distillation techniques and evaluation methods for enhanced AI understanding and implementation.
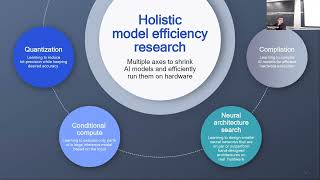
AI Model Efficiency Toolkit (AIMET) - Lecture 25
Explore AI model efficiency techniques with Qualcomm's toolkit. Learn about adaptive rounding, autocon, and transformer quantization for optimized inference and training on resource-constrained devices.
AI Model Efficiency Toolkit (AIMET) - Lecture 25
Explore AI model efficiency techniques with Qualcomm AI Research. Learn about AIMET, community research, core technologies, and industry applications for optimizing deep learning models.
Pruning and Sparsity in Machine Learning - Part I
Explore pruning and sparsity techniques in machine learning, focusing on improving model efficiency without sacrificing performance. Learn key concepts and practical applications.
SliceGPT Explained - Compressing Large Language Models
Explore SliceGPT's innovative approach to compressing large language models by deleting rows and columns, maintaining high performance while reducing parameters significantly.
The Era of 1-bit LLMs Explained - BitNet b1.58 and New Scaling Laws
Explore groundbreaking research on BitNet b1.58, a ternary parameter model matching full-precision Transformers while offering improved cost-effectiveness and defining new LLM scaling laws.
LLM Quantization: Why Size Matters
Explore LLM quantization techniques, their impact on model size, and practical applications in training, fine-tuning, and inference. Gain insights into scaling laws and optimization strategies.
How Well Do Sparse Models Transfer? - Exploring Transfer Performance in Computer Vision and NLP
Explore sparse models' transfer performance and efficiency gains in image and language tasks, outperforming dense models even at high sparsities.
Sparse Training of Neural Networks Using AC/DC
Explore AC/DC, a novel sparse training algorithm for DNNs. Learn its benefits, implementation, and deployment for improved performance and accuracy in deep learning.
Applying Second-Order Pruning Algorithms for SOTA Model Compression
Explore second-order pruning algorithms for model compression, achieving higher sparsity while maintaining accuracy. Learn to apply these techniques to your ML projects for improved efficiency.
Pruning and Quantizing ML Models With One Shot Without Retraining
Adapt advanced pruning and quantization methods for ML models, achieving 4X speedup with 99% accuracy in minutes, using Computer Vision and NLP examples.
Unlock Faster and More Efficient LLMs with SparseGPT - Neural Magic
Optimize LLMs with SparseGPT: prune and quantize models for efficient CPU deployment at GPU speeds. Explore one-shot compression, benchmarks, and practical implementation.
Efficient AI: From Supercomputers to Smartphones
Explore techniques for efficient AI training and inference, from data ingestion to model compression, enabling powerful models on supercomputers and smartphones.